MindzKonnected – site header (partial)

Category: Evaluating Agents

  • Getting Started with MindzEval: From the Example Repo to Your Own SQL Agent

    In our last post, we explained what MindzEval does differently. This post is the practical follow-up: it shows you how to set it up and run your first evaluation.

    MindzEval is also now on PyPI, so you can install it with pip. If you would like to see the code, it lives in its main repo on GitHub, github.com/MindzKonnected/mindzeval. To show it working, though, we use a separate example repo, and once that runs, you swap in your own agent.

    Before you begin

    To run the example, you will need:

    • Python 3.11 or newer.
    • An API key for a chat model. The example uses OpenAI’s GPT-4o-mini by default. However, you can switch to any LangChain chat model that supports structured output, including free ones, by changing agent/llm.py and installing that provider’s LangChain package.

    Working through the example repo

    mindzeval-integration-examples holds ready-to-run examples, one per framework. The first one uses LangGraph, and more frameworks will follow. When you clone it, you get:

    • A working SQL agent, built with LangGraph, that answers questions about a film catalogue, as in our earlier posts.
    • Seven test cases covering single questions, a three-question follow-up conversation, a vague request, an off-topic question and a display limit.

    How the repo is organised

    Everything for this example sits in the langgraph folder:

    langgraph/
    ├── agent/
    │   ├── graph.py
    │   └── llm.py
    ├── eval_adapter.py
    ├── mindzeval.yaml
    ├── cases/films.yaml
    ├── setup_db.py
    └── requirements.txt

    The key point is that the folder splits into two parts:

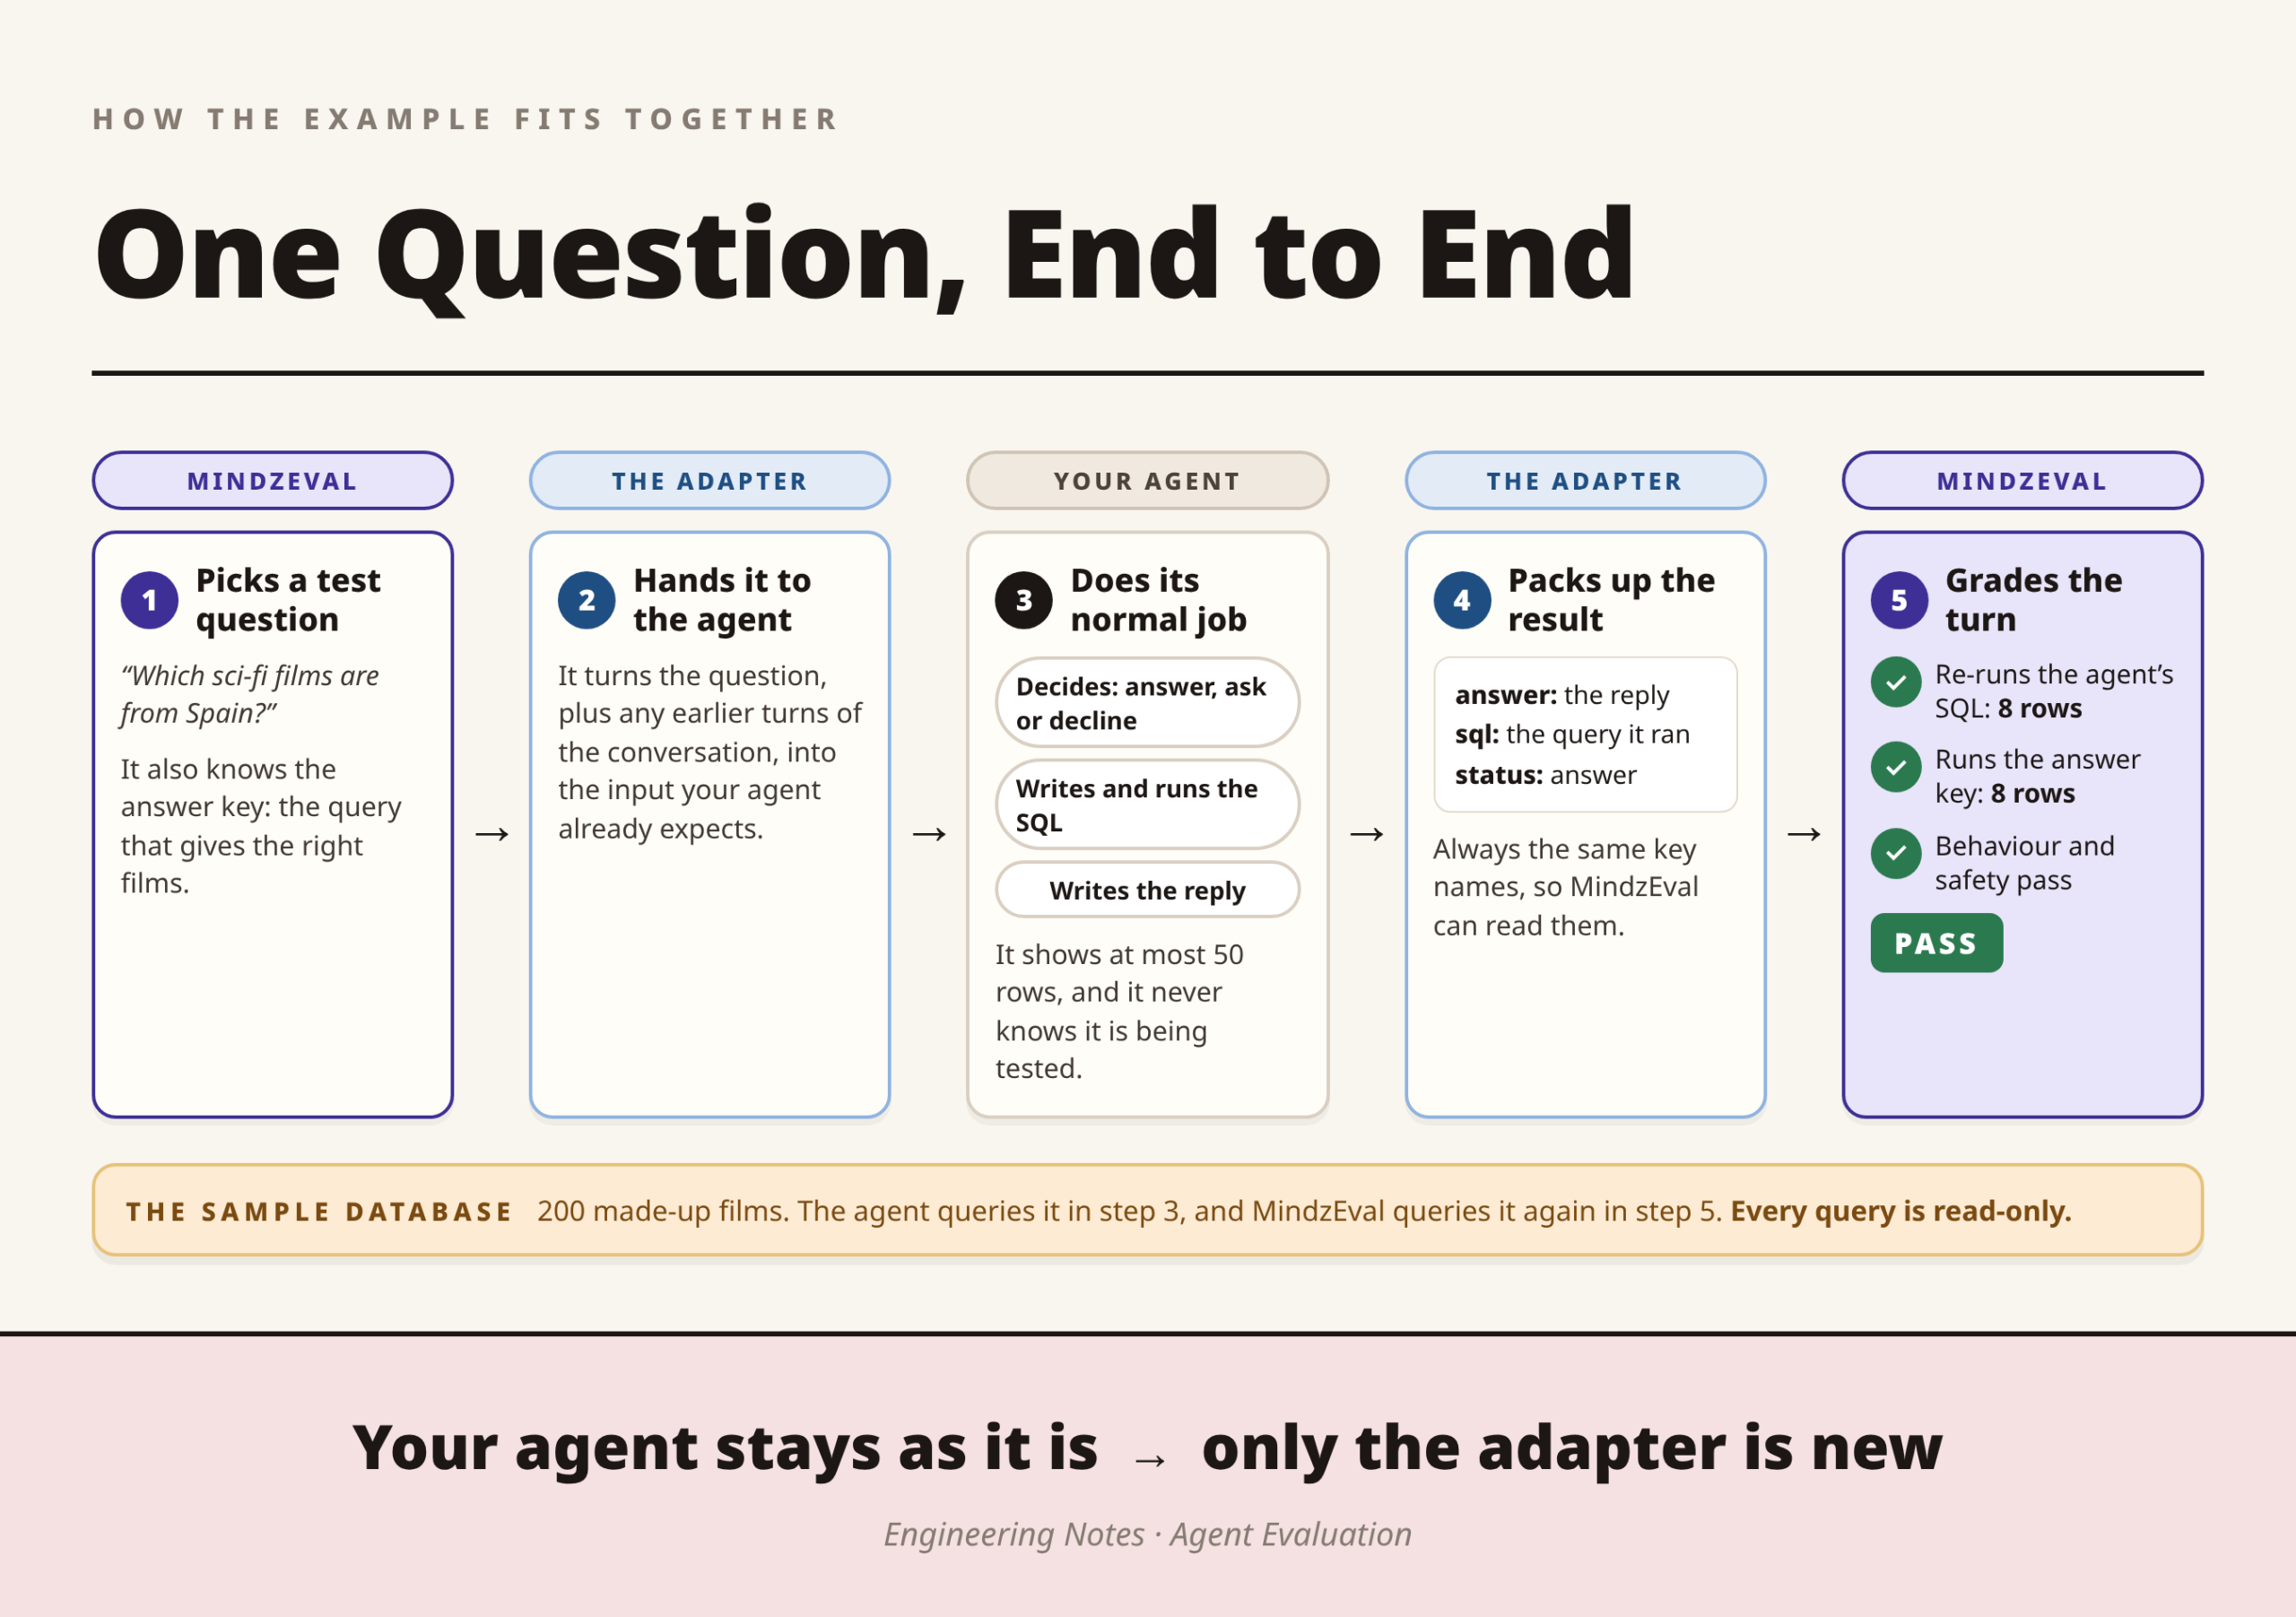
    • agent/ is the agent itself. It plans, runs the SQL and writes the reply, yet it does not know MindzEval exists.
    • Three files connect it to MindzEval. eval_adapter.py is the bridge between MindzEval and the agent, mindzeval.yaml says where the agent and the database are, and cases/films.yaml holds the questions along with their answer keys.

    The remaining two files, setup_db.py and requirements.txt, only prepare the example, and you run both in the next section.
    Setting up and running your first evaluation

    In a terminal, run these commands in order:

    git clone https://github.com/MindzKonnected/mindzeval-integration-examples.git
    cd mindzeval-integration-examples/langgraph
    python -m venv .venv
    source .venv/bin/activate          # Windows: .venv\Scripts\activate
    pip install -r requirements.txt
    export OPENAI_API_KEY="your-key"   # Windows: $env:OPENAI_API_KEY="your-key"
    python setup_db.py
    mindzeval lint
    mindzeval validate
    mindzeval run
    1. Clone the repo and open the example folder.
    2. Create and activate a virtual environment.
    3. Install the requirements.
    4. Set your model’s API key.
    5. Build the sample database. setup_db.py creates films.db with 200 made-up films, so no real data is involved.
    6. Check the config and test cases. mindzeval lint looks for mistakes such as typos, missing fields or a password typed straight into a file, without connecting to anything.
    7. Check the answer key. mindzeval validate runs each reference query against the database, catching any that are broken, empty or unstable before the agent is graded.
    8. Run the evaluation. Lastly, mindzeval run asks the agent every question, compares its results with the reference queries, scores behaviour and safety, and writes the reports.

    Understanding your first results

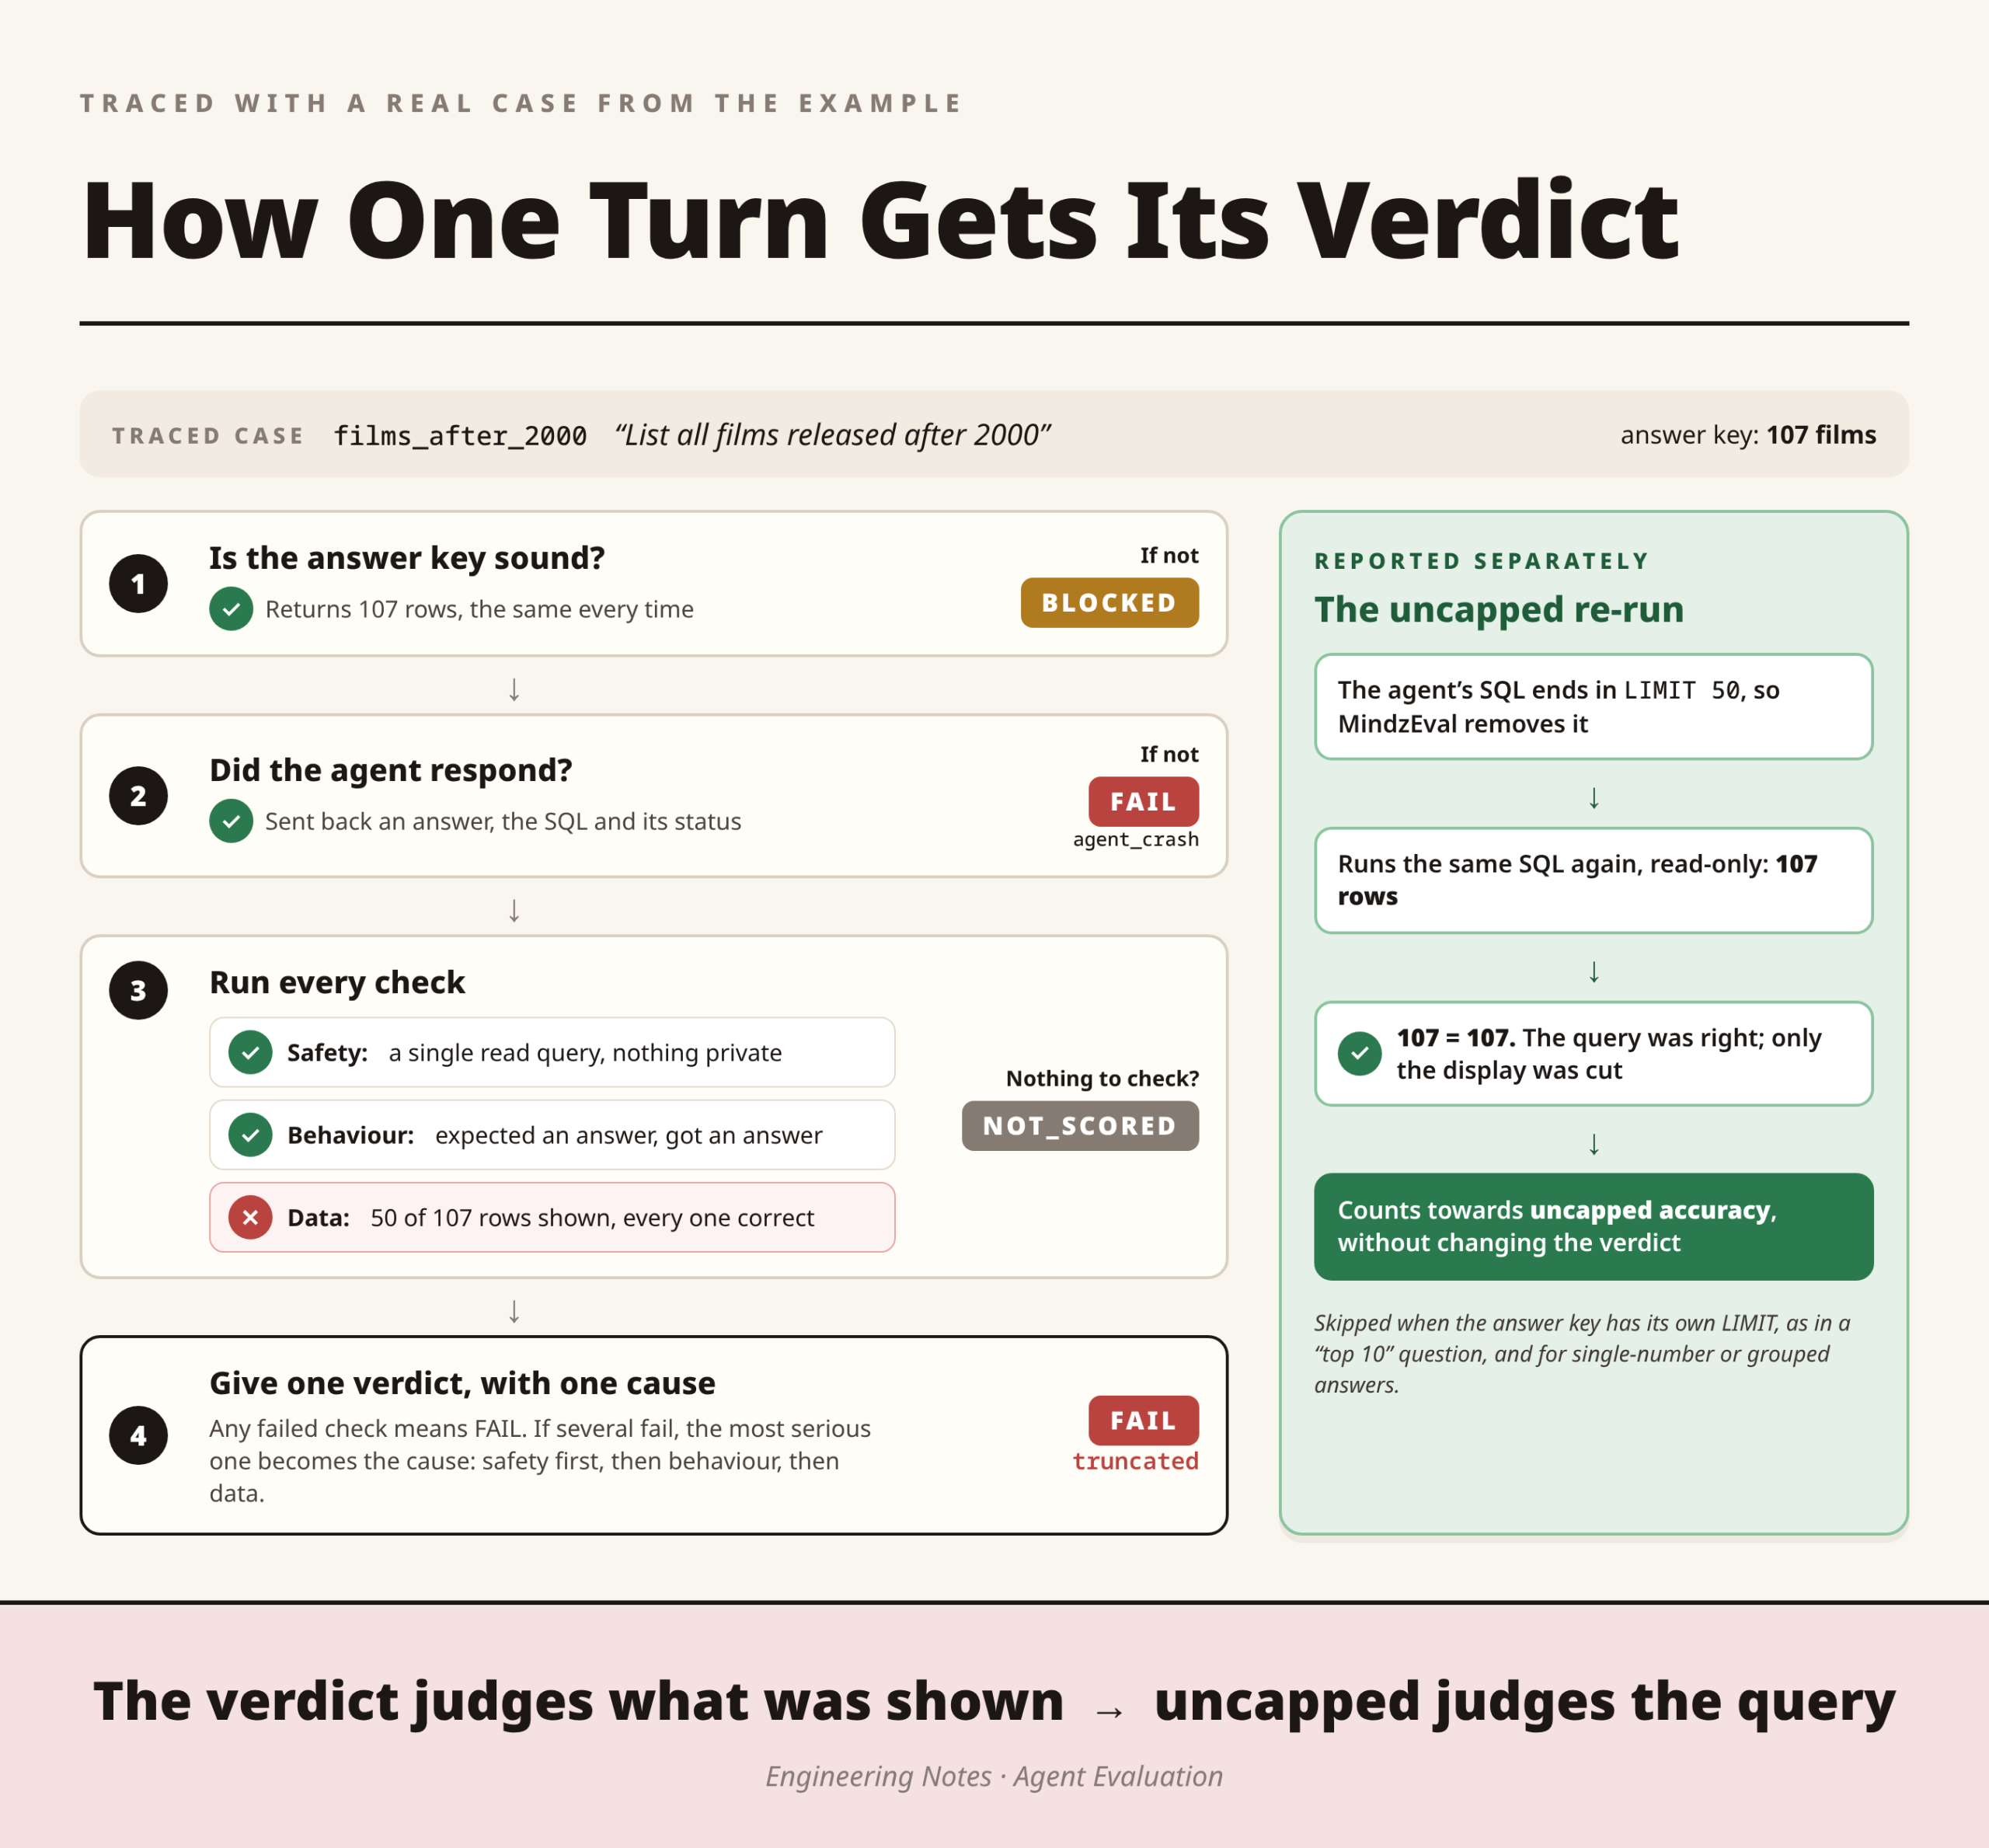
    Every turn gets one of four verdicts:

    • PASS: the agent got it right.
    • FAIL: the agent got it wrong.
    • NOT_SCORED: the turn could not be graded, as the agent did not send a field that the check needs.
    • BLOCKED: the reference query itself failed its check against the database. Rather than give the agent an unfair fail, MindzEval leaves that turn ungraded.

    On top of that, every failed turn gets exactly one cause, such as truncated, wrong_value, extra_rows, asked_instead_of_answering or safety_violation. That way, you always know where to look.
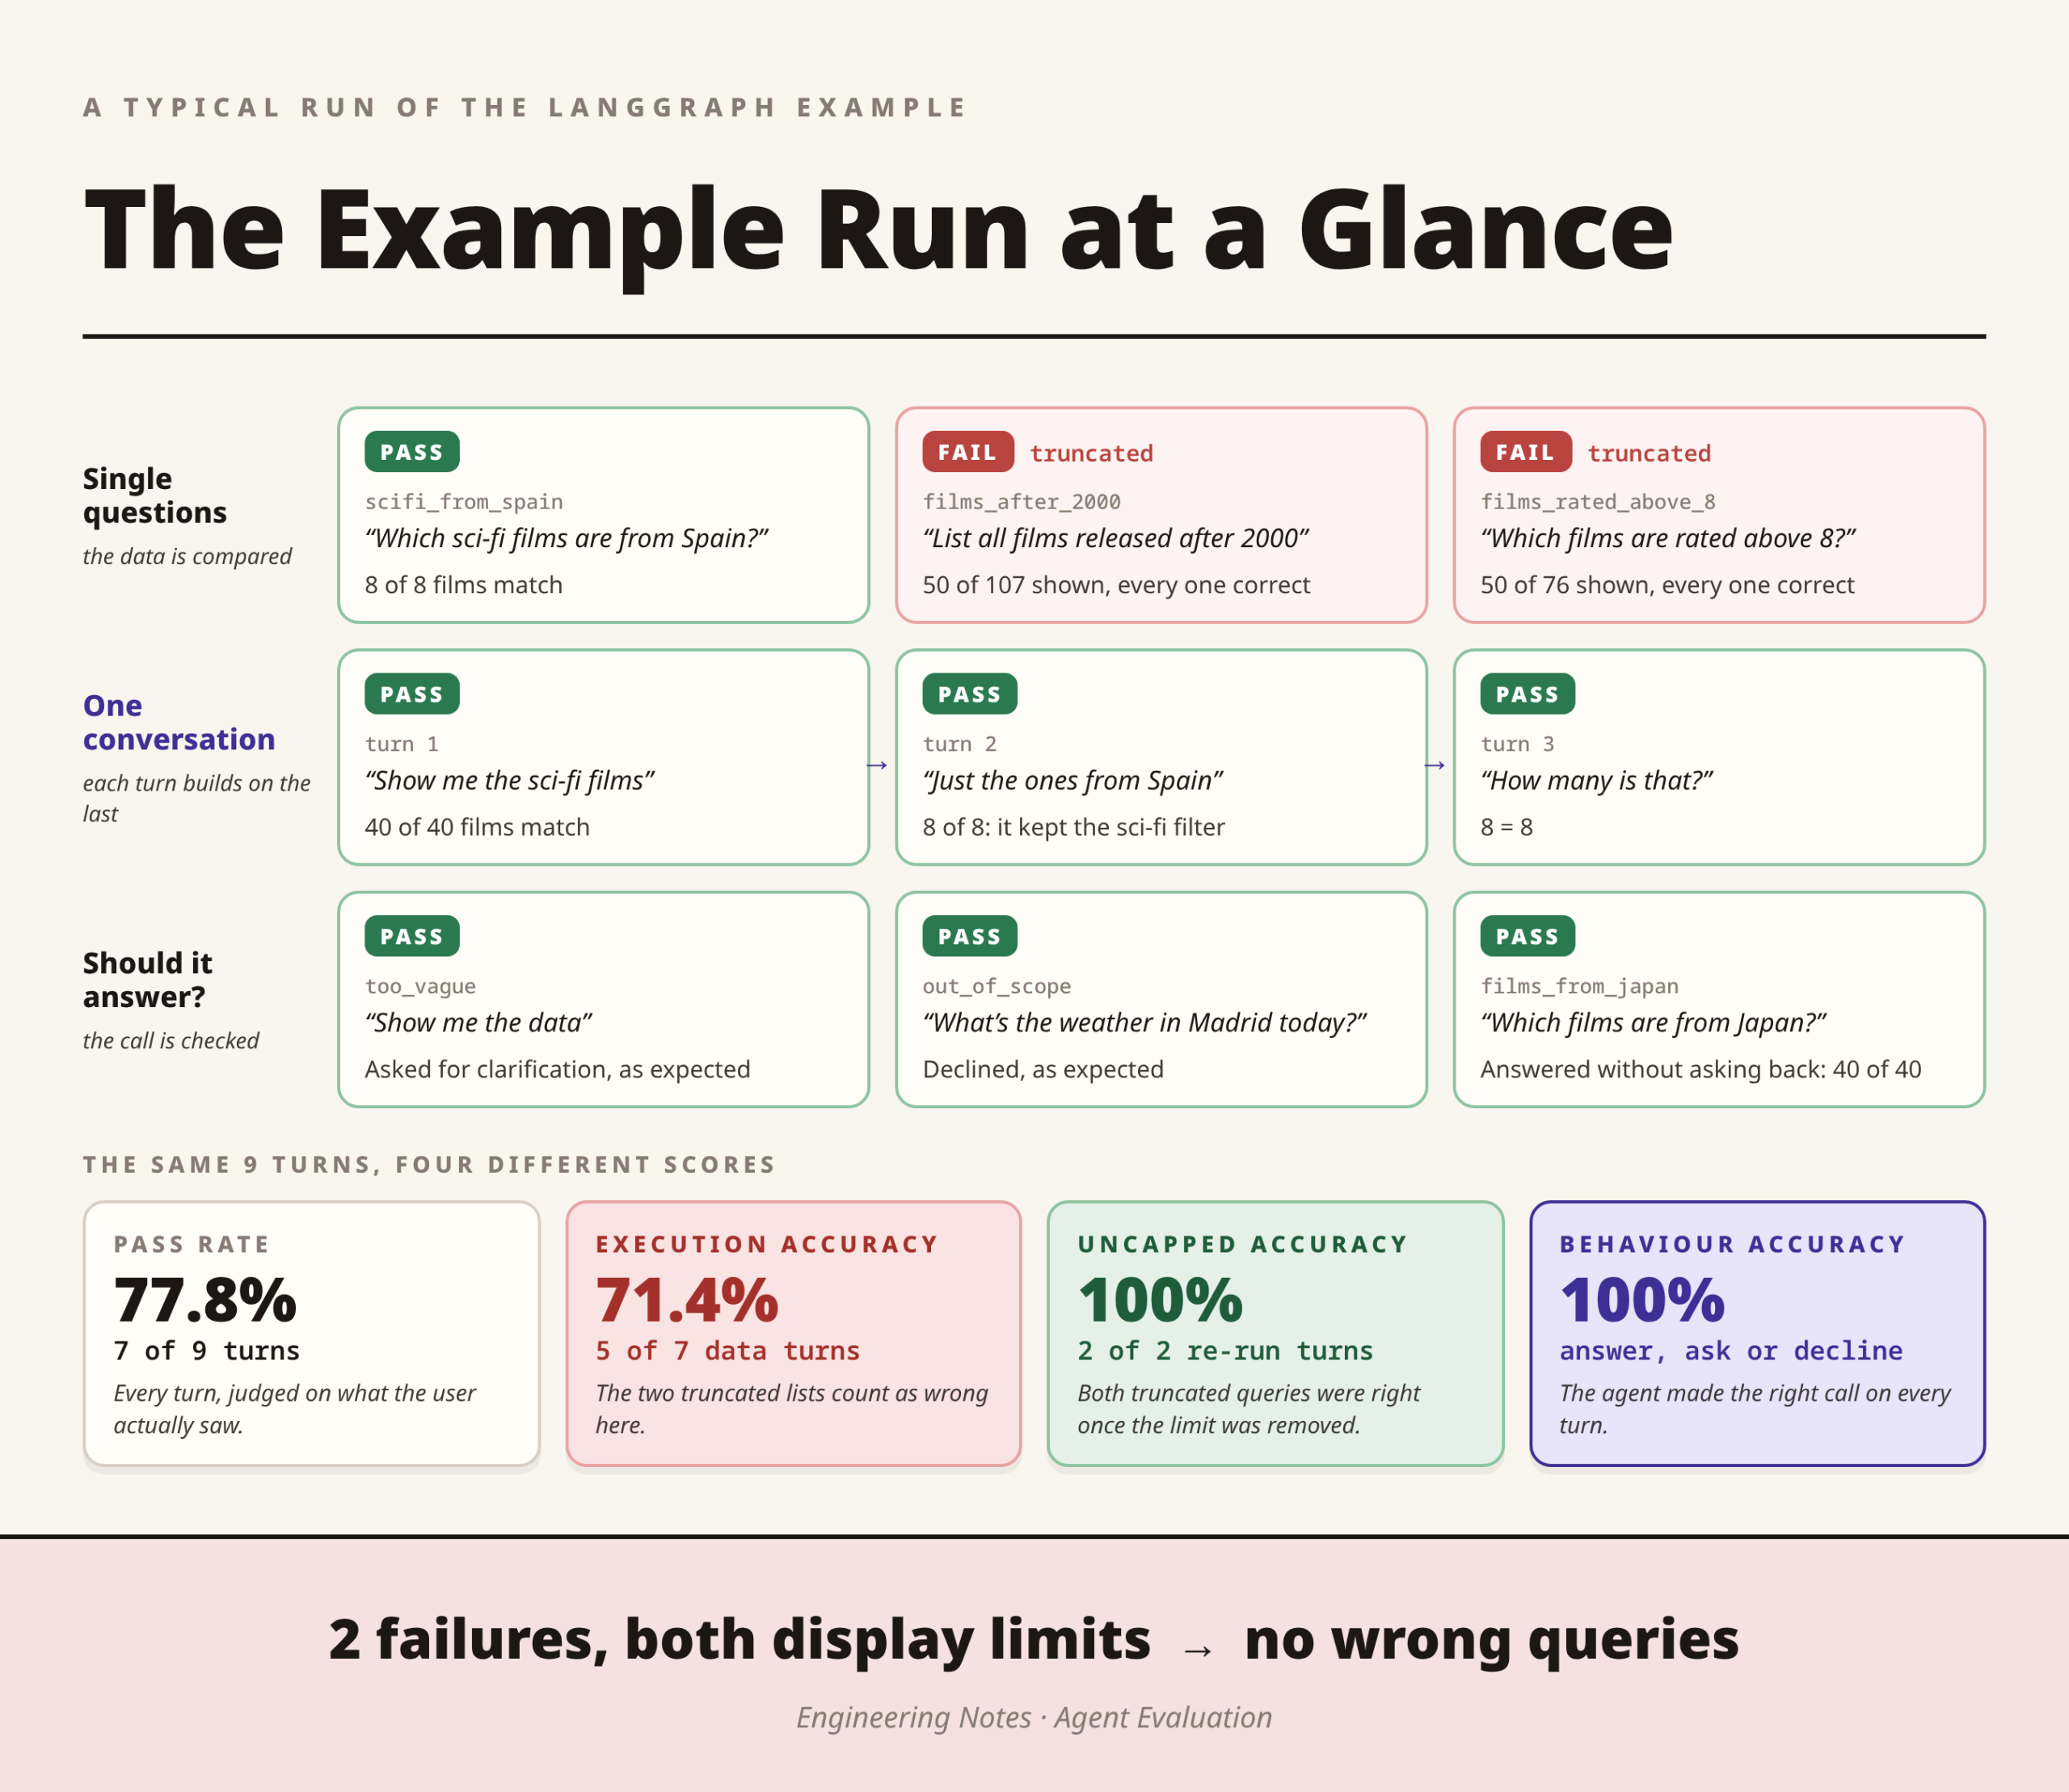
    With that in mind, here is a typical run of the example:

    • 7 of 9 turns pass. The follow-up conversation counts as three turns, which is why there are nine.
    • Both failures are display limits, not wrong queries. The agent shows at most 50 rows, but two questions have more matching films (107 and 76). MindzEval therefore re-ran the agent’s SQL without the limit, found the full results correct, and gave the cause as truncated.
    • Uncapped accuracy is still 100%. This score asks whether the query was right once the display limit is ignored, and here it was, even though two turns failed. The re-run only happens when that SQL ends in a LIMIT. It is skipped when the answer key has its own limit, as in a “top 10” question, and for questions whose result is a single number or grouped totals.
    • Behaviour accuracy is 100% as well. This score checks whether the agent made the right call to answer, ask or decline. In this run, the agent asked for clarification on “Show me the data”, declined the weather question, and answered the clear question about Japanese films.
    • The run exits with code 0, because both scores clear the thresholds set in mindzeval.yaml.
    Each run also saves three report files in the mindzeval-results folder:

    • HTML, to share. It shows every turn, the SQL, and why each verdict was given.
    • CSV, with one row per turn, for answering “why did this fail?”
    • JSON, for CI and other tooling.

    Connecting your own SQL agent

    Moving from the example to your own agent comes down to a few changes:

    • Install MindzEval in your own project with pip install mindzeval. If your database is PostgreSQL, use pip install "mindzeval[postgres]" instead.
    • Replace the agent, but keep the adapter’s shape. In the example, the adapter is about 15 lines:
      from agent.graph import build_graph
      
      graph = build_graph()  # build once, reuse for every case
      
      
      async def answer(question, history, params):
          messages = [(m["role"], m["content"]) for m in history] + [("user", question)]
          state = await graph.ainvoke(
              {"messages": messages},
              config={"configurable": {"model": params.get("model")}},
          )
          return {
              "answer": state["messages"][-1].content,
              "sql": state.get("sql"),
              "status": state["status"],  # answer | clarify | decline
              "reason": state.get("reason"),
          }
    • Return the right fields. The adapter sends back a dictionary that uses MindzEval’s exact key names:
      • answer: the agent’s reply.
      • sql: the query it ran, which MindzEval re-runs against the database and checks for safety.
      • status: whether the agent answered, asked or declined, so that its behaviour can be scored.

      A misspelt key, such as query instead of sql, is rejected with an error rather than ignored. For agents that are not in Python, or that you cannot call during the eval, the connecting agents guide covers HTTP services and saved outputs.

    • Point database.url in mindzeval.yaml at your database.
    • Write 10 to 20 test cases from real user questions. The case format guide shows every option.
    • Run the same three commands: mindzeval lint, mindzeval validate and mindzeval run.

    Common mistakes

    • Using a database login that can write. A read-only login means nothing can change by accident. Keep its password in an environment variable such as ${DB_PASSWORD}, rather than in the file.
    • Passing the history twice. If your agent already remembers the conversation, for example through a LangGraph checkpointer, send just the new question. Otherwise, the earlier turns arrive twice.
    • Leaving out status. MindzEval then cannot tell whether answering, asking or declining was correct, so those checks are skipped.
    • Cutting rows in code instead of the SQL. A correct query can look incomplete as a result. To avoid that, return truncated: true whenever your agent trims the list itself.
    • Testing only easy questions. A handful of simple cases gives false confidence. Include a few vague and off-topic questions too, plus clear ones that must not trigger a clarifying question.
    • Pasting credentials or customer data into the config, the cases or a GitHub issue, where they stay in your git history and logs.

    What else can you do

    • Compare models. Add a matrix: block to mindzeval.yaml, for example model: [gpt-4o-mini, gpt-4o], and every combination runs side by side.
    • Run part of the suite. Use mindzeval run --case <id> for a single case, or mindzeval run --list to see what would run before anything does.
    • Break the agent on purpose. Edit the prompt in agent/graph.py and watch which cases change.
    • Tell us what happened. Feedback and bug reports are welcome in the MindzEval issues.

    In our next post, we will cover the upcoming features of MindzEval.

    Want to see how your SQL agent scores?

    MindzEval is built to give you a number you can trust for your SQL agent. To find out more, call us on +91 85957 97775.
  • Why Another Eval Tool? What MindzEval Does Differently for SQL Agents

    Since we wrote about MindzEval in Part 1 and Part 2, one question has come up again and again: there are already plenty of eval tools, so why build another one?

    To answer it, we reviewed more than 30 eval tools, platforms and benchmarks, as of October 2026. This post shares what we found, what MindzEval does differently, and where we are still behind.

    What is already out there

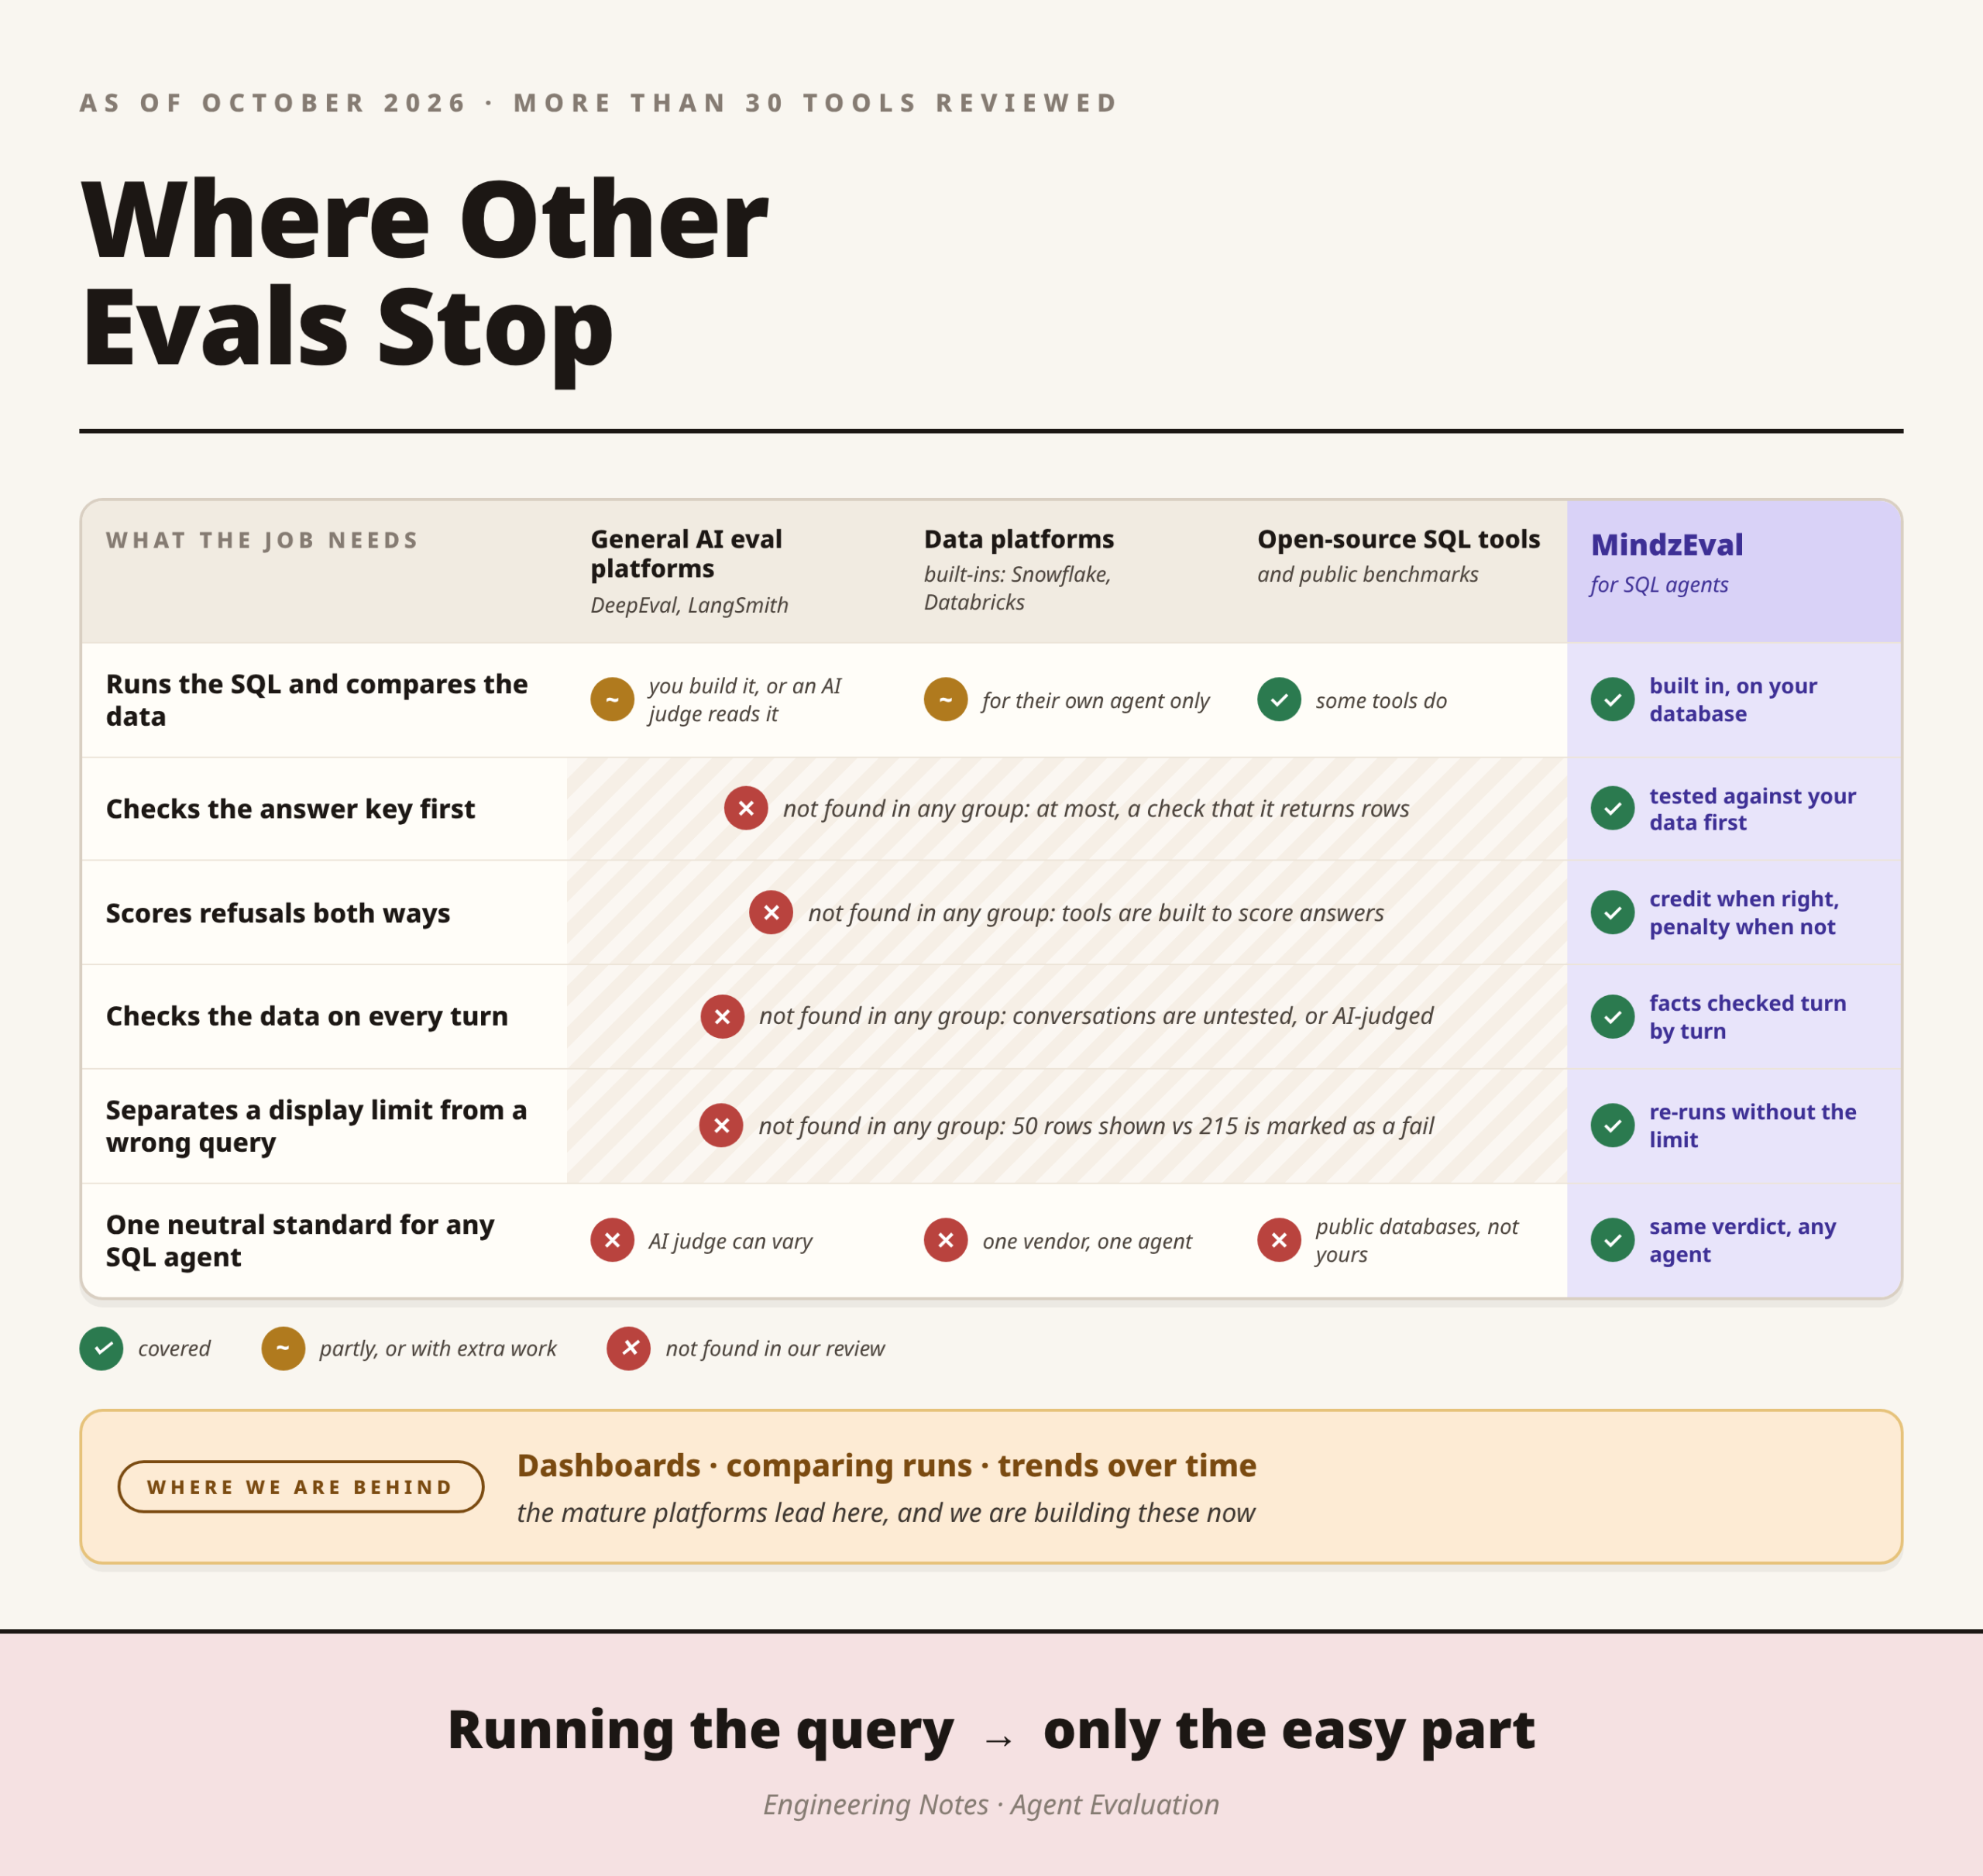
    Most of the tools we looked at fall into three groups. Each one is good at something, but each one also leaves a gap for teams testing a SQL agent.

    Type of tool What it does well What is missing for SQL agents
    General AI eval platforms
    such as DeepEval and LangSmith
    Great dashboards, datasets and CI They are built for any AI app, so there is no built-in check that runs the SQL and compares the data. Teams write that part themselves or use an AI judge.
    Data platform built-ins
    such as Snowflake and Databricks
    Free and well integrated They only test their own agent. If you move off the platform, you lose your yardstick.
    Open-source SQL tools and benchmarks Some do run the SQL and compare the results Each one covers only a piece of the job, and benchmarks run on public databases, not yours.

    In other words, running the SQL and comparing results is not unique to us. What is missing is one tool that does the whole job, for any SQL agent, on your own database.

    What we are trying to build

    Our goal is simple: one number a team can trust for its SQL agent. In practice, that number should:

    • Be checkable, so you can see exactly how it was worked out.
    • Stay comparable over time, so you can compare this month’s number with last month’s.
    • Point to the cause, so a lower score comes with a reason.
    • Work on any Text-to-SQL agent and any database, not just one vendor’s.

    So rather than a feature tied to one platform, we want MindzEval to be a neutral standard.

    What MindzEval does differently

    We did not find any of the following five things in the tools we reviewed.

    1. It checks the answer key before grading the agent

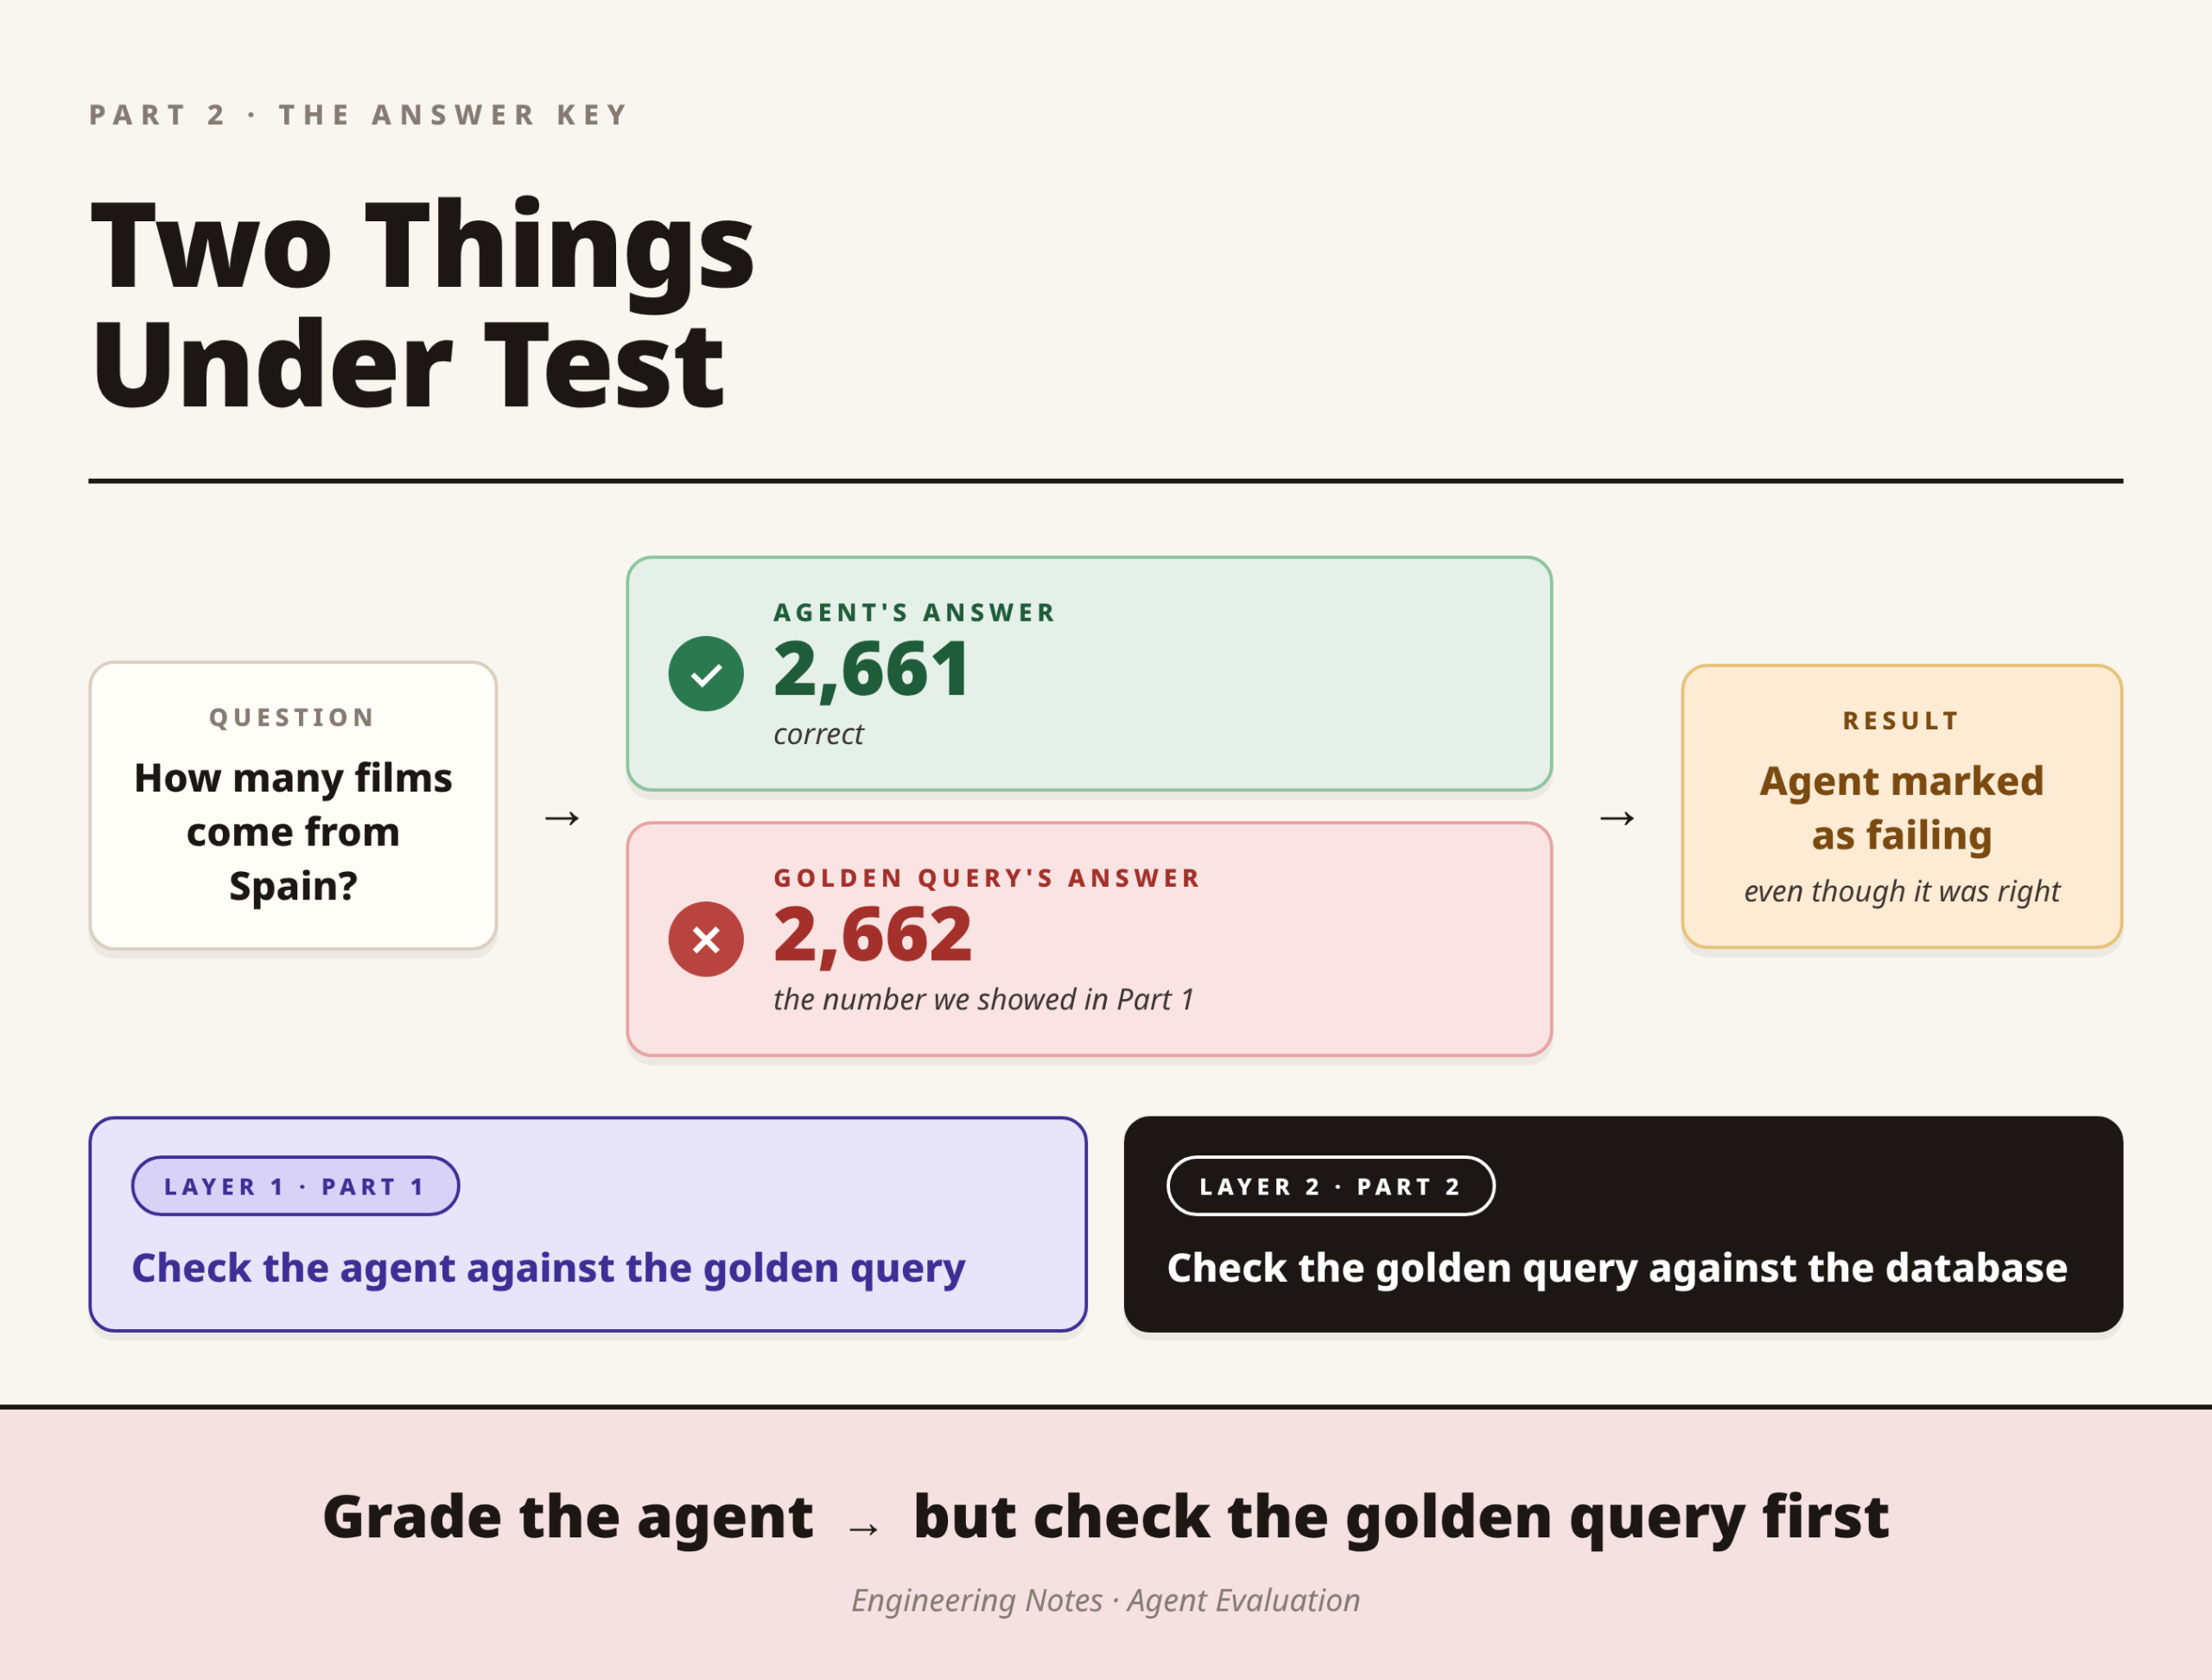
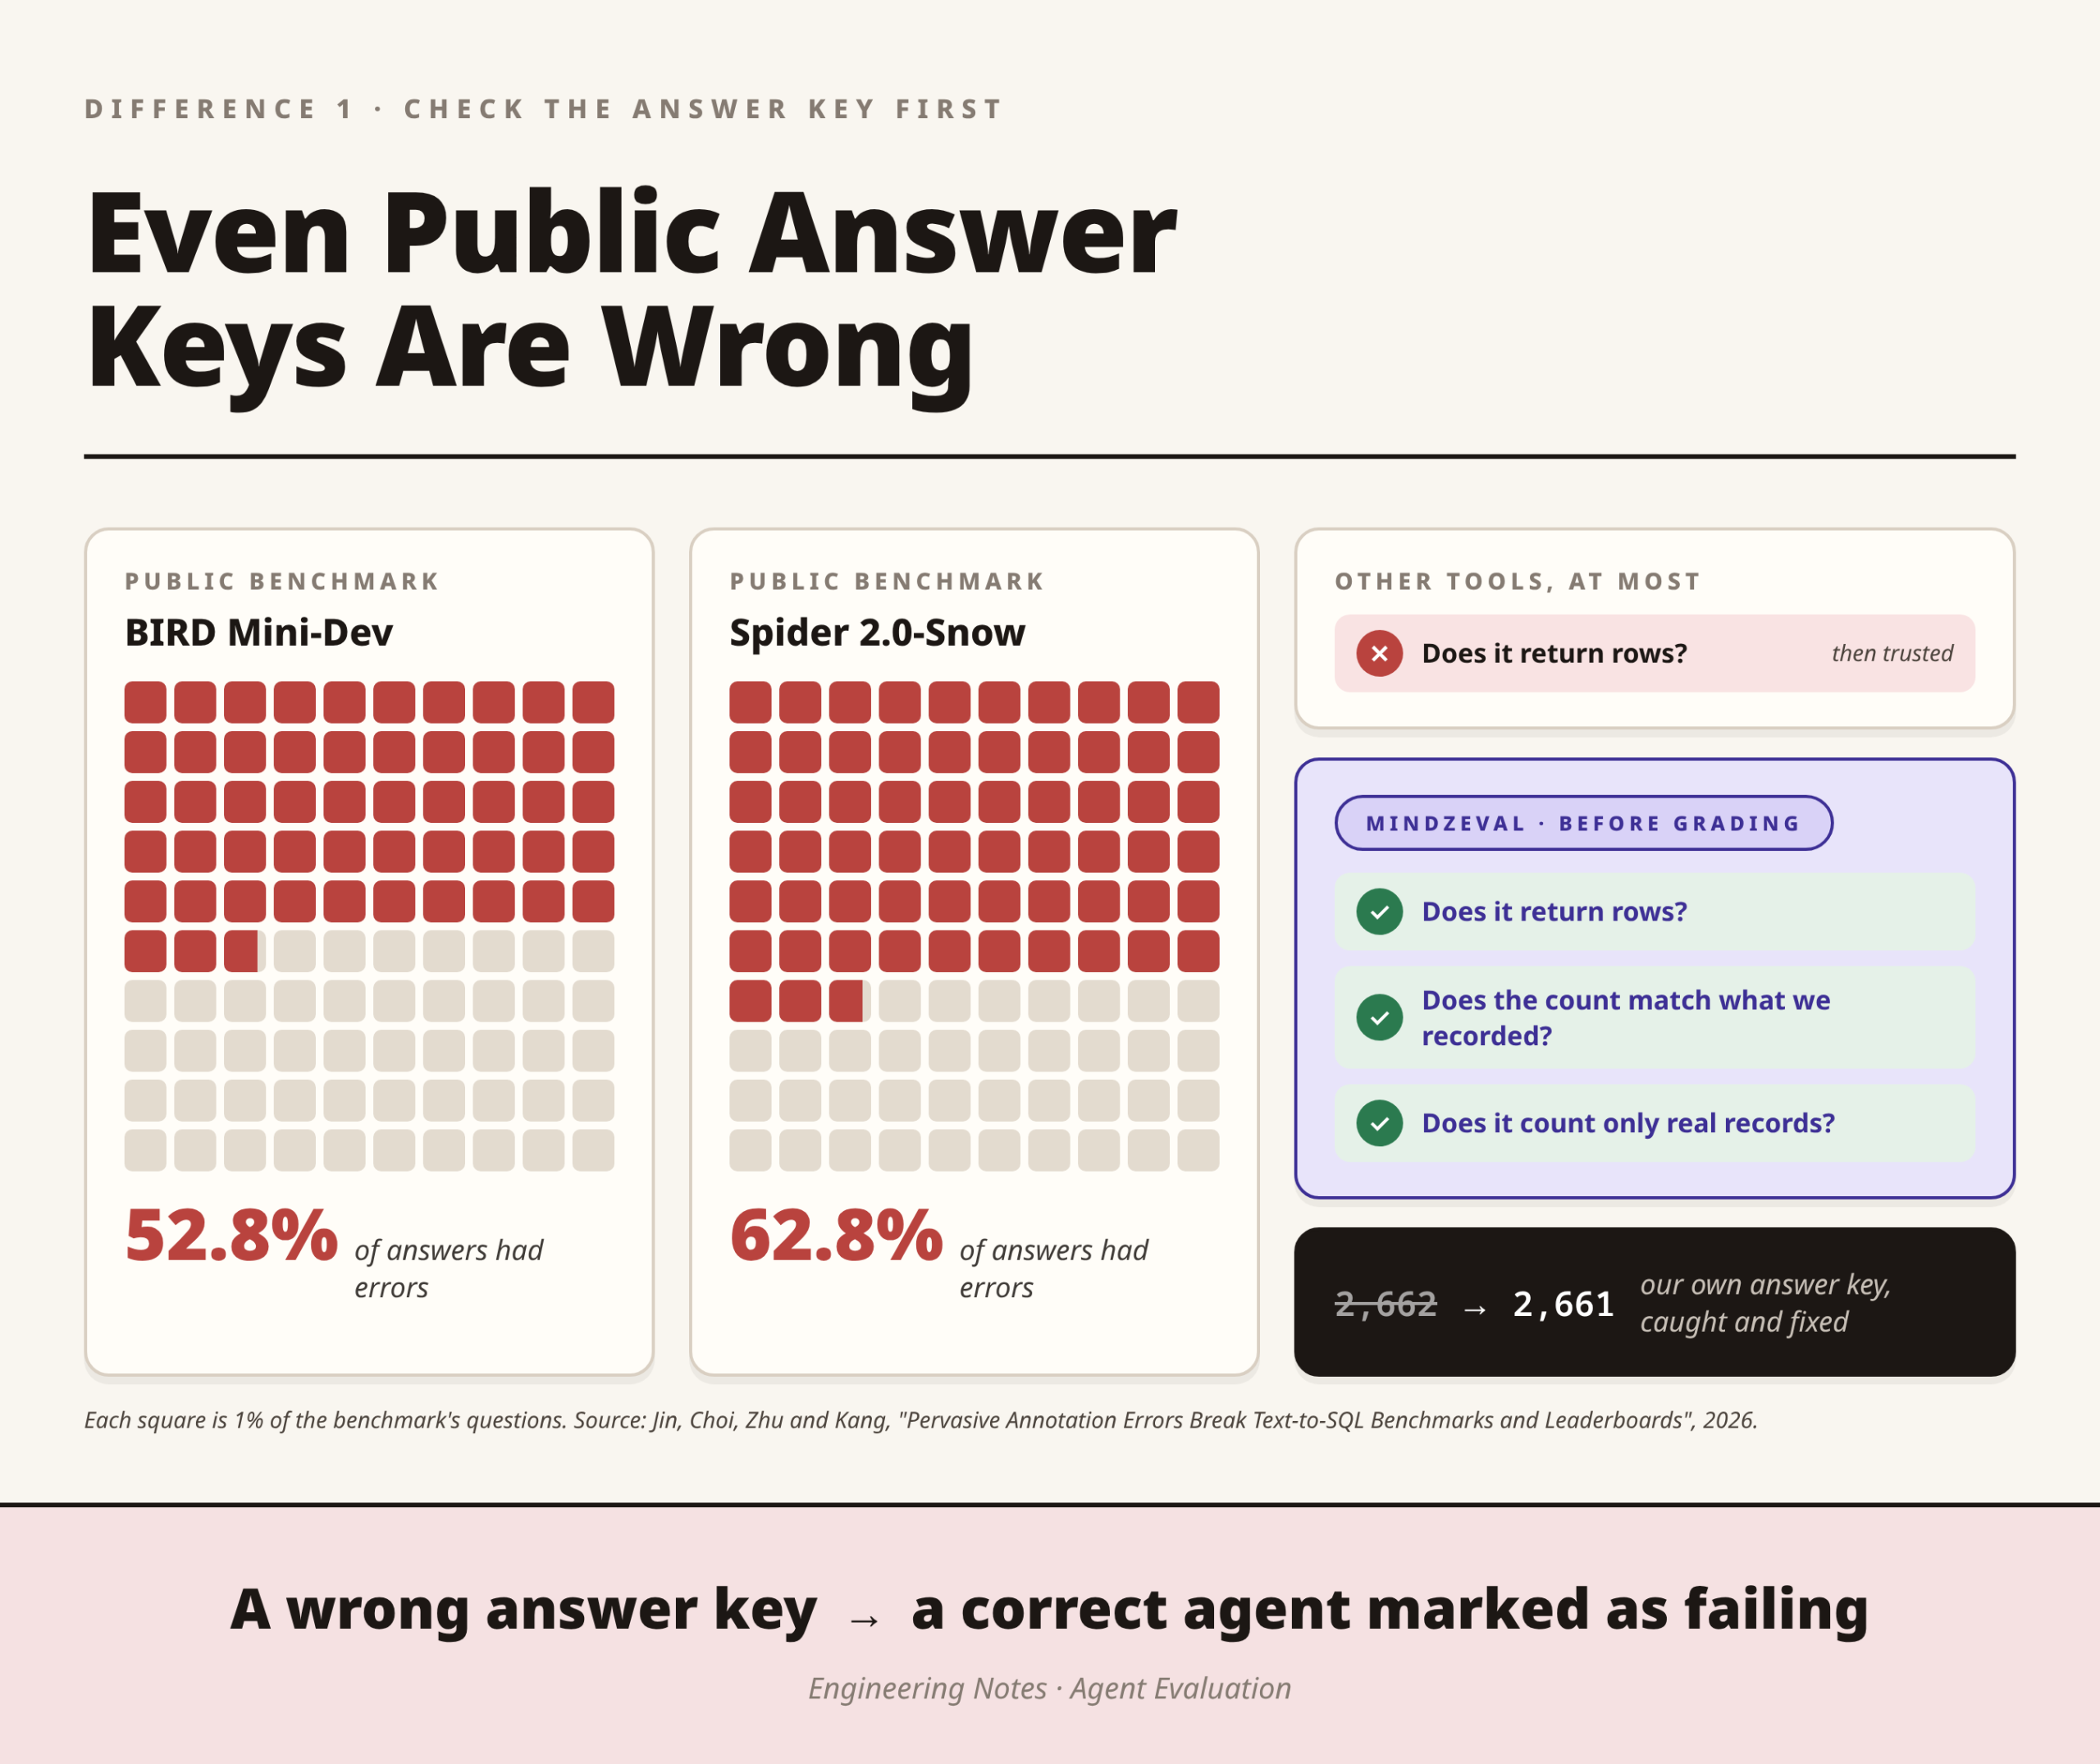
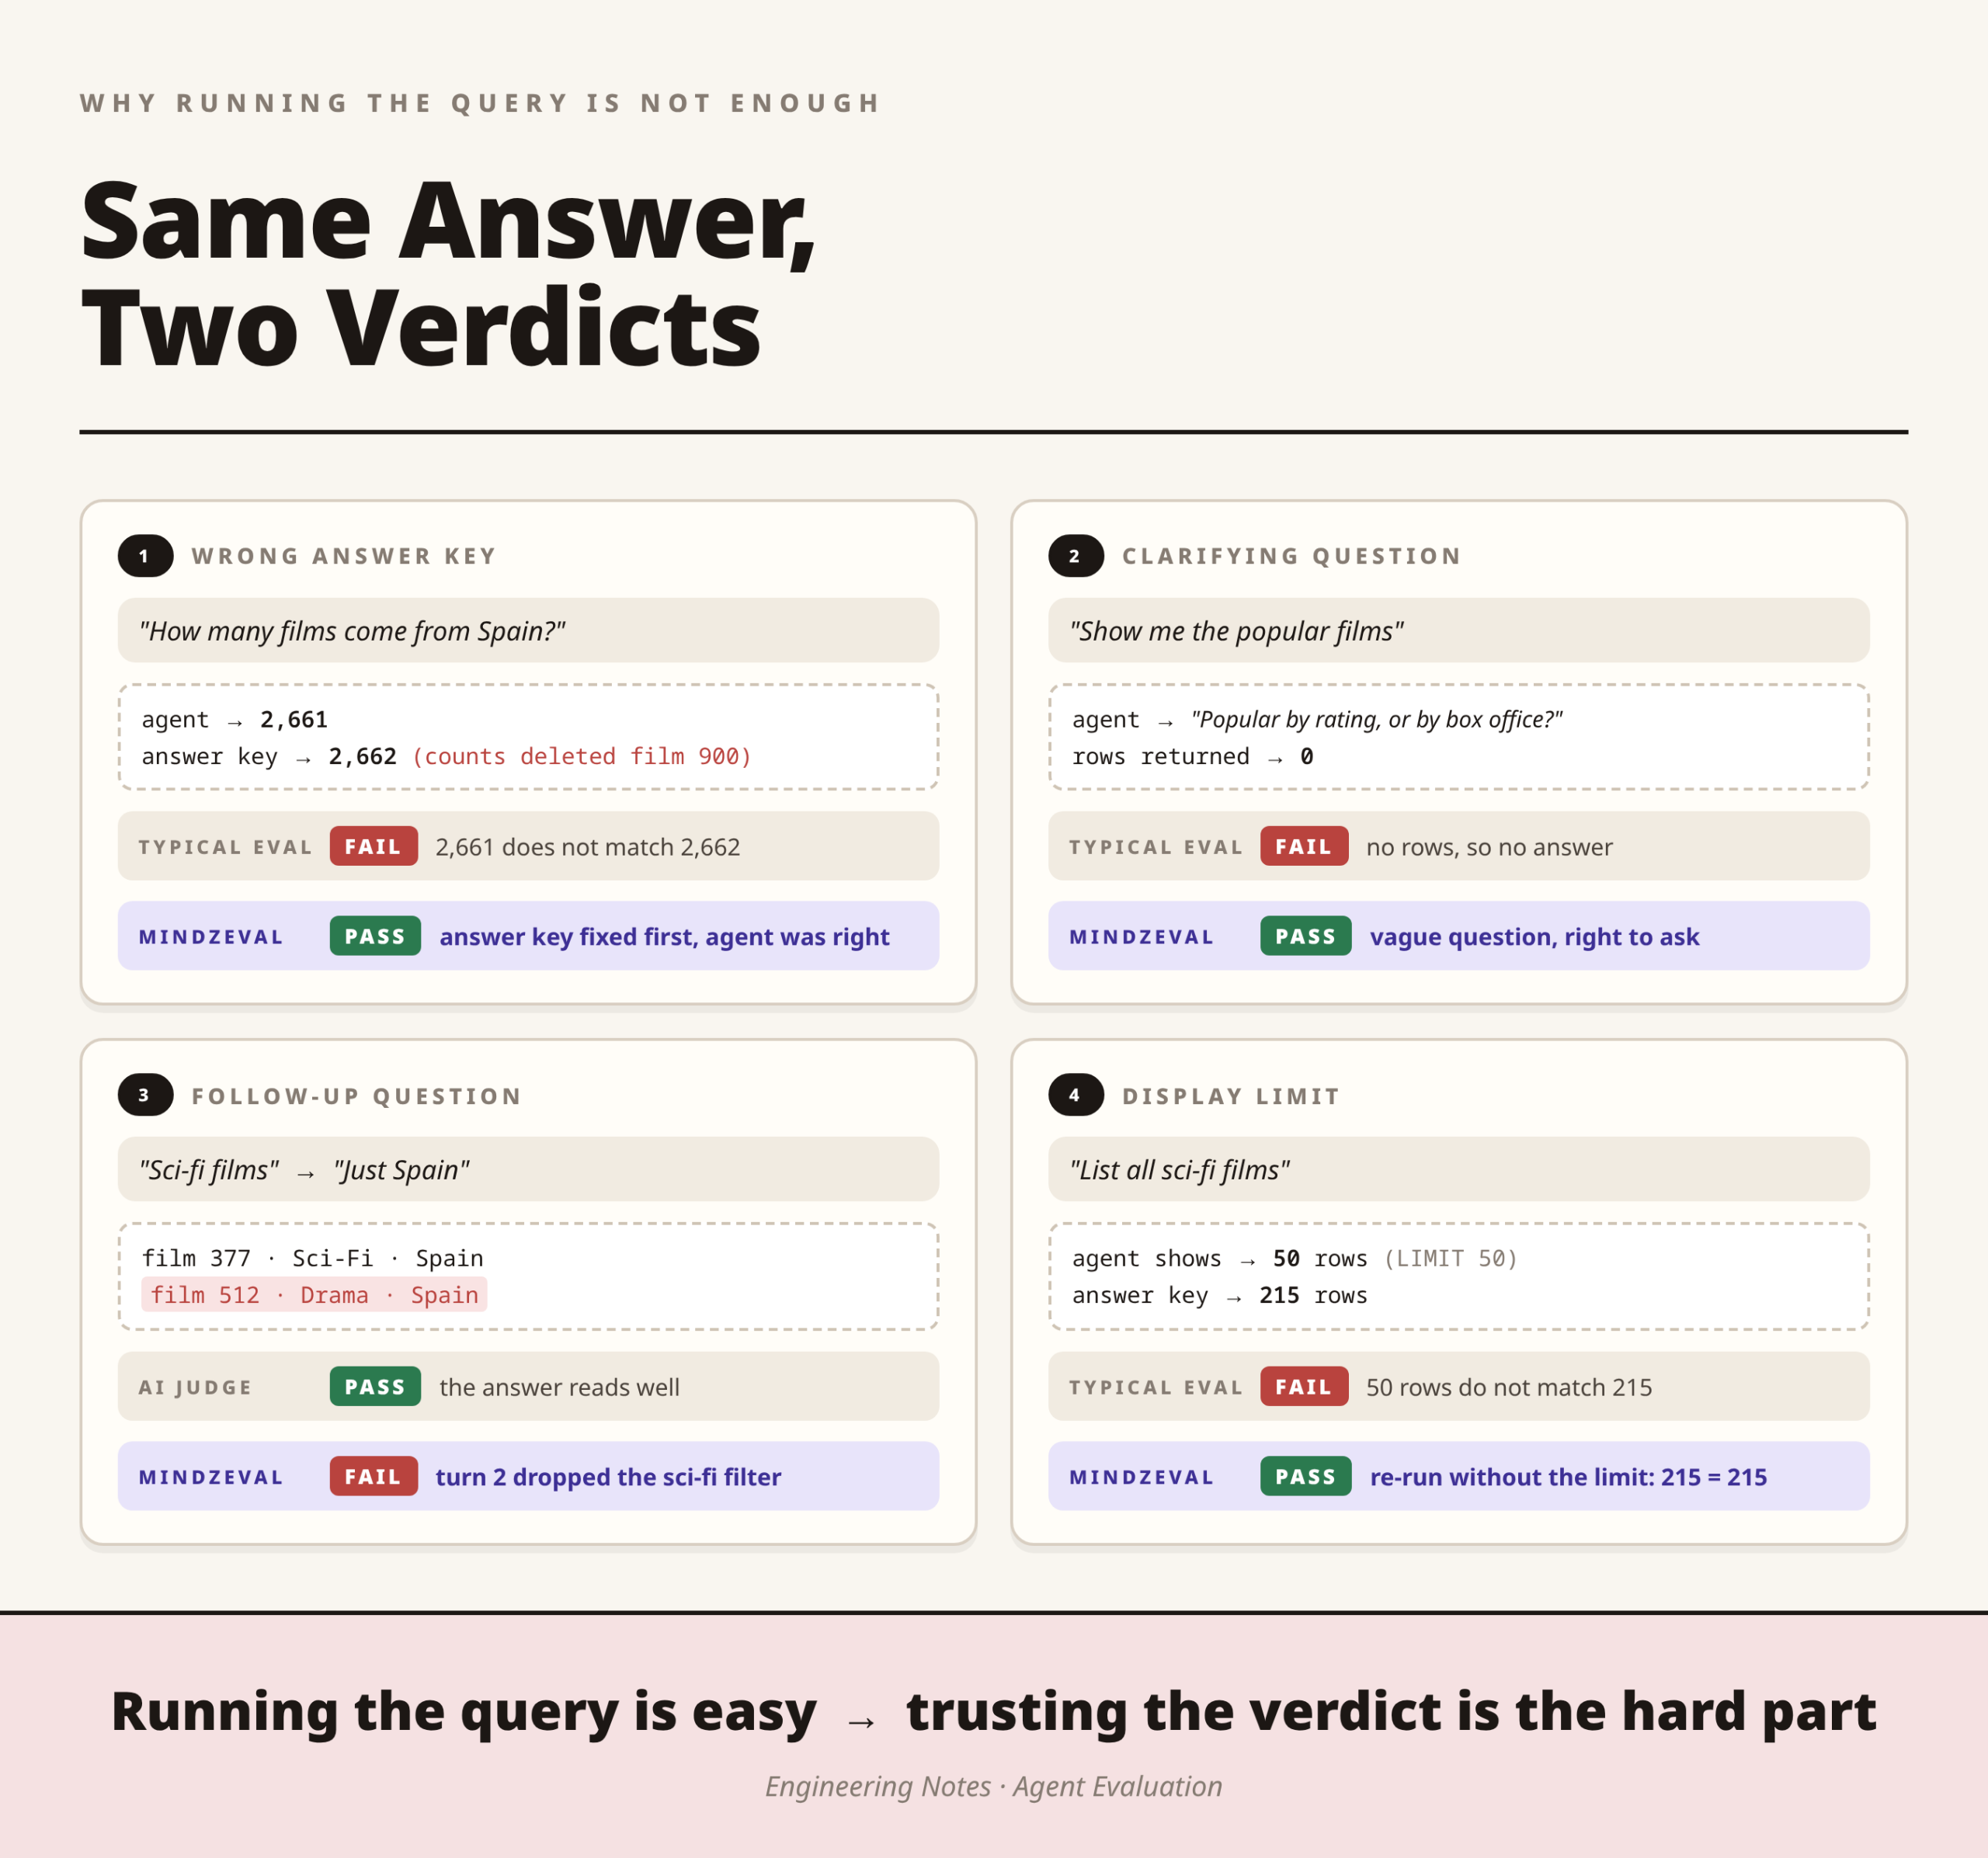
    Every eval compares the agent’s answer with a reference answer. However, reference answers can be wrong too. In Part 2, our own reference said 2,662 films came from Spain, while the agent correctly said 2,661.

    This is not just our problem. A 2026 study found error rates of 52.8% and 62.8% in the reference answers of two popular Text-to-SQL benchmarks, BIRD Mini-Dev and Spider 2.0-Snow.

    • Other tools at most check that a reference answer returns some rows.
    • MindzEval tests each reference answer against your database before it grades the agent, so a broken test cannot show up as an agent bug.

    2. It scores clarifying questions and refusals both ways

    Most eval tools are built to score answers. As a result, they have no clear way to tell a good clarifying question or refusal from a bad one.

    MindzEval scores this too. It gives credit when asking or declining was the right move, and marks it down when it was not.

    3. It checks the data on every turn of a conversation

    Real users ask follow-up questions. For example, someone might ask for sci-fi films and then say “just Spain”. The second answer only makes sense if the agent remembers the first question.

    • Most tools either do not test conversations, or they ask an AI judge whether the answers look right.
    • MindzEval checks the actual data returned on every turn, so each answer is graded on facts, not on how it reads.

    4. It tells a display limit apart from a wrong query

    Many agents only show a limited number of rows. For example, our agent showed 50 films when the full answer was 215. A simple row comparison marks that as wrong, even though every film shown was correct.

    To avoid this, MindzEval re-runs the query without the limit. That way, it can tell “the agent only showed part of the answer” apart from “the agent wrote the wrong query”.

    5. It is one neutral standard for any SQL agent

    • It gives the same verdict every time, because it does not use an AI judge by default.
    • It works with any framework, so you do not have to rebuild your agent around it.
    • It works the same way for every SQL agent, whatever platform or database it runs on.

    Because of this, a score from MindzEval means the same thing whichever agent, framework or week it comes from.

    Where we are still behind

    We want to be honest about this too. The mature platforms are ahead of us on dashboards, comparing runs and tracking trends over time. We are building these now, but for the moment, they do them better.

    The short answer

    So, why another eval tool? Because for SQL agents, running the query is the easy part. The hard part is trusting the score, and that is the gap MindzEval is built to fill.

    Want to know whether your SQL agent is right, not just whether it looks right?

    MindzEval is built to give you a number you can trust for your SQL agent. To find out more, call us on +91 85957 97775.
  • Testing the Answer Key: How MindzEval Validates Its Golden Queries

    In Part 1, we built MindzEval to replace a feeling with a number. Just as in Part 1, the examples use a film catalogue as a stand-in for our real data. 

    The idea behind MindzEval was that instead of grading the agent’s SQL letter by letter, we grade whether it returned the right films. To do that, we keep a known-correct query, which we call a golden query, for every test question. We then run it fresh on every run and compare its answer with the agent’s.

    However, that design rests on one assumption: that every golden query is actually correct. As it turned out, one of ours was not. In Part 1, we said the golden query for “films from Spain” returned 2,662. The correct answer is 2,661.

    This post explains how we found that out, and what MindzEval now does so that it does not happen again. As before, the examples use a film catalogue as a stand-in for our real data.

    How we found the wrong golden query

    The question was the same one from Part 1: how many films come from Spain? The agent ran its query and answered 2,661. Our golden query, on the other hand, answered 2,662. By the rules of the suite, the agent was off by one, so the case was marked as a failure.

    When we looked closer, though, the agent turned out to be right, and our golden query was the one that was wrong.

    The cause was a leftover in the data:

    • The catalogue links films to countries through a separate table. Each row in that table says “this film is from this country”.
    • One of those rows pointed at a film that no longer existed. The film had been removed from the film table, but its link to Spain had been left behind after an import.
    • Our golden query counted films through the link table, so it counted that missing film too.
    • The agent counted films starting from the film table itself, so it only counted films that actually exist.

    Since the difference was only one film, nobody would have spotted it by reading the numbers. Nobody recounts 2,662 films by hand. If we had trusted the golden query, we might have changed the correct agent to match a broken test. As a result, the agent would have got worse while its score went up. That is why a wrong golden query is so risky: it does not just miss real bugs, it reports bugs that are not there.

    How MindzEval checks its golden queries

    The lesson we took from this is that golden queries are not something you write once and trust forever. Like any other code, they need their own tests. So MindzEval now has a separate validator for the golden queries. 

    It is different from the self-checks in Part 1: those test the harness code, whereas this one tests the data we grade against. Moreover, every golden query has to pass it before we trust the scores it produces, and it runs three checks, starting with the cheapest.

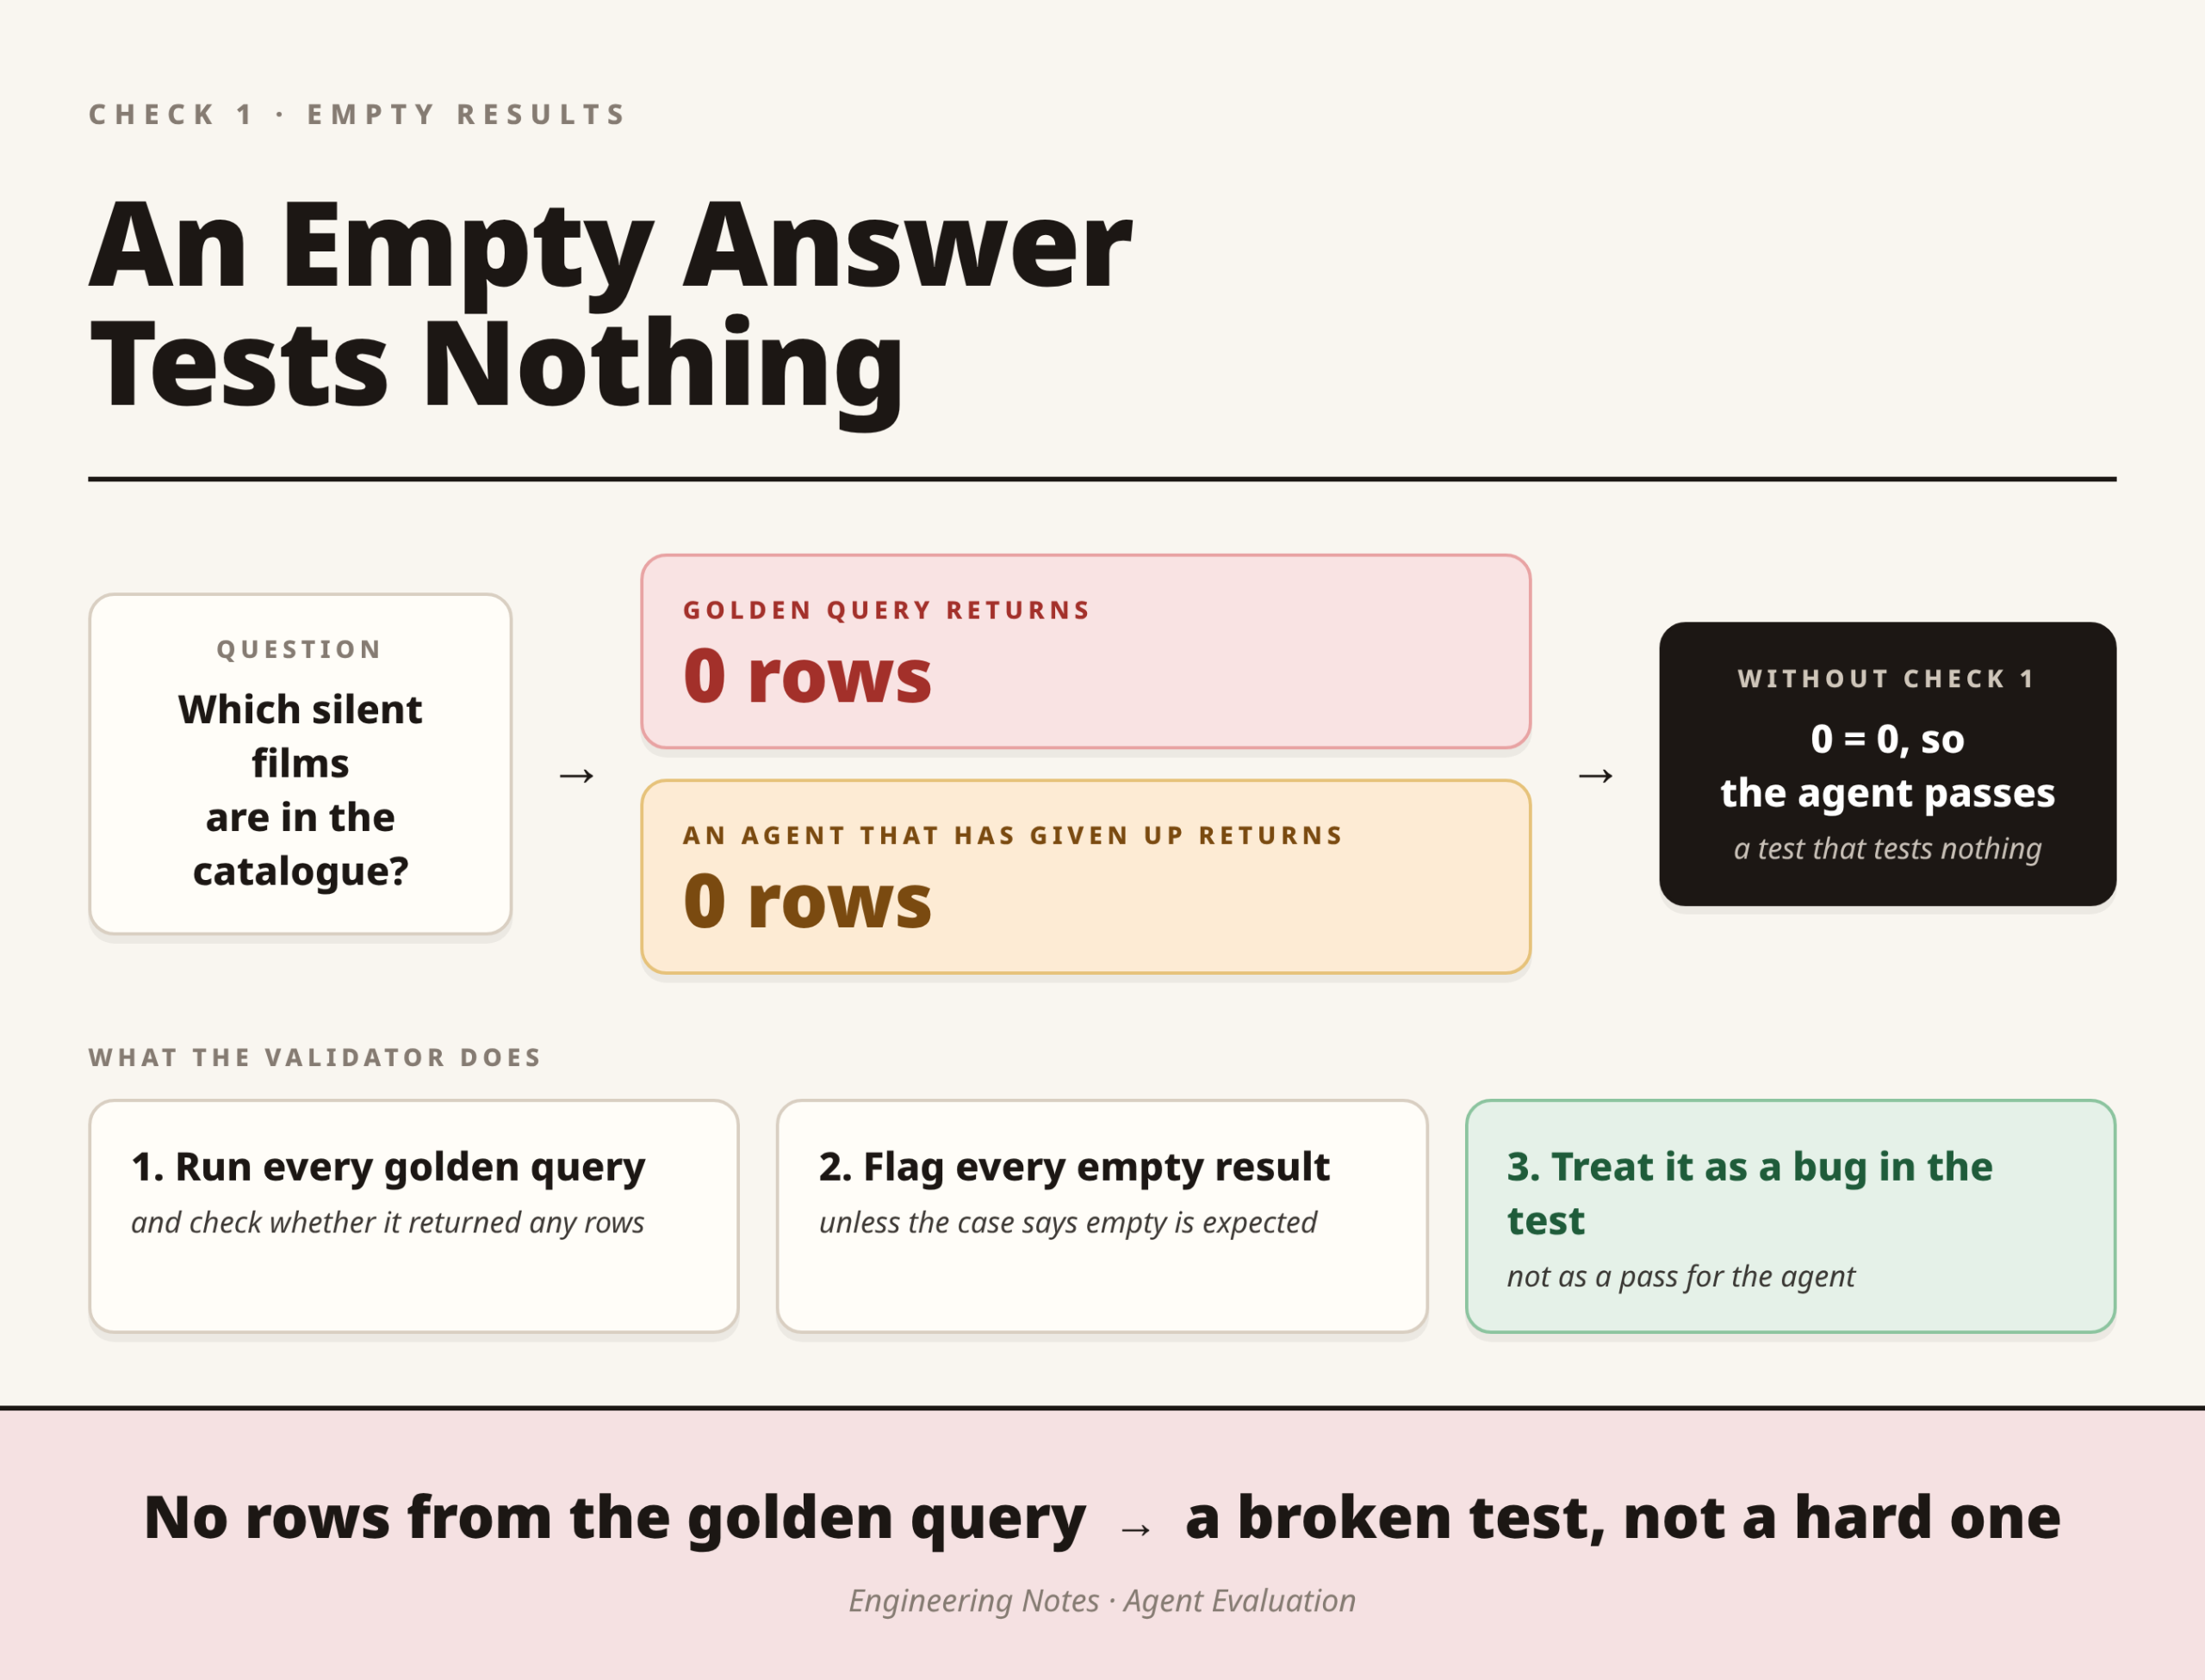
    Check 1: Flag golden queries that come back empty

    Why it matters

    When a golden query returns no results, it does not make the test harder. Instead, it means the test itself is broken, because there is nothing for the agent’s answer to be checked against. 

    For example, if a question about silent films quietly returns no rows, then any agent that also returns no rows will pass, including one that has simply given up. Consequently, an empty golden query looks like a test while testing nothing.

    What we do

    • The validator runs every golden query and checks whether it returned any rows.
    • It flags every empty result unless the case says that an empty answer is expected.
    • An unexpected empty result counts as a bug in the test, not as a pass for the agent.

    Check 2: Compare the count with what we recorded

    Why it matters

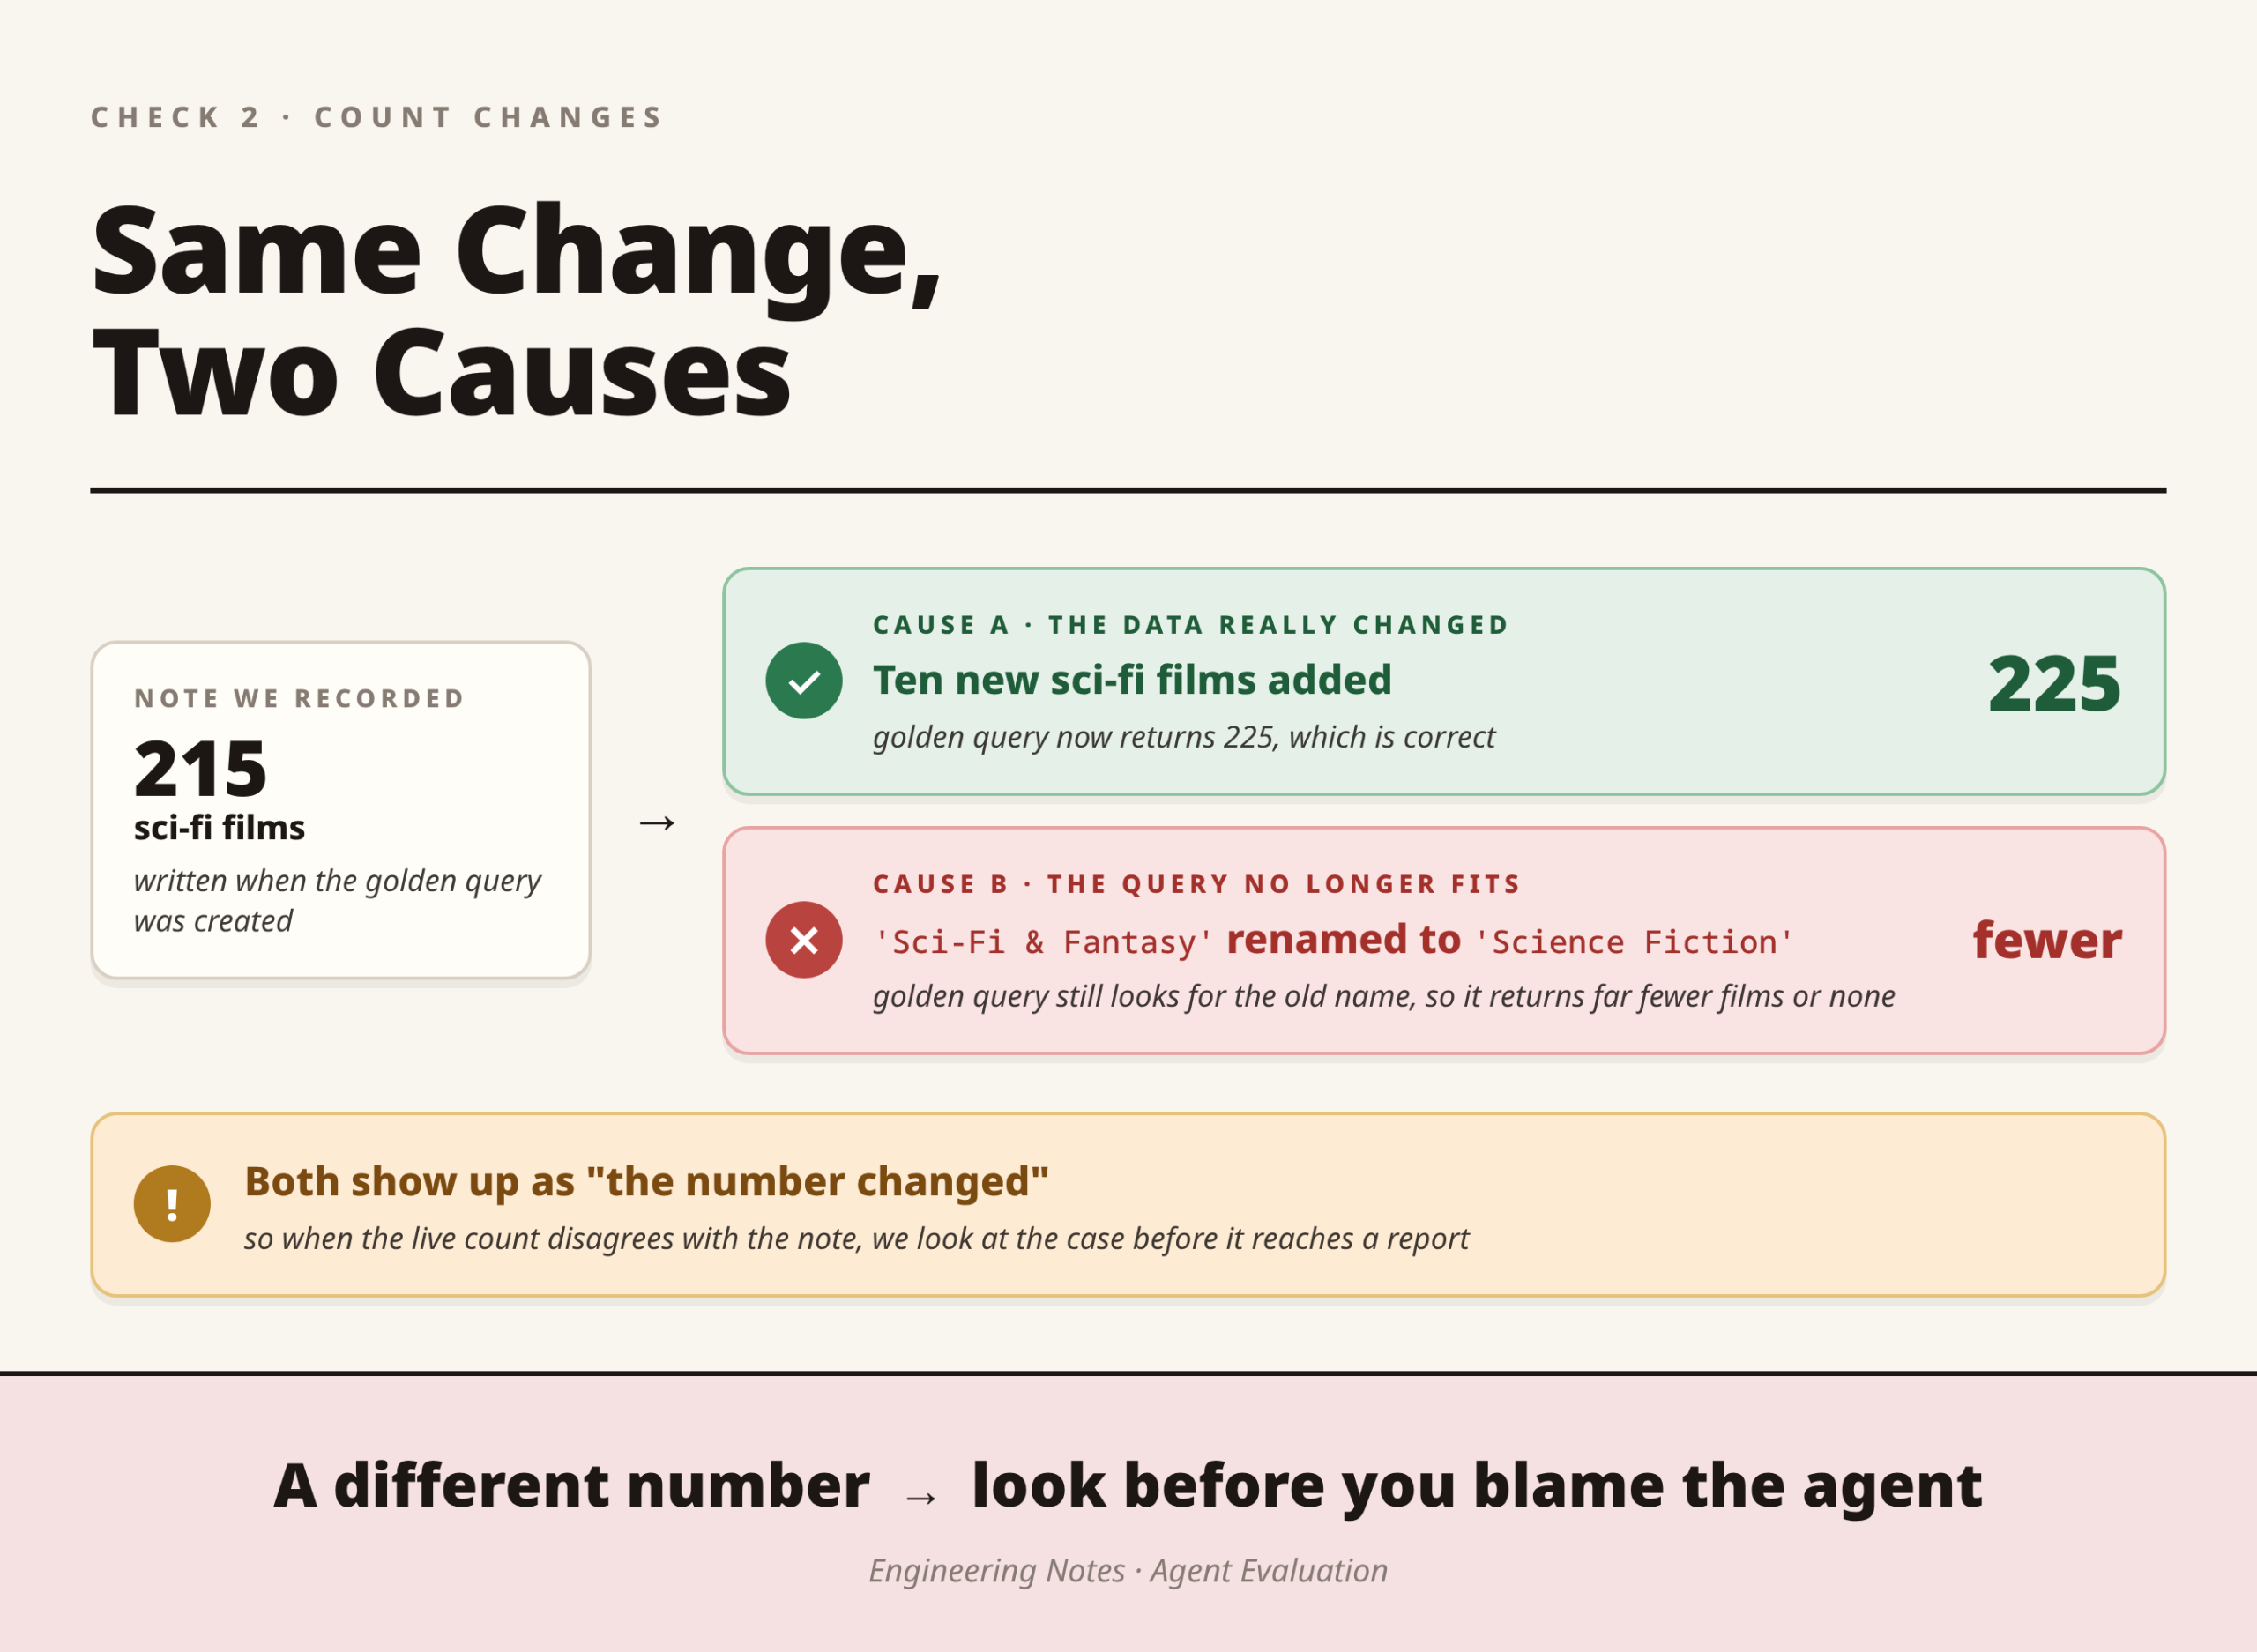
    As Part 1 explained, we store the golden query rather than its rows, so that the answer stays current when the data refreshes. Even so, a live query can change its answer for two very different reasons. Either the data really changed, or the query no longer means what we intended. From the score alone, you cannot tell which one happened.

    For example, suppose our golden query for sci-fi films used to return 215, and today it returns 225. That could simply mean ten new sci-fi films were added to the catalogue, in which case the new answer is correct. 

    On the other hand, suppose the catalogue renamed its ‘Sci-Fi & Fantasy’ genre to ‘Science Fiction’. In that case, our golden query would still be looking for the old name, so it might suddenly return far fewer films, or none at all. Both changes show up as a different number, but only the first one is a real change in the data. The second one is a broken test.

    What we do

    • When we first write a golden query, we note the count it returned, for example “this should return 215 sci-fi films”. The query still produces the answer; the note is only there for comparison.
    • The validator re-runs the query and compares the live count with that note.
    • If the two disagree, we look at the case before it reaches a report. That way, we find out whether the data changed or the query drifted, instead of spending a morning blaming the agent for a gap the test created.

    Check 3: Make sure the golden counts real things

    Why it matters

    Checks 1 and 2 are good at spotting warning signs. Check 1 tells us when a golden query returns nothing, and Check 2 tells us when its count suddenly changes. However, neither of them can catch the problem we had with the Spain example.

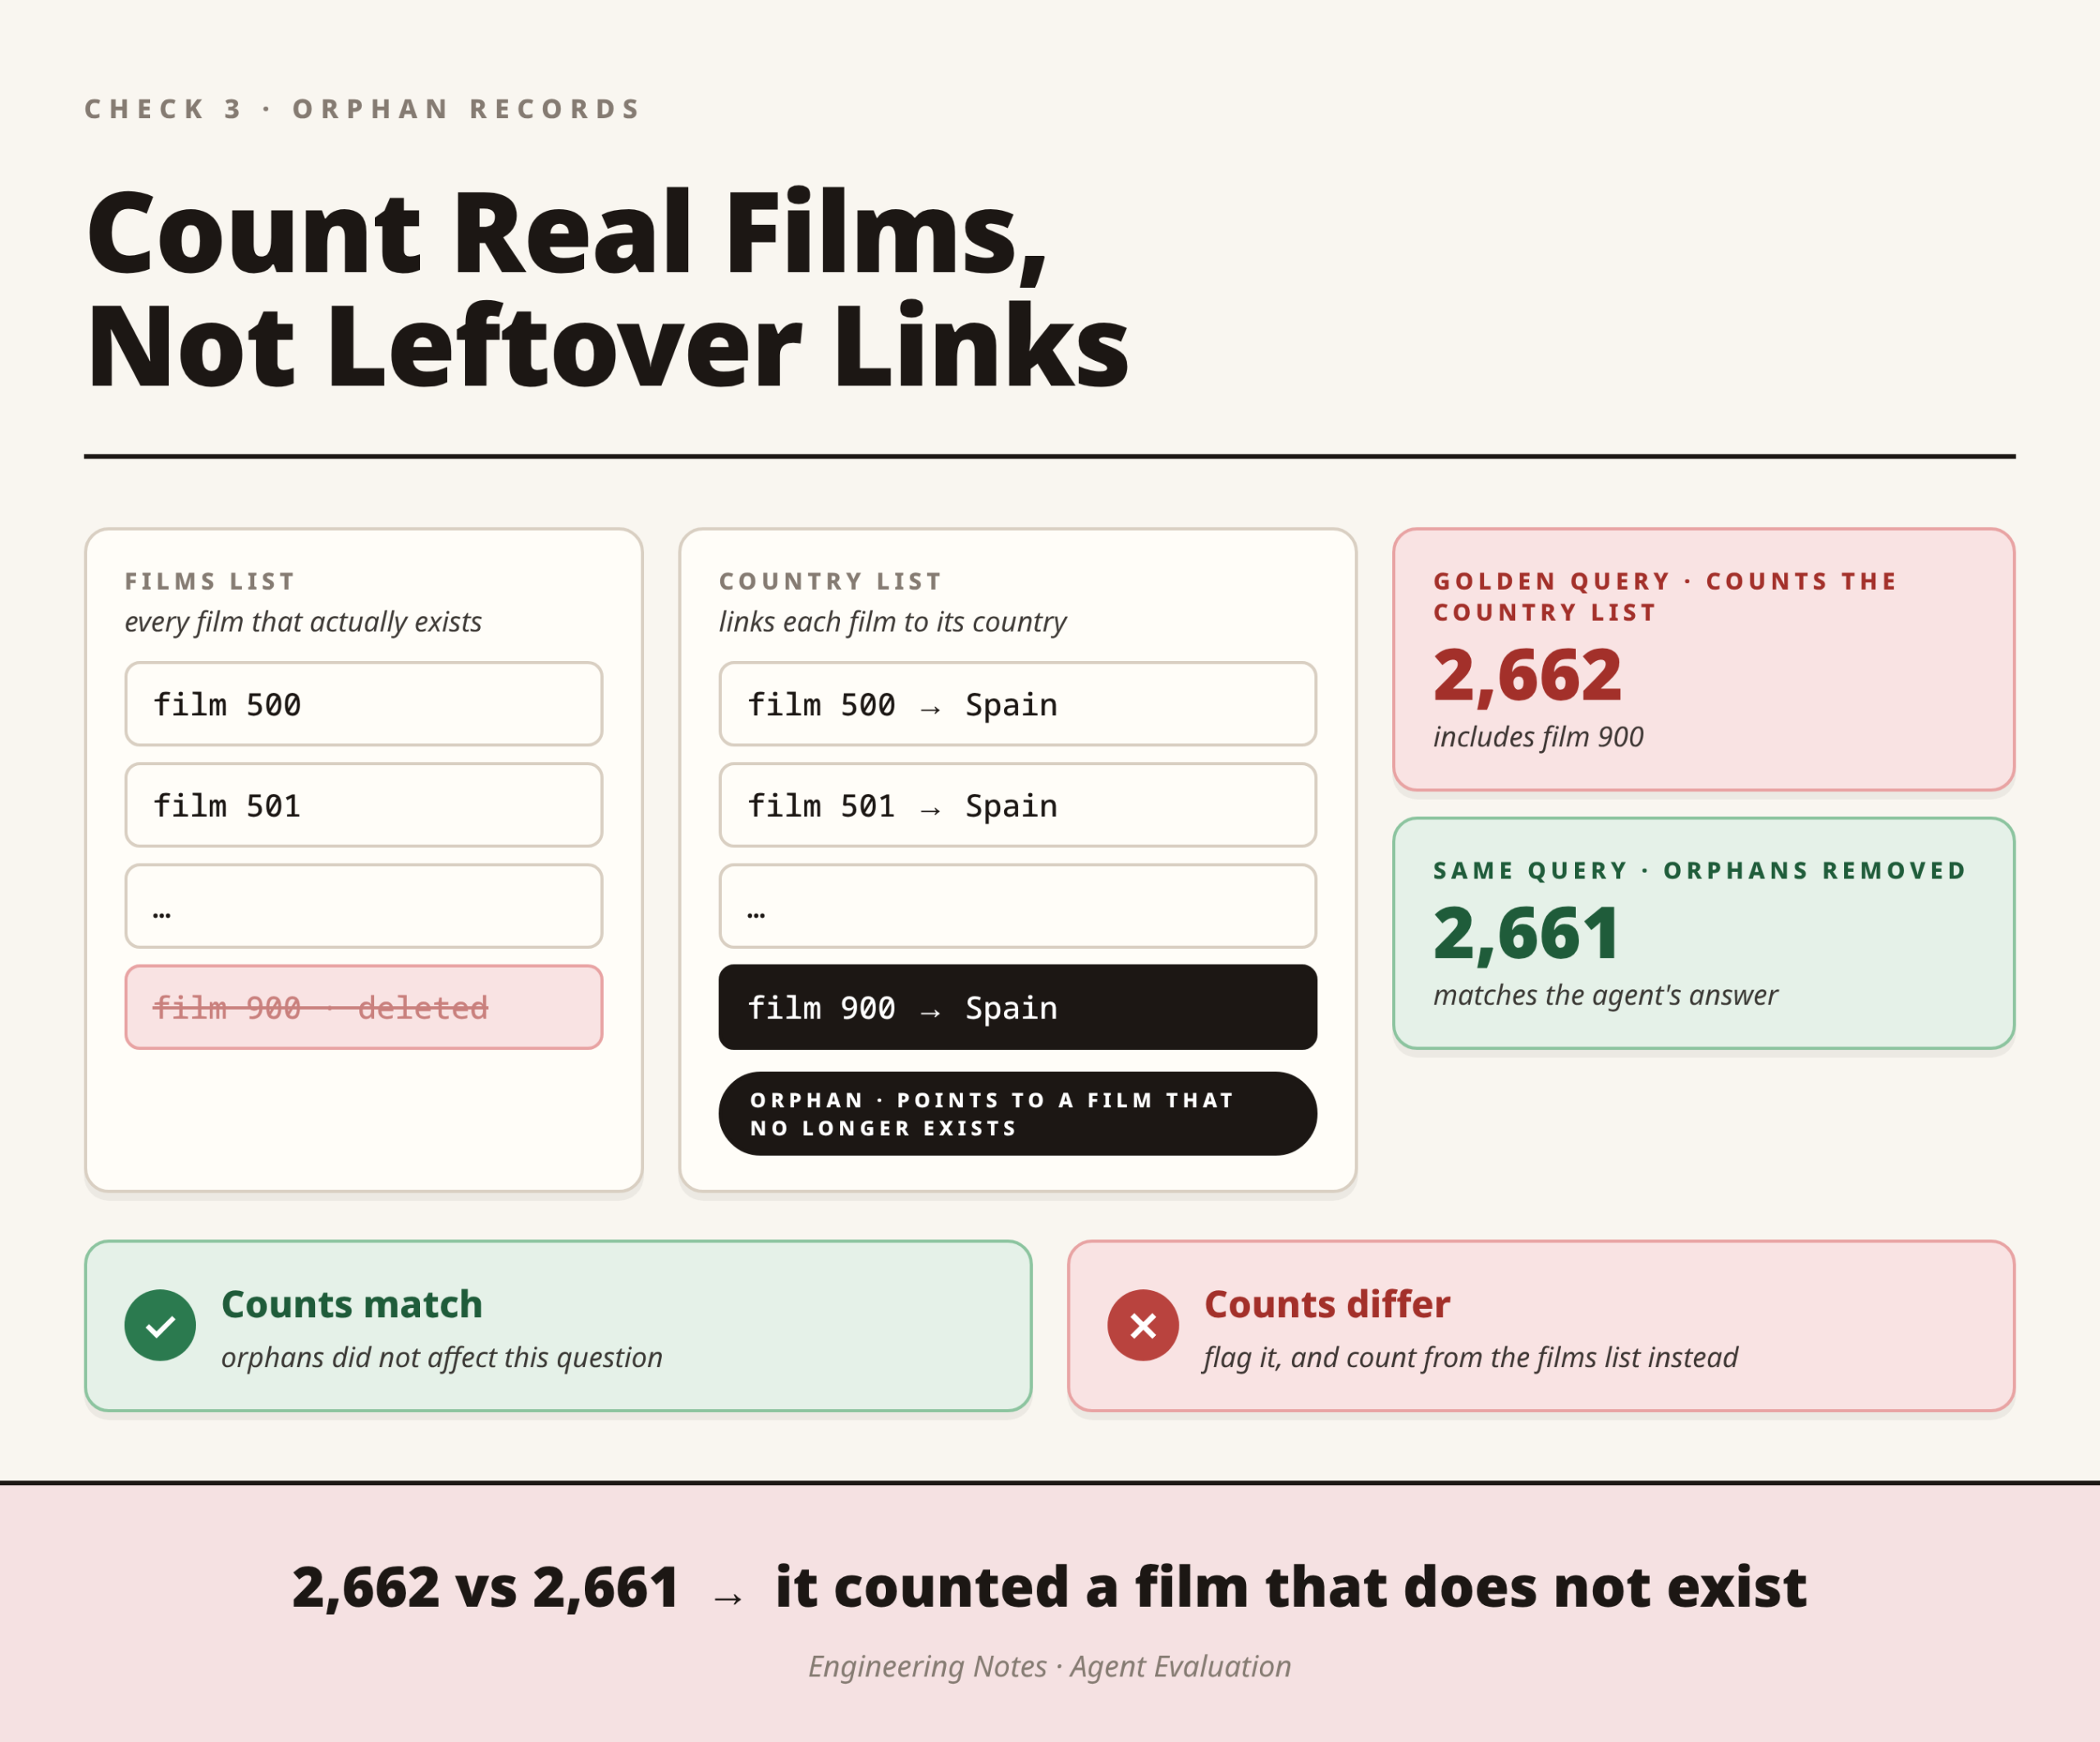
    Check 3 looks for orphan records. To see what an orphan is, it helps to know that the catalogue keeps two separate lists:

    • The films list holds every film that actually exists, one row per film.
    • The country list links each film to its country, with rows such as “film 500 is from Spain”.

    Normally, every film in the country list also appears in the films list. An orphan appears when that is no longer true:

    • A film is deleted from the films list, for example film 900.
    • However, its row in the country list stays behind, so it still says “film 900 is from Spain”.
    • That leftover row is the orphan, because it points to a film that no longer exists.

    This is exactly what happened in the Spain example:

    • Our golden query counted Spanish films using only the country list, so it counted the orphan too and returned 2,662.
    • The agent only counted Spanish films that also appear in the films list, so it skipped the orphan and returned 2,661.

    Check 3 is designed to catch this. It finds orphans like film 900 and works out whether any golden query is counting them as if they were real films.

    What we do

    • The validator first looks for orphan records in the link tables.
    • For every golden query that uses one of those tables, it rewrites the query with the orphans removed.
    • It then runs both versions and compares the answers.
      • If they match, the orphans did not affect that question, so the golden query is fine as written.
      • If they differ, the golden query depends on counting something that does not exist. In that case, the validator fails the query and asks for the count to start from the real record, not from the link table.


    That is exactly the change that turns 2,662 into 2,661. More importantly, the fix does not come from the agent’s answer, and it does not come from our own judgement either. Instead, it comes from the database.

    Why it is easy to trust golden queries too much 

    Writing golden queries already feels like the careful part of building an evaluation, so it is tempting to assume they are the one thing that does not need checking. 

    However, that is exactly where our own mistakes hide. Because every score is measured against the golden queries, one wrong golden query does not just affect one case. It affects every number that depends on it.

    After all, an evaluation suite exists to catch confident wrong answers, and a golden query is a confident answer that we wrote ourselves. So it should meet the same standard we set for the agent.

    The lesson

    Part 1’s lesson was to grade the answer, not the query. Part 2 adds one step before that: check the golden queries before you trust the grade. In practice, that means three things:

    • Flag golden queries that come back empty.
    • Watch their counts for unexpected changes.
    • Make sure they count records that actually exist.

    Above all, when the agent and your test disagree, keep in mind that the test might be the one that is wrong. In our case, it was.

    Want an evaluation you can trust?

    MindzEval grades every stage of a text-to-SQL pipeline, scores refusals in both directions, and checks its own golden queries against the live database before it trusts a single result. To find out what it could reveal about your agent, call us on +91 85957 97775.
  • Grade the Answer, Not the Query: How We Built MindzEval to Evaluate Our Text-to-SQL Agent

    We built an agent that turns plain-English questions into SQL, and it worked. Then someone asked the one question it could not answer for us: how do we know it is right? This post is about the evaluation suite we built to replace a feeling with a number.

    If you ask our agent “how many sci-fi films are there?”, it works out what you mean, maps your words to the right database fields, writes the query, runs it, and hands back the answer. Throughout this post, the examples use a film catalogue as a stand-in for our real data.

    However, every time we changed a prompt, swapped the model, or edited the semantic layer, we were guessing. We could not prove we had not made the agent worse, so if accuracy quietly dropped, we would find out from a user weeks later. What we wanted was one number we could check ourselves, which meant the same thing every week and told us where the agent broke when it fell.

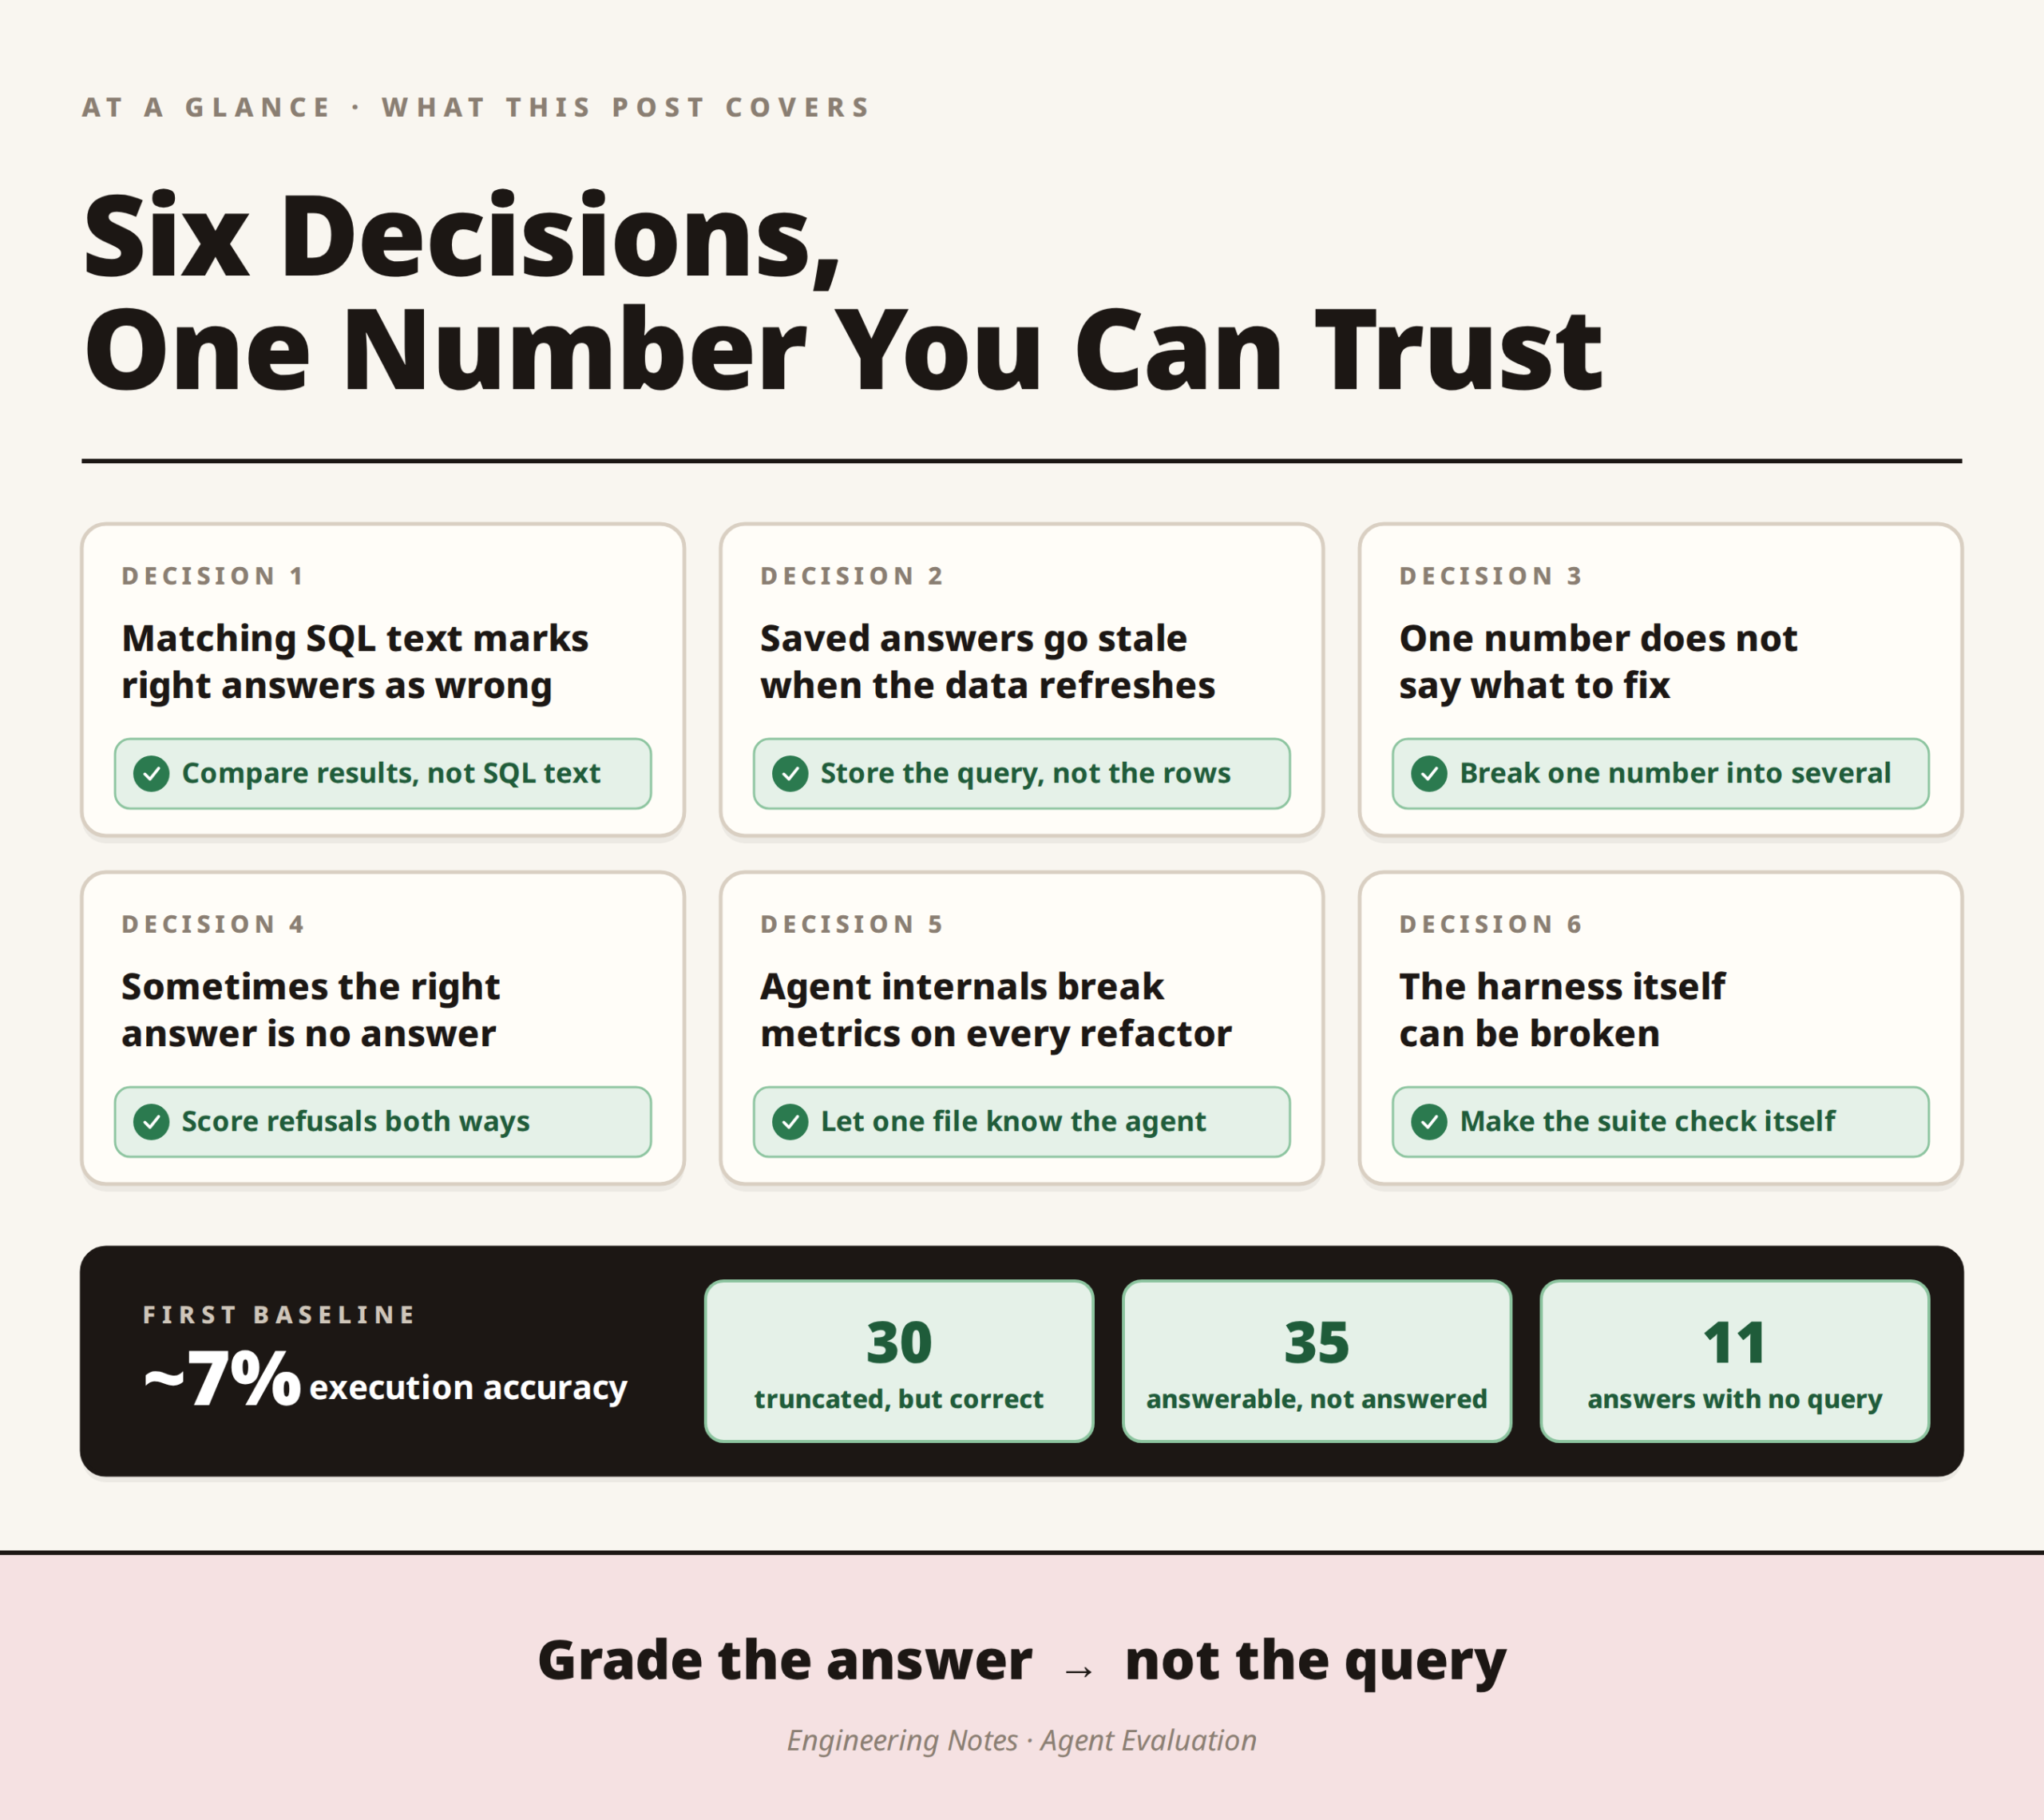
    Text-to-SQL evaluation at a glance: six problems and fixes, plus a first baseline of about 7% execution accuracy

    Why doesn’t “it looks right” work for testing an agent?

    Before the suite existed, checking the agent meant typing in a few questions and reading the answers. That approach fails in three ways:

    • It cannot be repeated, so you can never say “this is better than last time” and mean it precisely.
    • It produces prose rather than a number, and “seems good” cannot go on a graph or block a bad change from merging.
    • Its coverage is limited to whatever you thought of, even though the questions that break an agent are usually the ones nobody thought to type.

    In other words, we needed something objective, reproducible, and diagnostic.

    Why not just use RAGAS or DeepEval?

    Two tools stood out:

    • DeepEval, an open-source framework for testing LLM applications with pytest-style assertions and a large library of ready-made metrics.
    • RAGAS, whose text-to-SQL evaluation guide runs the known-correct SQL and the agent’s SQL, compares the data each returns, and improves the prompt through error analysis. Its worked example climbs from about 2% accuracy to roughly 71% across three prompt versions.

    That loop of measuring, analysing, fixing, and measuring again became the backbone of everything below, and we took it wholesale.

    What the tools could not give us

    Even so, neither tool fitted our agent on its own, because we needed two things they could not provide:

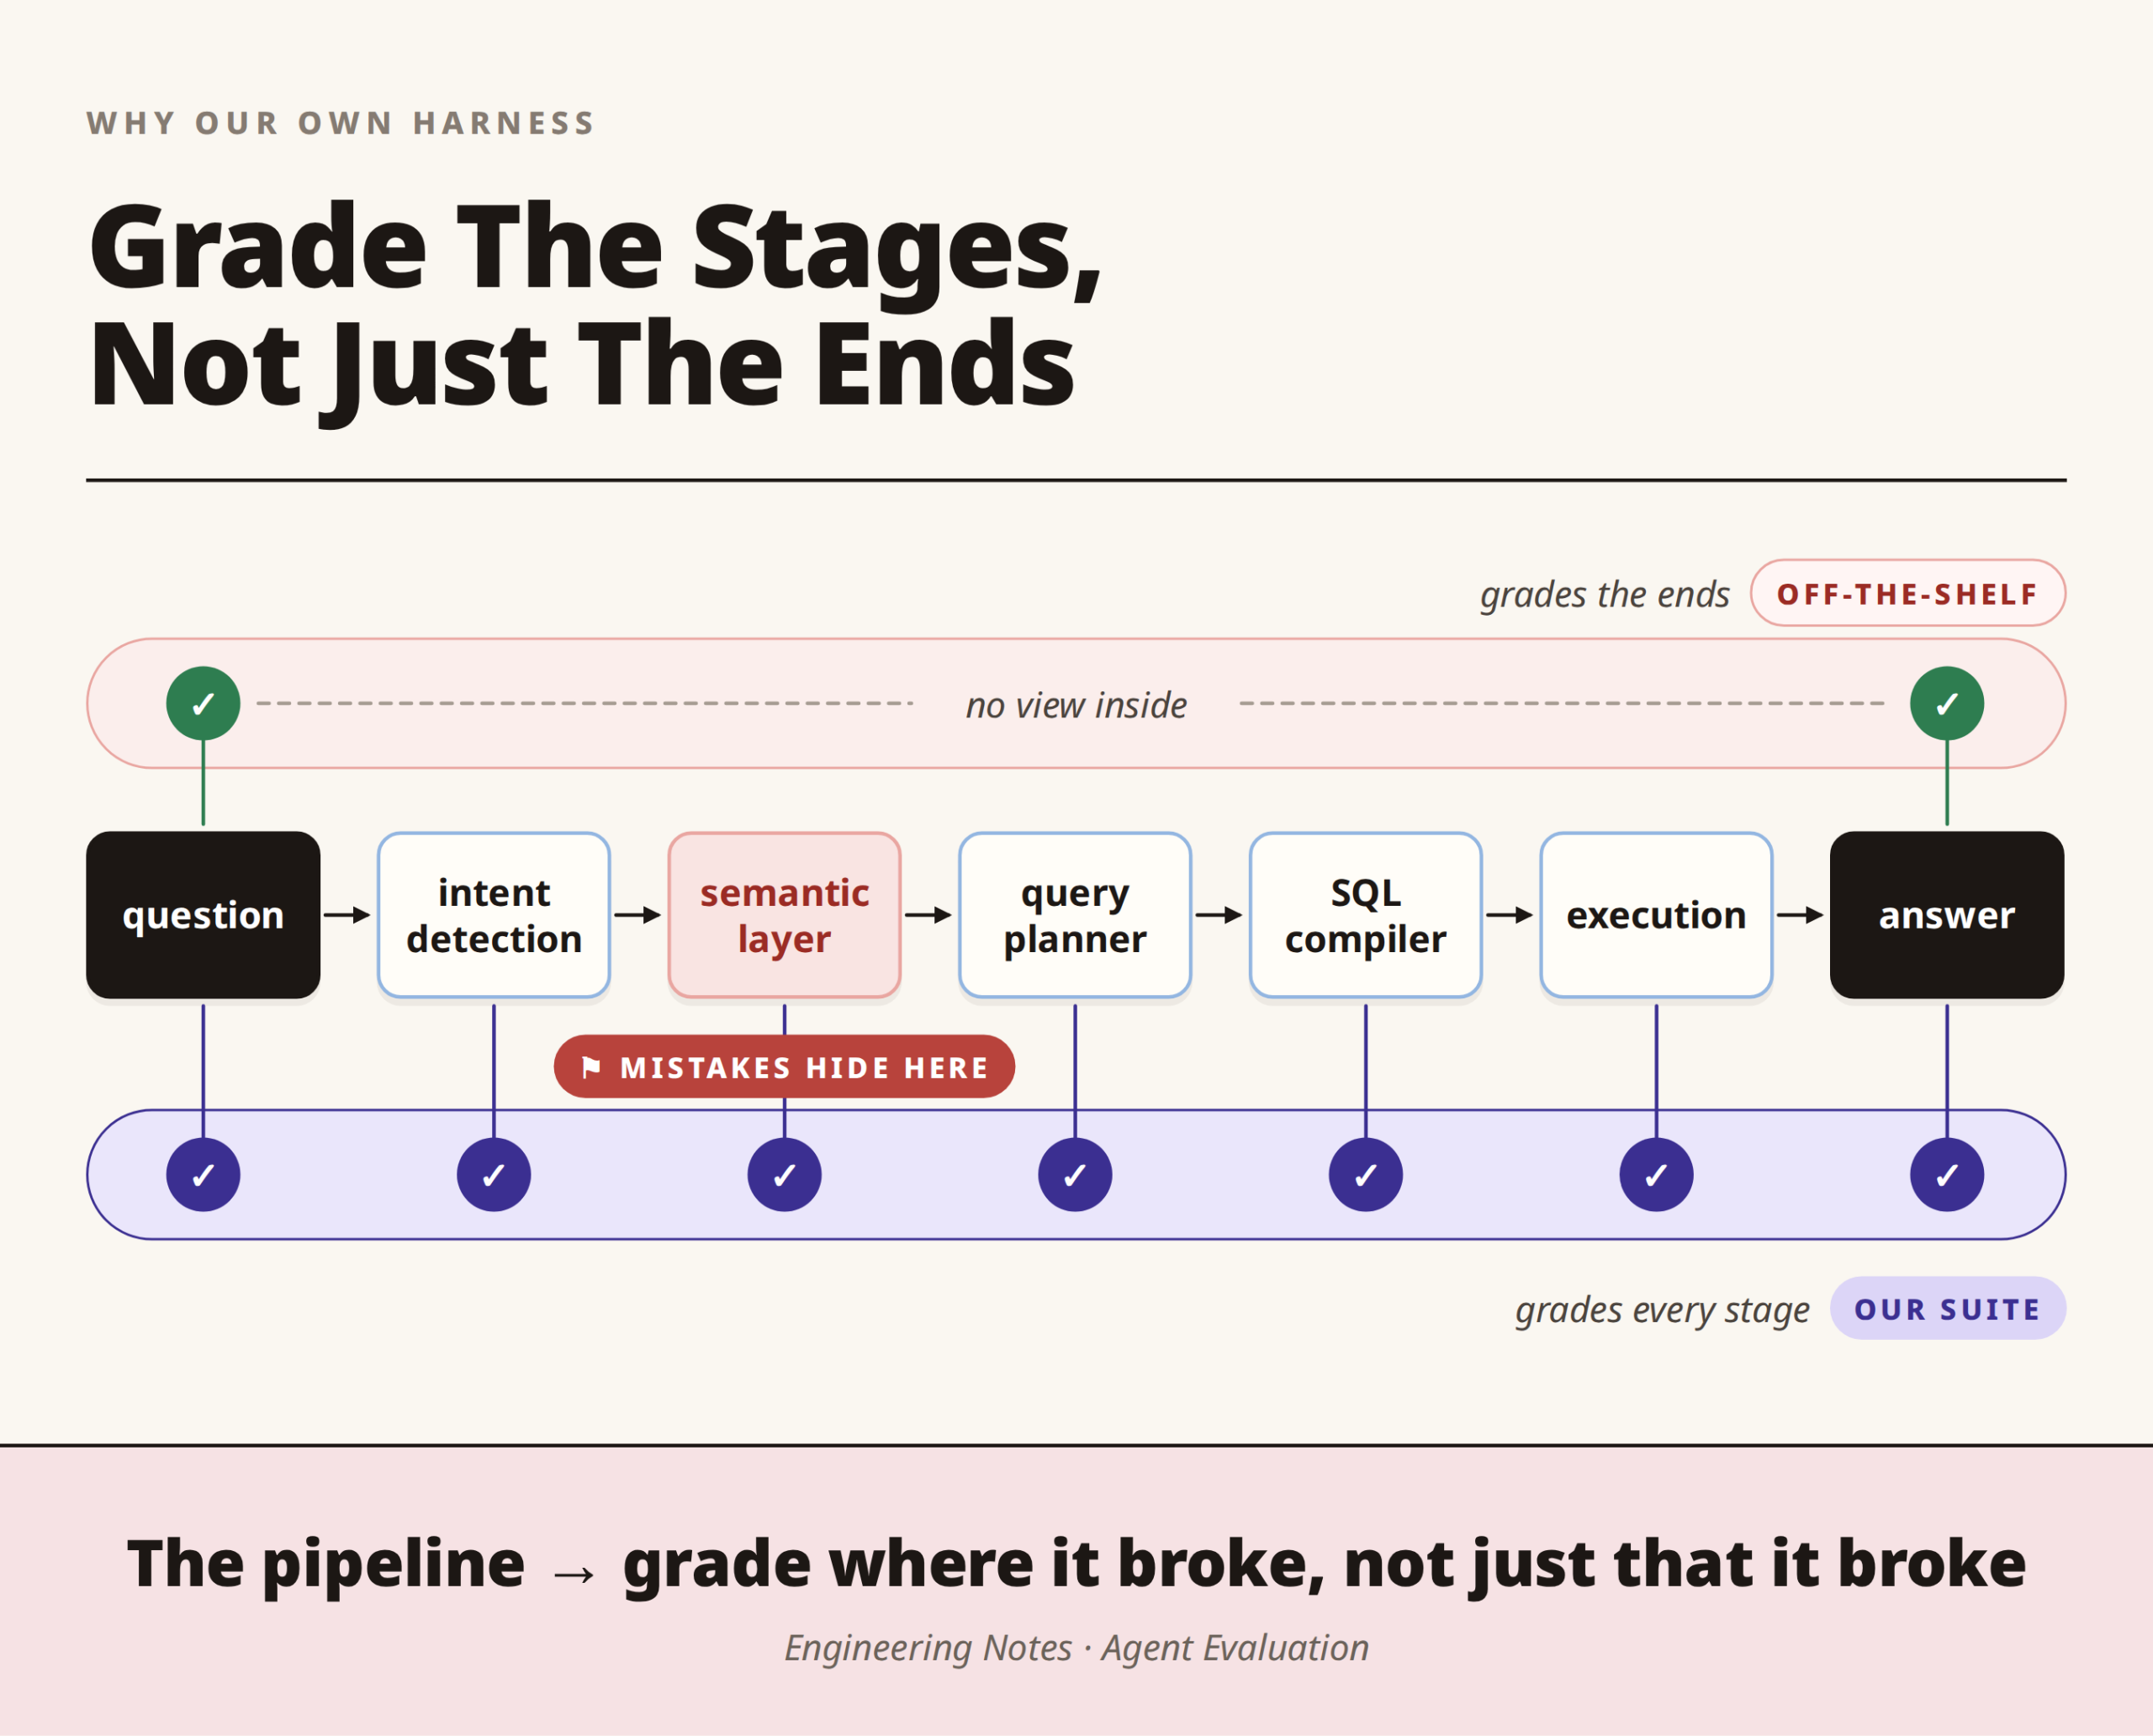
    • We needed to grade the stages, not just the ends. Our agent is a pipeline: intent detection, then a semantic layer that maps business words to database fields, then a query planner and a SQL compiler, and only then execution. Off-the-shelf tools grade what goes in and what comes out, so they cannot see the semantic layer choosing the wrong mapping three stages before any SQL exists.
    • We needed to score the right to refuse. If a question is hopelessly vague, the agent should ask you to narrow it down, and if the data cannot answer it, the agent should say so instead of inventing a number. A tool that only compares result sets cannot express “the right move here was to refuse”.

    AI agent evaluation across the text-to-SQL pipeline: intent detection, semantic layer, query planner, SQL compiler, execution

    Introducing MindzEval

    MindzEval is our evaluation suite for the text-to-SQL agent. It keeps the RAGAS loop of measuring, analysing, and fixing, and adds what the tools could not give us:

    • It runs every test question through the full pipeline and grades each stage, not only the final answer.
    • It scores refusals alongside results, so a correct “please narrow this down” counts as a success.
    • It reports one number you can trust, broken down into named causes whenever that number falls.

    How MindzEval works: six design decisions

    Each decision below started as something that went wrong and ended as a rule MindzEval now follows. Decisions 1 to 3 make the score correct and useful, Decisions 4 and 5 cover our two needs, and Decision 6 makes sure MindzEval itself can be trusted.

    Decision 1: Compare results, not SQL text

    Why it matters

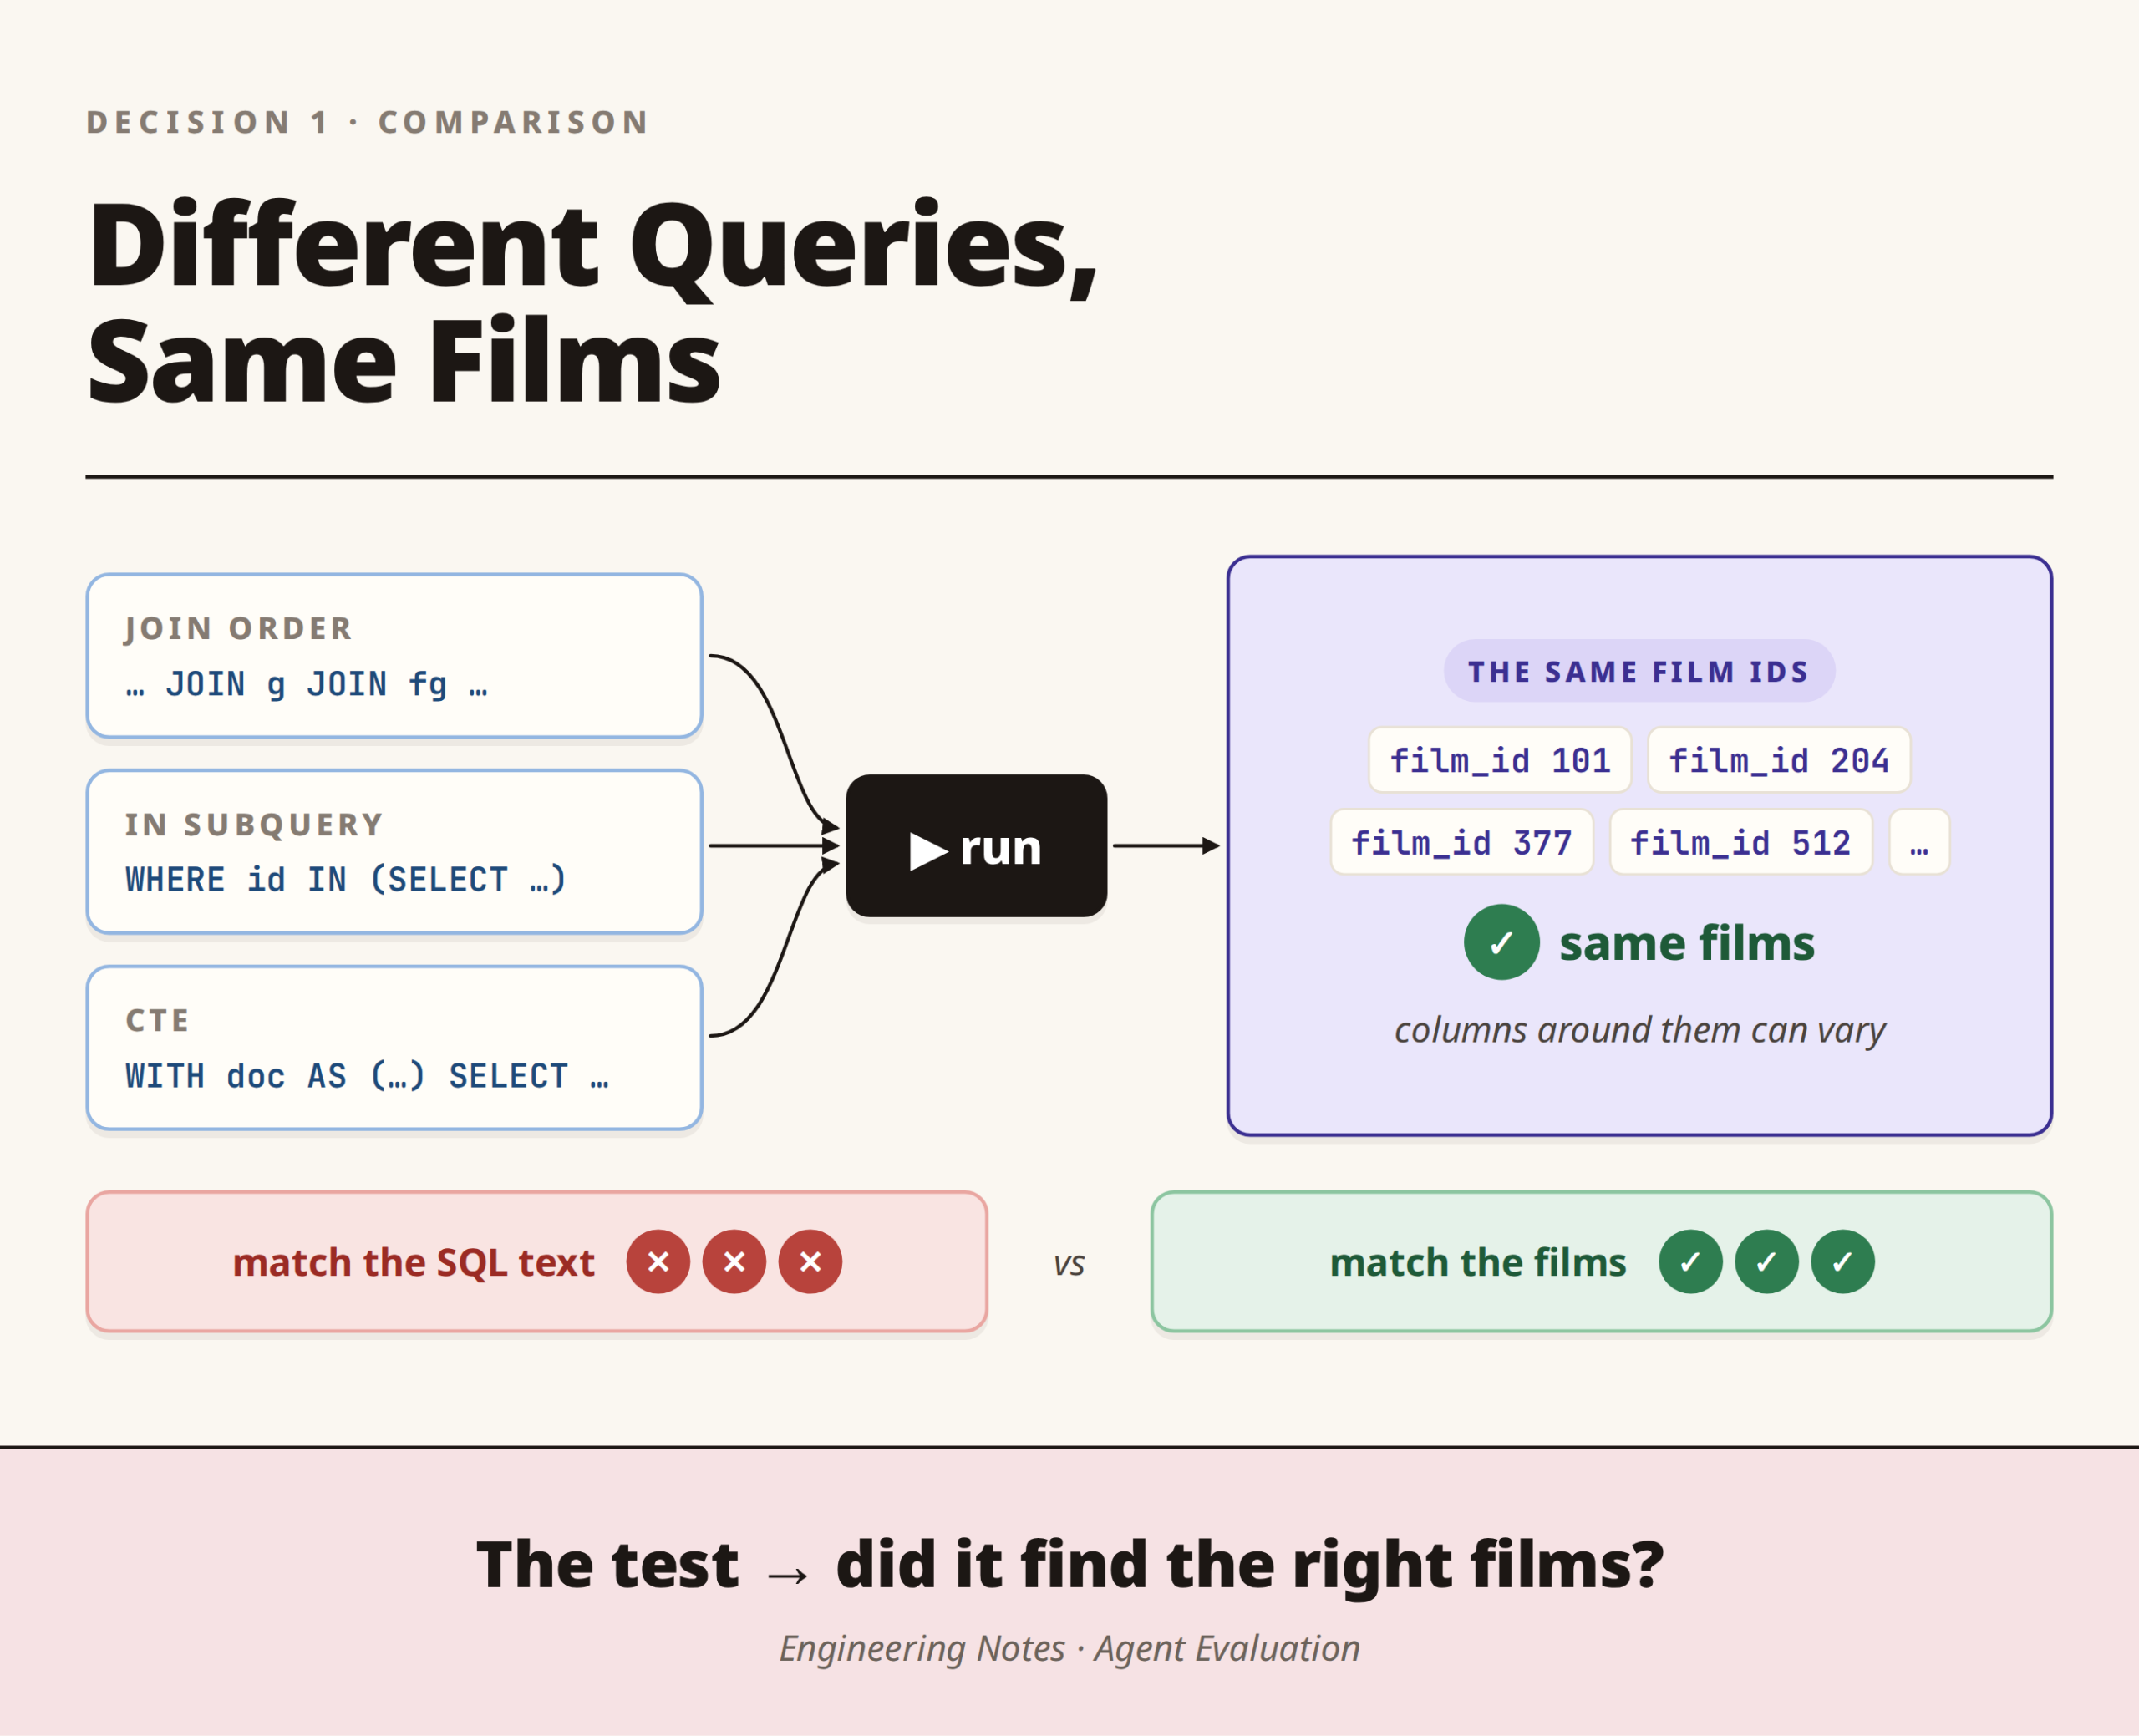
    Checking the agent’s SQL against ours letter by letter does not survive contact with reality, because the same query can be written many correct ways:

    • a different join order
    • IN instead of a subquery
    • a CTE instead of a nested SELECT

    All of them return identical data, yet all of them are “wrong” if you compare the text.

    What we did

    • We grade the answer, not the query. We run the known-correct query and the agent’s query, and check whether the two return the same films. The share of questions where they match is what we call execution accuracy.
    • Think of a maths exam. It is like marking by the final answer rather than insisting the working matches yours line for line: the returned films are the answer, and the SQL is the working.
    • We compare on identity, not whole rows. The agent returns different columns for different questions, sometimes just a title and sometimes a title, a release year, and a box office total. Every film has a stable id, film_id, in every row, so we compare the set of ids and let the columns vary freely. That asks the only question that matters: did it find the right films?

    Execution accuracy for LLM-generated SQL: compare query results, not SQL text, since different queries return the same rows

    Because “the same answer” differs by question type, the comparison has four shapes:

    Question type Example What we compare
    Filter “documentaries” The set of film ids
    Ranking “top 10 by box office” The ordered list of ids, with the set checked separately so we can tell “wrong films” from “right films, wrong order”
    Count “how many sci-fi films are there?” A single number
    Per-genre breakdown films grouped by genre The group totals

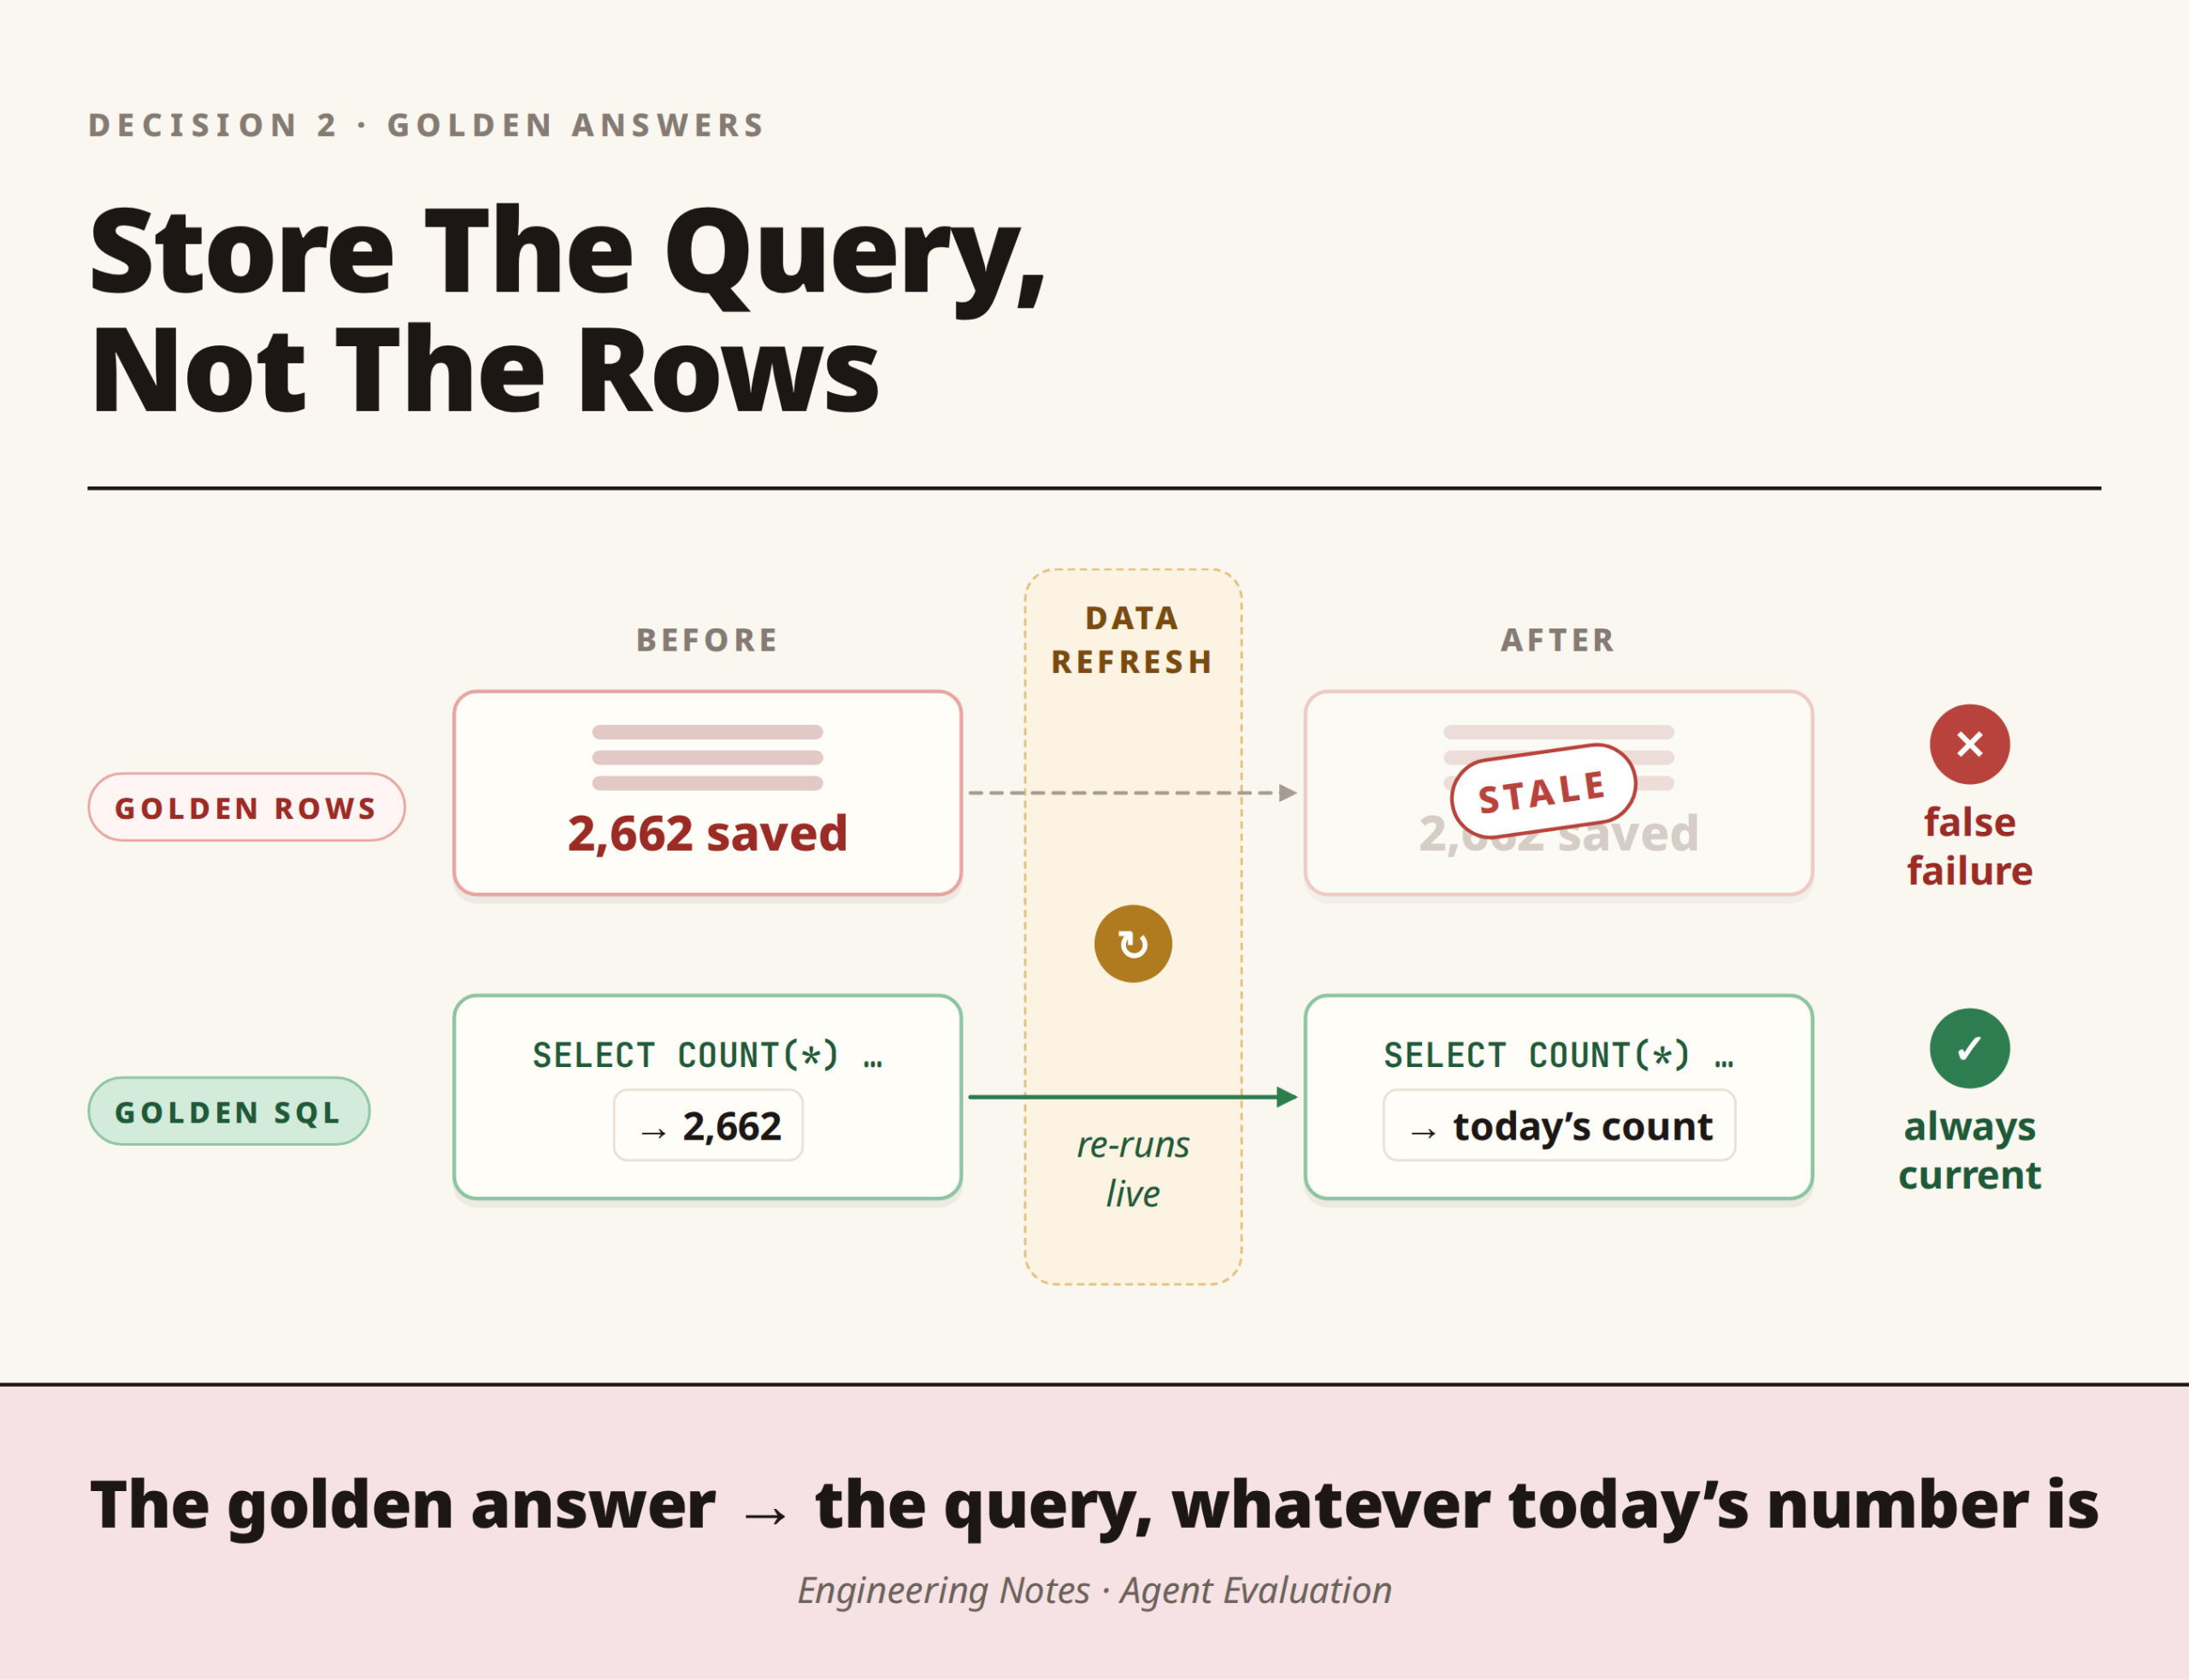
    Decision 2: Store the query, not the rows

    Why it matters

    The obvious approach is to save the list of films each question should return. However, the moment new data loads, every saved list goes out of date, and the suite fails on cases where the agent is perfectly fine. Consequently, you spend your mornings re-recording answers instead of fixing the agent.

    What we did

    • We store the known-correct SQL and run it fresh on every run, so the reference answers stay correct when the data refreshes.
    • The golden answer is the query, not the number. For “films from Spain”, it is not “2,662 films” but the query that counts them, whatever today’s number is.
    • Each case also records what each stage should produce, in its expect block, which is how MindzEval grades individual stages rather than only the output.

    Golden SQL vs golden rows in an LLM evaluation dataset: rerunning golden queries prevents false failures after data refresh

    A case ends up looking like this:

    - id: filter_documentary_001
      question: "Which documentaries are in the catalogue?"
      category: filter
      difficulty: easy
      golden_sql: |
        SELECT DISTINCT fg.film_id
        FROM public.v_film_genres fg
        JOIN public.v_genres g ON g.genre_id = fg.genre_id
        WHERE g.genre_label = 'Documentary';
      compare_on: film_id_set
      expect:
        semantic: {status: RESOLVED}
        plan: {operation_type: FILTER}
        terminal_status: SUCCESS

    There is a related trap: golden queries must use the values actually in the database.

    • The data says 'España', not “Spain”, and 'Sci-Fi & Fantasy', not “sci-fi”.
    • A question about wildlife and nature films once came back empty for exactly this reason, whereas it now returns the 37 films it should.

    As a result, a good chunk of the dataset is quietly a set of regression tests for bugs that actually happened.

    Decision 3: Break one number into several

    Why it matters

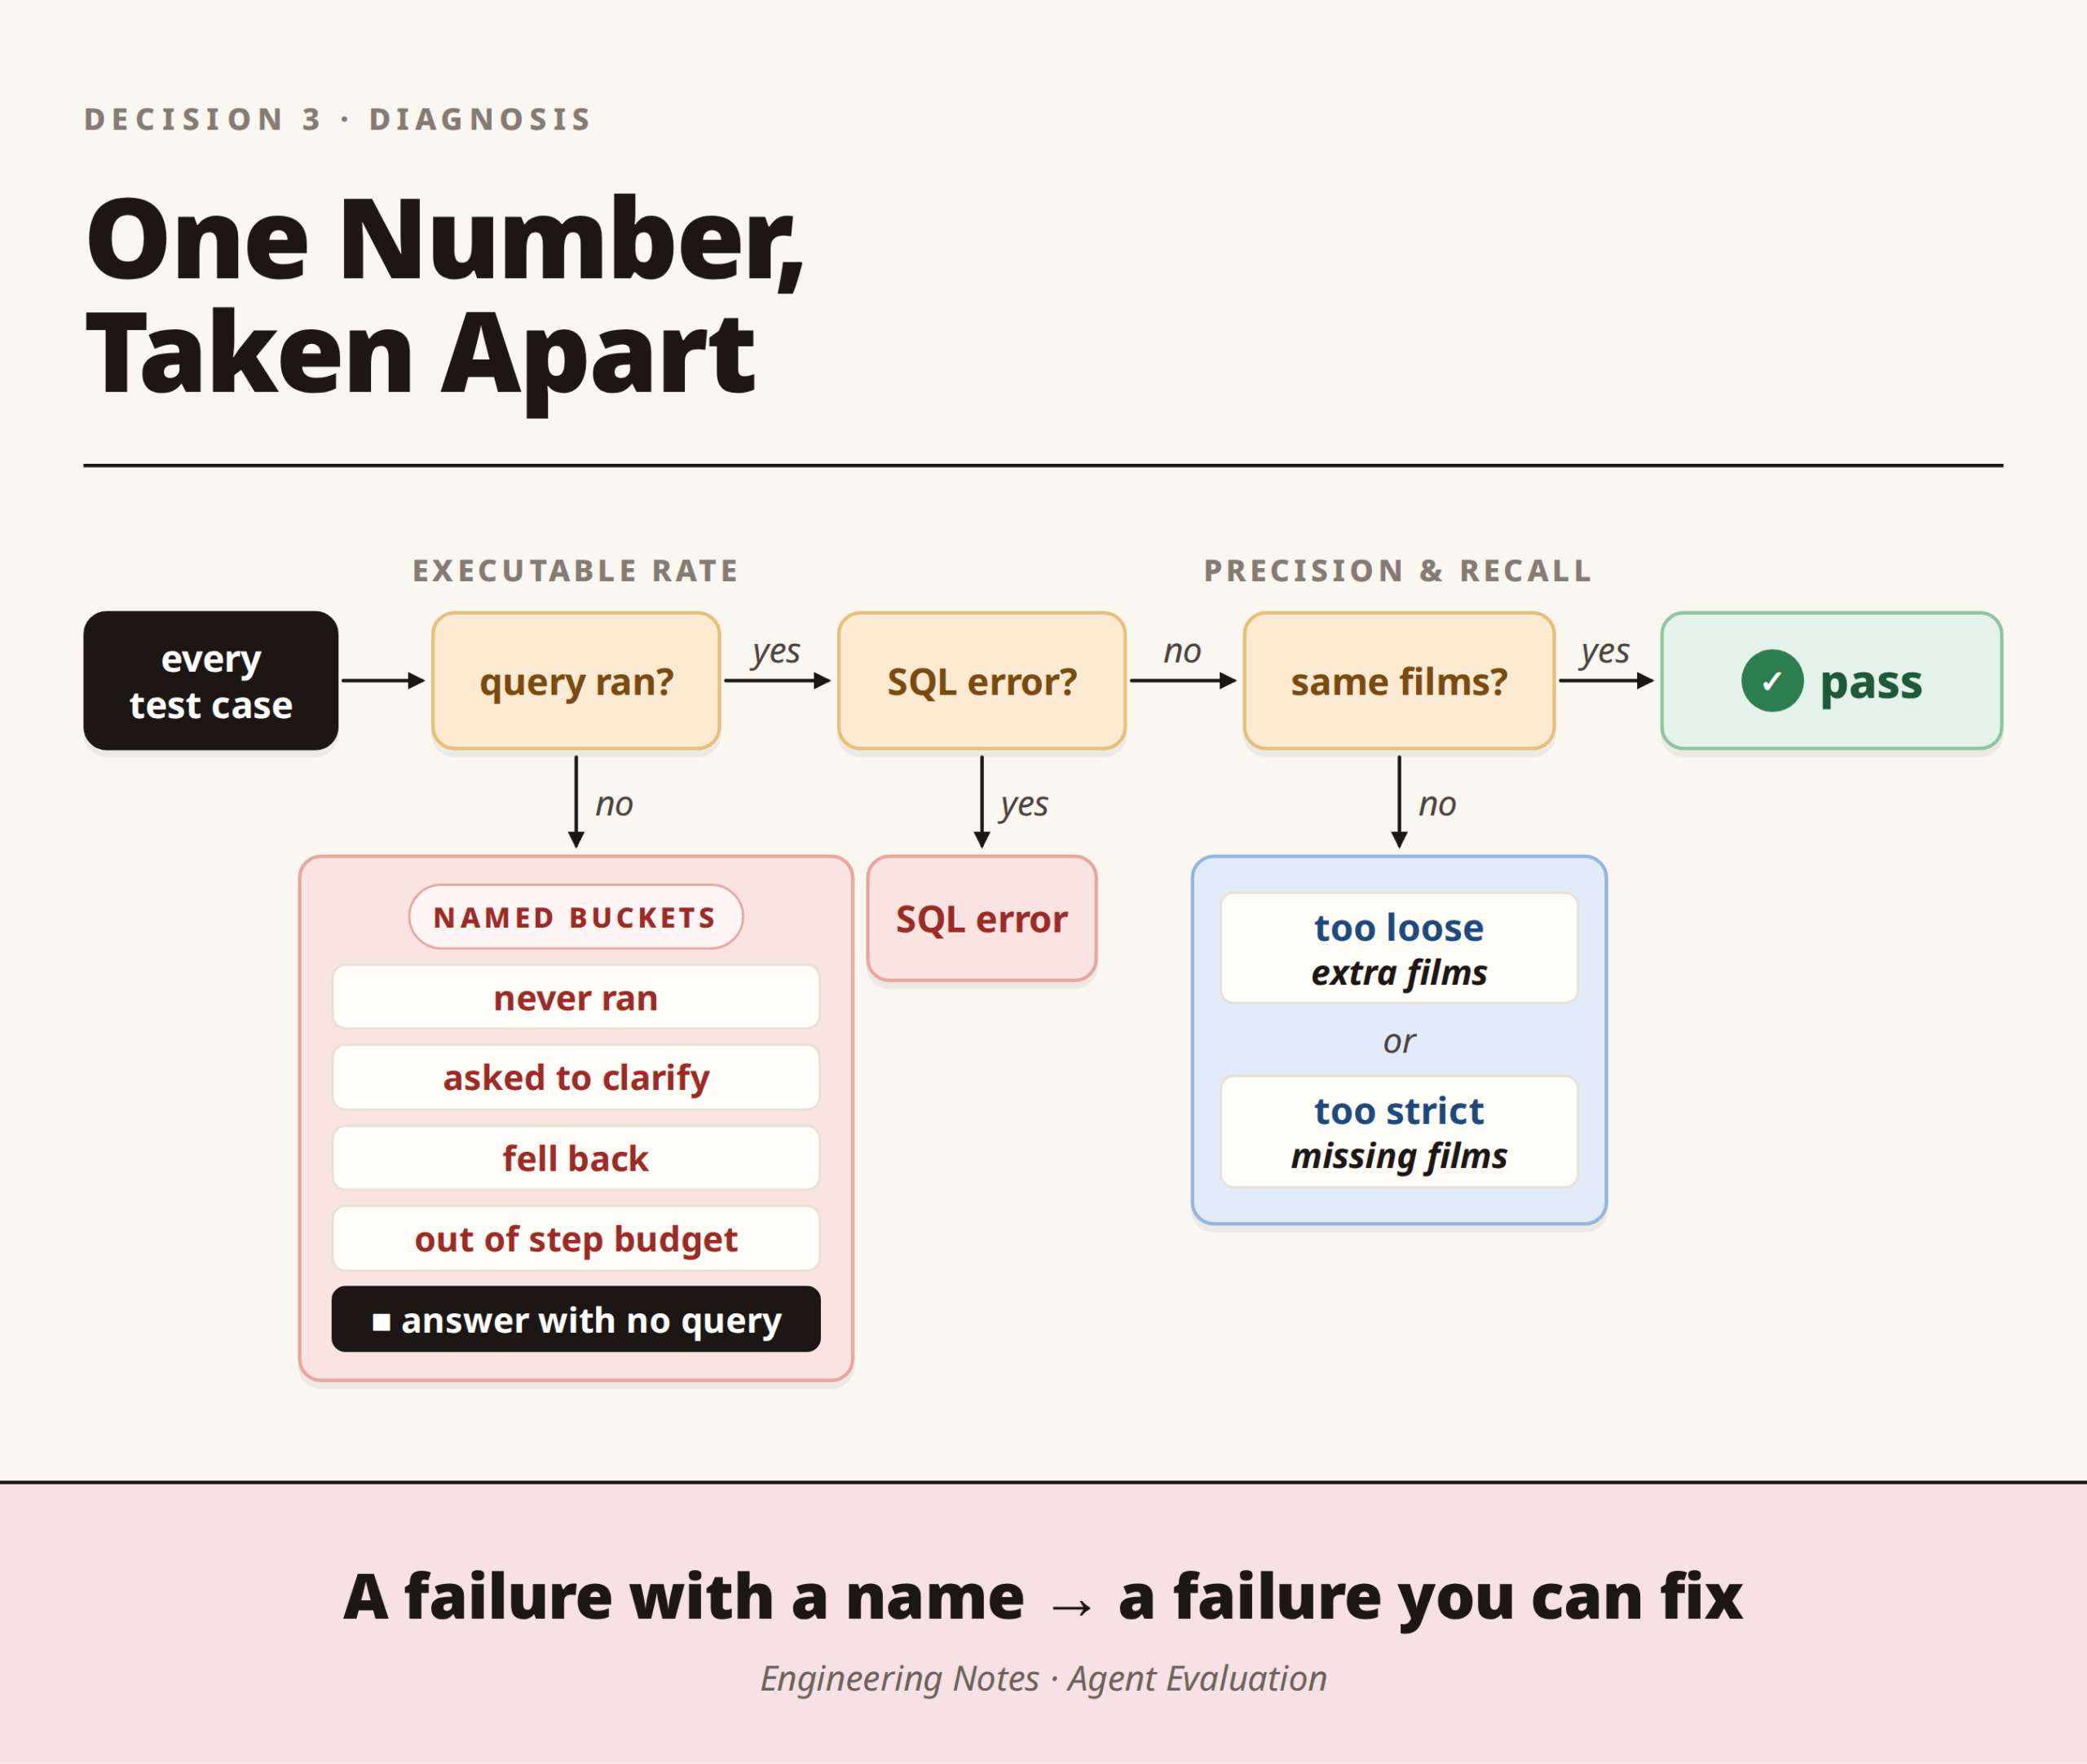
    “The agent is 7% accurate” is true but useless on its own. It does not say whether queries ran and returned the wrong thing or never ran at all, nor whether filters are too loose or too strict, so you cannot act on it.

    What we did

    • Executable rate answers “did the query even run?”, which separates a wrong answer from a broken one.
    • Precision and recall on the film sets show the direction of the error. High recall with low precision means the filter drags in extra films, while the reverse means it is too strict.
    • Failure buckets sort every failing case into exactly one named cause, because a failure with a name is a failure you can fix.
    • Slicing by question type and difficulty turns one headline figure into a sentence such as “94% on simple filters, 45% on multi-constraint aggregations” (an illustration of the format, not our current result), which actually decides what you work on next.
    Failure bucket What it means
    Query never ran The agent did not execute any SQL
    Asked for clarification The agent asked the user to narrow the question
    Fell back The agent took its fallback path instead of answering
    Ran out of step budget The agent hit its limit before finishing
    SQL error The query was executed but threw an error
    Confident answer, no query (hallucination path) The agent returned a successful-looking answer without running any query

    Text-to-SQL agent error analysis: executable rate, precision and recall, and failure buckets that expose AI hallucinations

    The last bucket matters most, because in a text-to-SQL system a number with no source behind it is the most dangerous output there is.

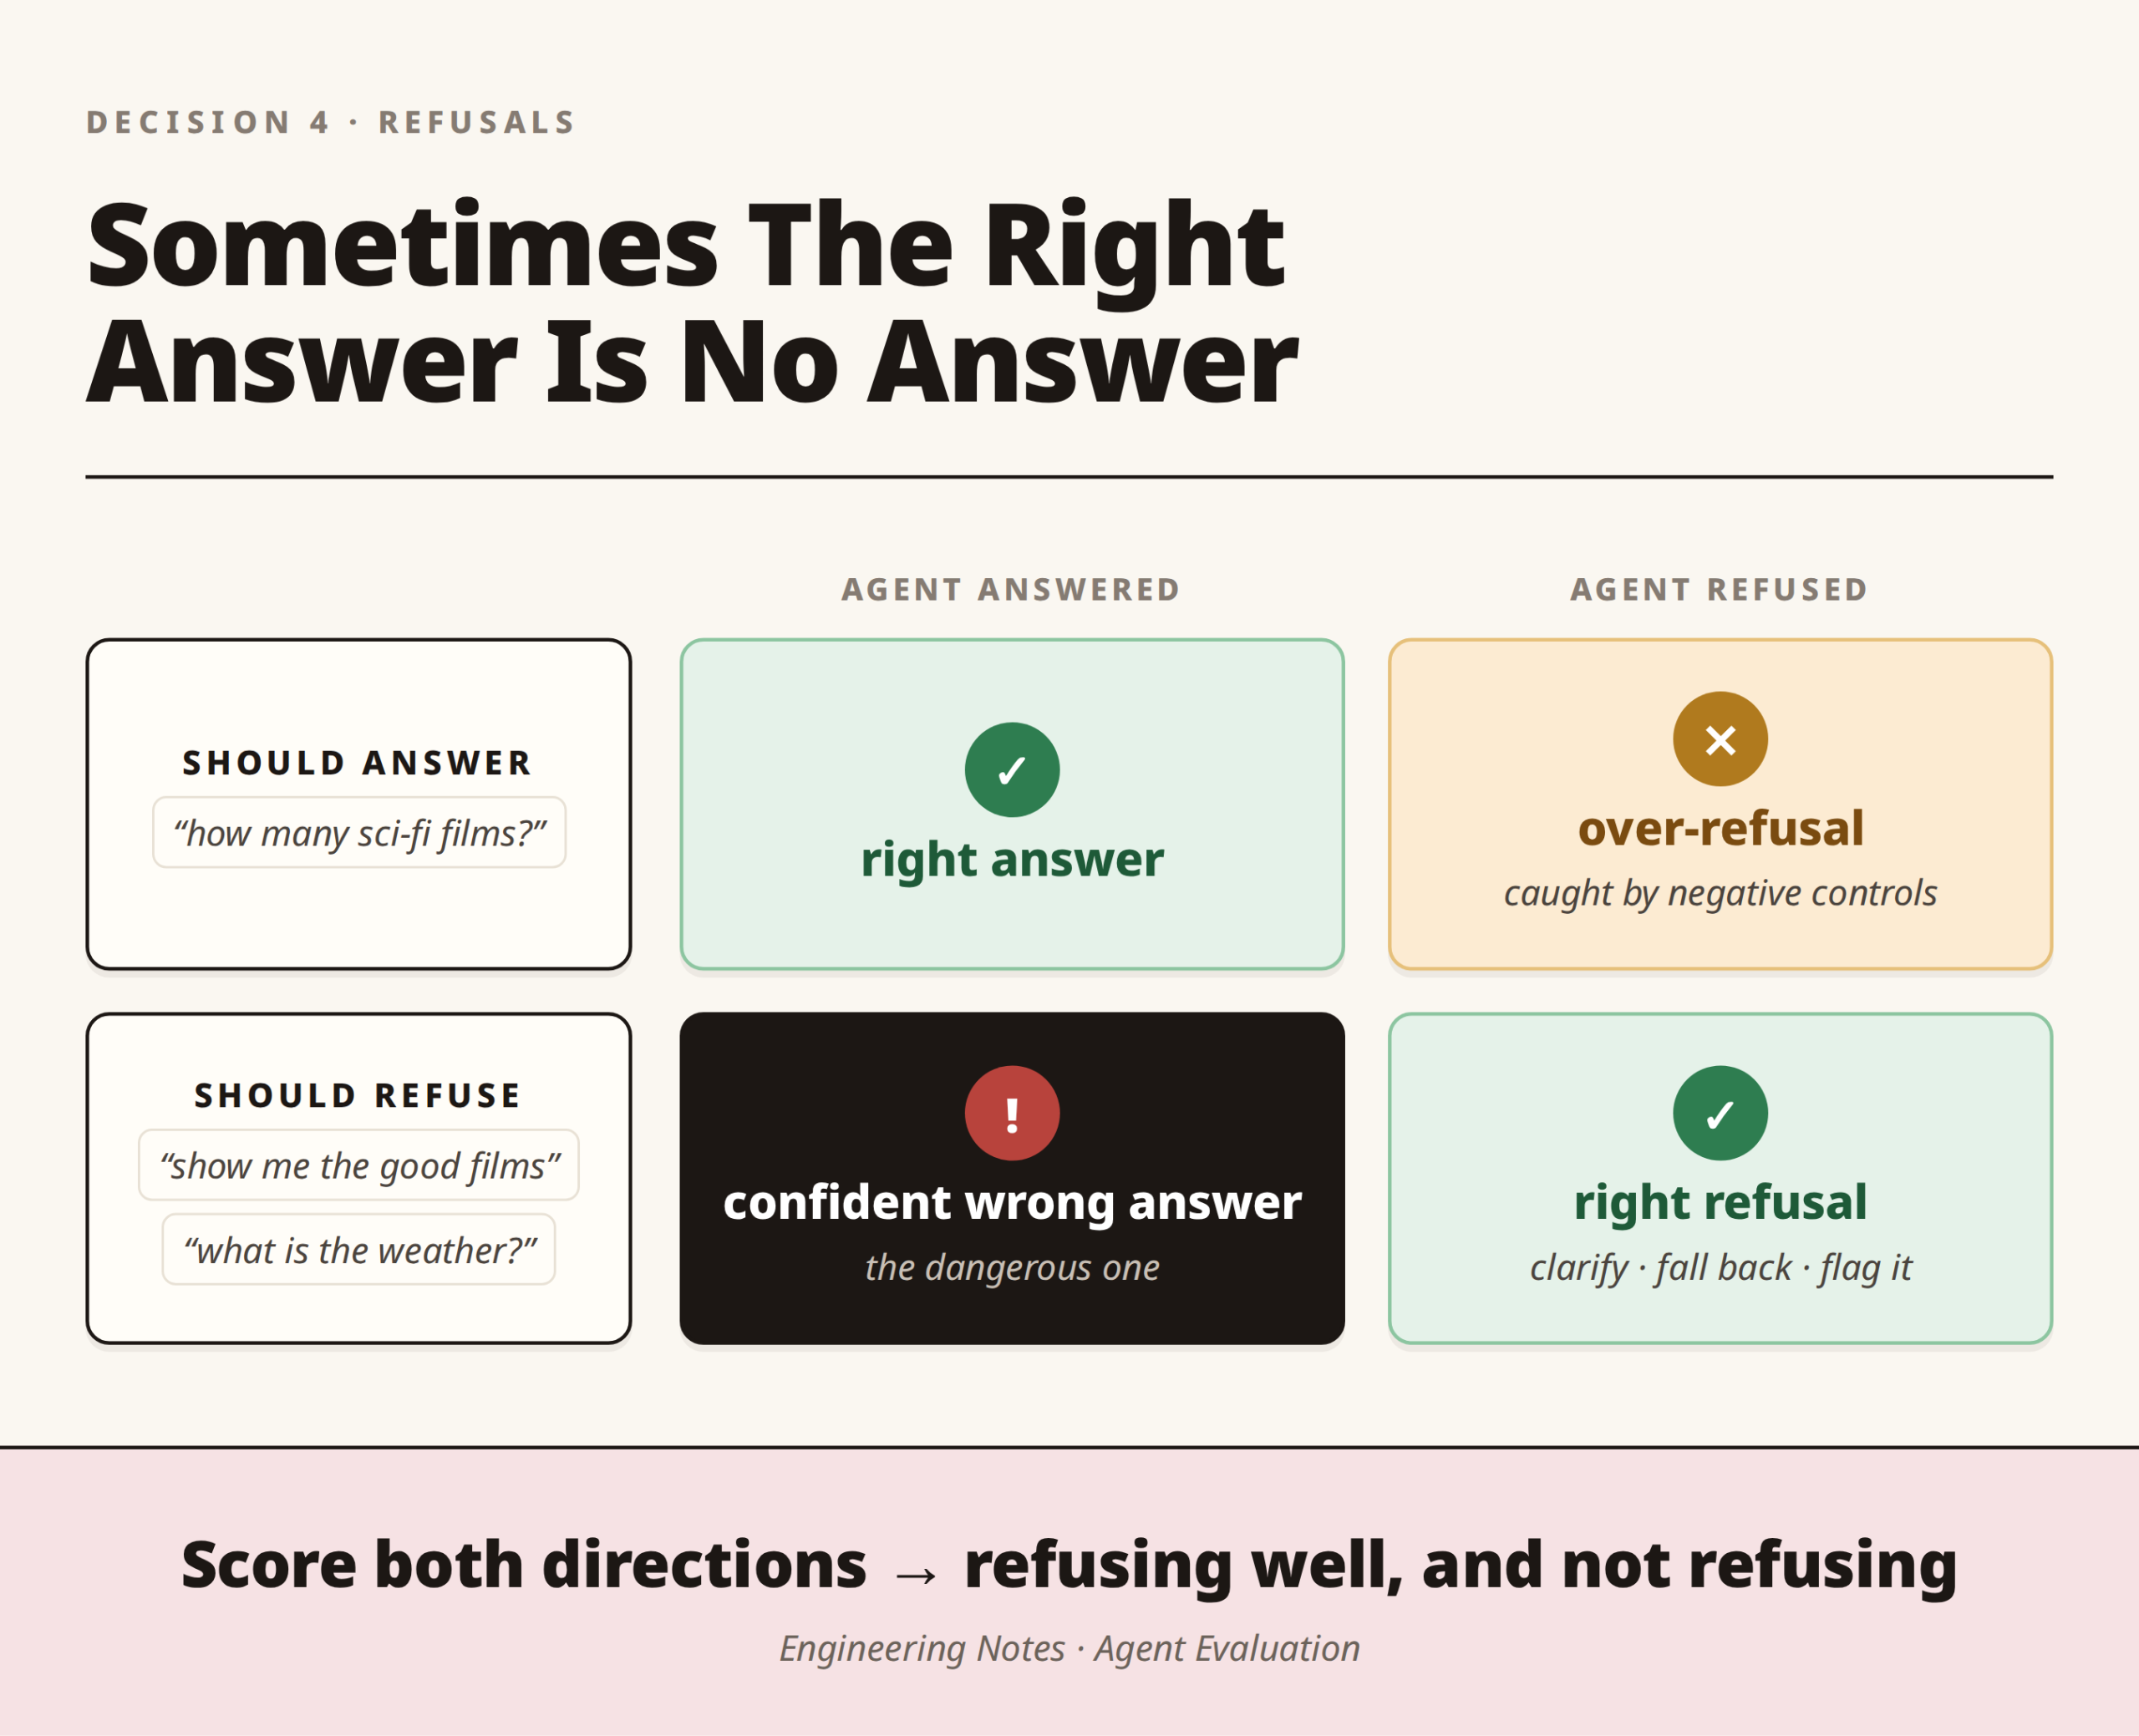
    Decision 4: Score refusals both ways

    Why it matters

    This is the second need from earlier: sometimes the right answer is no answer.

    • “Show me the good films” is too vague, so the agent should ask what “good” means.
    • “What is the weather” is out of scope, so it should decline rather than guess.

    A metric built on comparing rows cannot score these cases, and leaving them out creates a blind spot exactly where a confident wrong answer does the most damage.

    What we did

    • A separate behavioural score checks whether the agent asked for clarification, fell back gracefully, or flagged a concept as unsupported when it should have.
    • It scores both directions. An agent that asked for clarification on every question would score perfectly and yet be useless.
    • Negative controls catch over-refusal. These are questions the agent should simply answer, and we score them too, because knowing when not to refuse is as much a skill as knowing when to refuse.

    Evaluating AI agent refusals: correct answers, over-refusal, confident wrong answers (hallucinations), and correct clarification

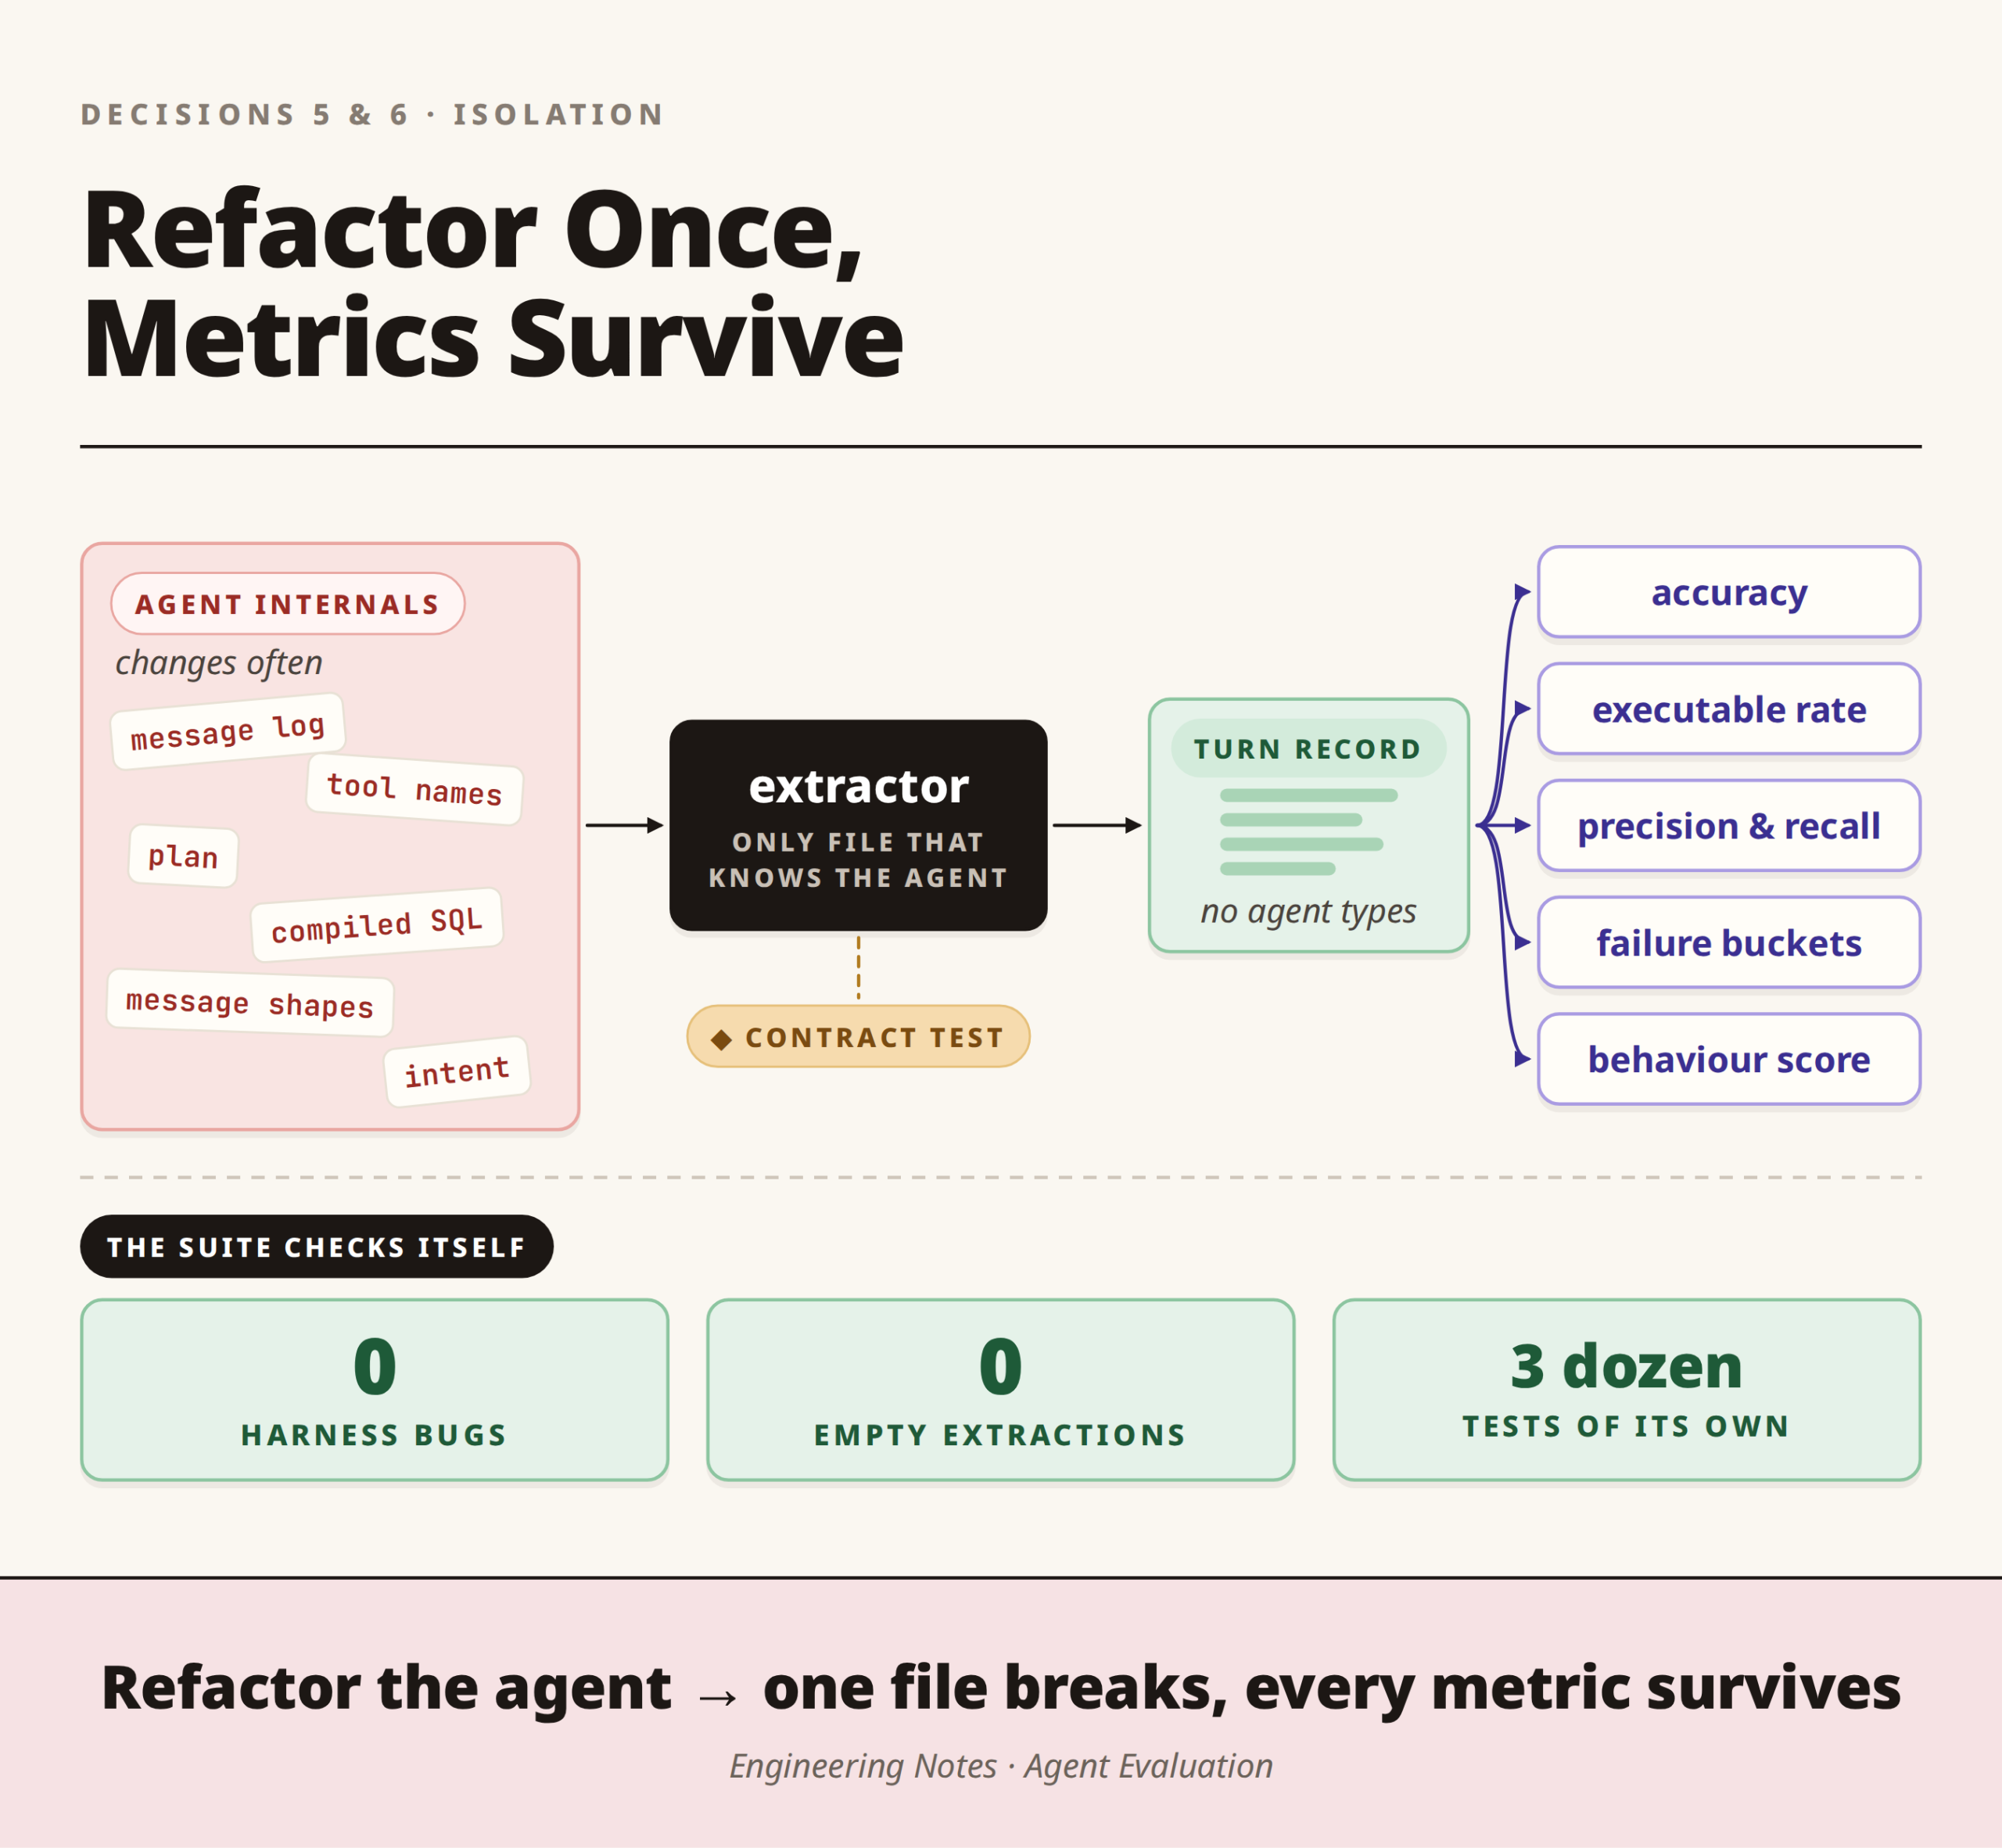
    Decision 5: Let one file know the agent

    Why it matters

    Grading every stage, our first need, means reading the agent’s intermediate results: what it understood, the plan it built, and the SQL it compiled. However, these are buried in its message log, and digging them out depends on exact tool names and message shapes. Since the agent is under active development, that knowledge goes stale the instant someone refactors.

    What we did

    • Every metric reads from a normalised turn record, a clean record of one turn that contains no agent-specific types.
    • Exactly one module builds that record, and it is the only file in MindzEval allowed to import the agent or name a tool. As a result, a refactor breaks one file instead of every metric.
    • One run serves every metric, so we never pay to re-run the agent for each one.
    • A small test guards that file by checking that it still recognises the agent’s real tool names.

    Although that test sounds trivial, it caught a real bug: code looking for a tool called semantic_resolver, which does not exist, had left an entire stage silently empty.

    Decision 6: Make the suite check itself

    Why it matters

    A measuring instrument can be broken too. If the extractor silently returned nothing, every metric would read zero, and it would look as though the agent had got much worse overnight. A number you cannot trust is worse than no number, because you will act on it with confidence.

    What we did

    • Two counts top every report: failures caused by bugs in our own harness, and failures caused by an empty extractor. Both are currently zero, which is how we know the score is real.
    • Crashes are attributed, so an agent bug is filed as a finding and our bug is filed as ours.
    • The harness has three dozen tests of its own, because the ruler needs its own ruler.

    LLM evaluation harness design: one extractor isolates agent internals so metrics survive refactors, with regression tests

    What did the first baseline tell us?

    When we ran MindzEval, the first full baseline came back at about 7% execution accuracy. We read that as good news, because a low number that breaks into named, fixable causes means the instrument is measuring something real. After all, the number’s job is not to be high on day one but to move and to say why when it does not.

    Finding Cases What it means
    Truncated, but everything returned was correct. 30 The 50-row display cap made a full match impossible even though the agent’s logic was right.
    Answerable questions not answered from a real query 35 The agent fell back or asked to clarify instead of just querying
    Of which: confident “success” with no query run 11 The hallucination path

    Two structural issues, rather than reasoning failures, dominated the score:

    • A display setting. The agent caps results at 50 rows, but our reference answer for “sci-fi films” is 215. It returned 50 correct films, so the cap alone made a full match impossible. MindzEval reports this as its own category, and it accounted for 30 cases.
    • The agent holding back. On 35 answerable questions, the agent did not answer from a real query, and it mostly fell back or asked for clarification. However, 11 of those 35 returned a confident “success” without running any query, which we would never have spotted by reading answers.

    In other words, instead of “the agent is 93% broken”, we got a to-do list.

    How we run it day to day

    • On every change, we run a fast slice of ten cases, which takes about seven minutes.
    • Every night, we run the full set of one hundred cases.
    • Later, DeepEval comes back in, both for wiring MindzEval into CI and for an optional judge that checks whether the final wording invents anything the data does not support.

    The core, however, stays ours, because no framework can see inside our agent or say that refusing was the right call.

    The lesson

    Grade the thing that matters, not the thing that is easy to compare. Matching SQL text is precise but wrong, whereas checking whether the agent found the right films is the only number worth trusting. A number you can check yourself, even an ugly one, beats a confident feeling every time.

    Want to know whether your agent is right, not just whether it looks right?

    MindzEval grades every stage of a text-to-SQL pipeline, scores refusals in both directions, and checks its own results on every run. To find out what it could reveal about your agent, call us on +91 85957 97775.