Since we wrote about MindzEval in Part 1 and Part 2, one question has come up again and again: there are already plenty of eval tools, so why build another one?
To answer it, we reviewed more than 30 eval tools, platforms and benchmarks, as of October 2026. This post shares what we found, what MindzEval does differently, and where we are still behind.
What is already out there
Most of the tools we looked at fall into three groups. Each one is good at something, but each one also leaves a gap for teams testing a SQL agent.
| Type of tool | What it does well | What is missing for SQL agents |
|---|---|---|
| General AI eval platforms such as DeepEval and LangSmith |
Great dashboards, datasets and CI | They are built for any AI app, so there is no built-in check that runs the SQL and compares the data. Teams write that part themselves or use an AI judge. |
| Data platform built-ins such as Snowflake and Databricks |
Free and well integrated | They only test their own agent. If you move off the platform, you lose your yardstick. |
| Open-source SQL tools and benchmarks | Some do run the SQL and compare the results | Each one covers only a piece of the job, and benchmarks run on public databases, not yours. |
In other words, running the SQL and comparing results is not unique to us. What is missing is one tool that does the whole job, for any SQL agent, on your own database.
What we are trying to build
Our goal is simple: one number a team can trust for its SQL agent. In practice, that number should:
- Be checkable, so you can see exactly how it was worked out.
- Stay comparable over time, so you can compare this month’s number with last month’s.
- Point to the cause, so a lower score comes with a reason.
- Work on any Text-to-SQL agent and any database, not just one vendor’s.
So rather than a feature tied to one platform, we want MindzEval to be a neutral standard.
What MindzEval does differently
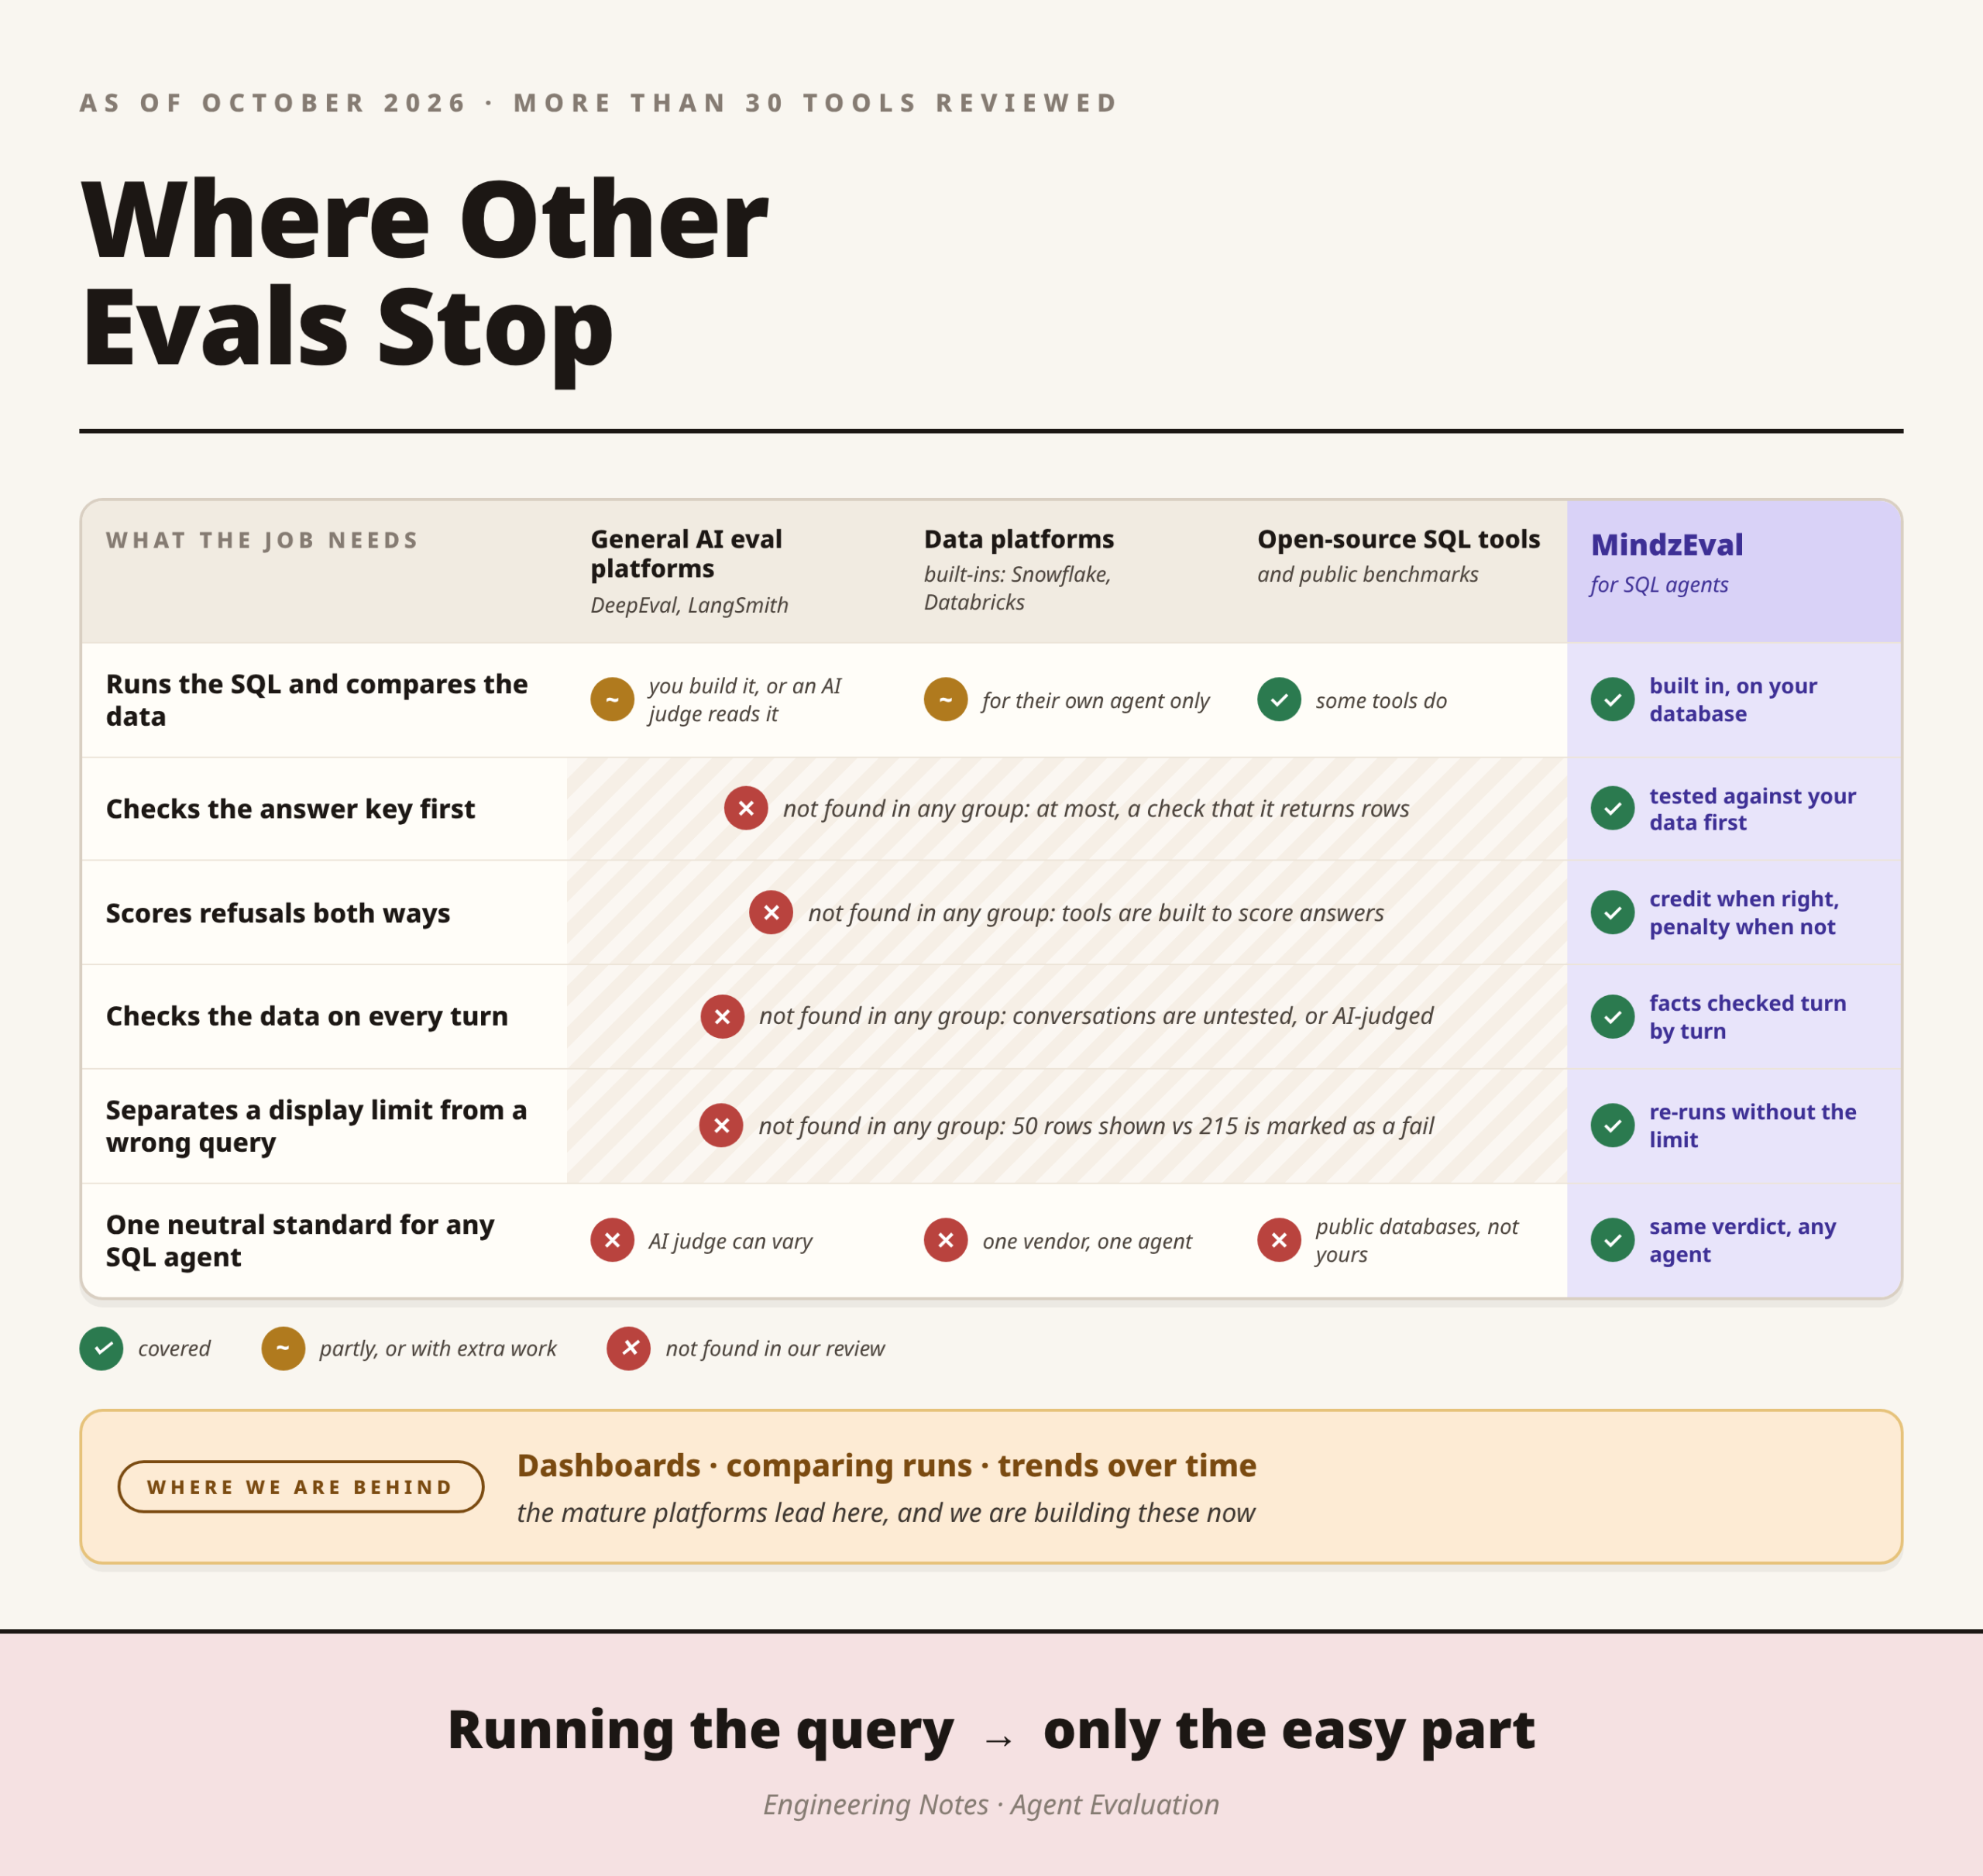
We did not find any of the following five things in the tools we reviewed.
1. It checks the answer key before grading the agent
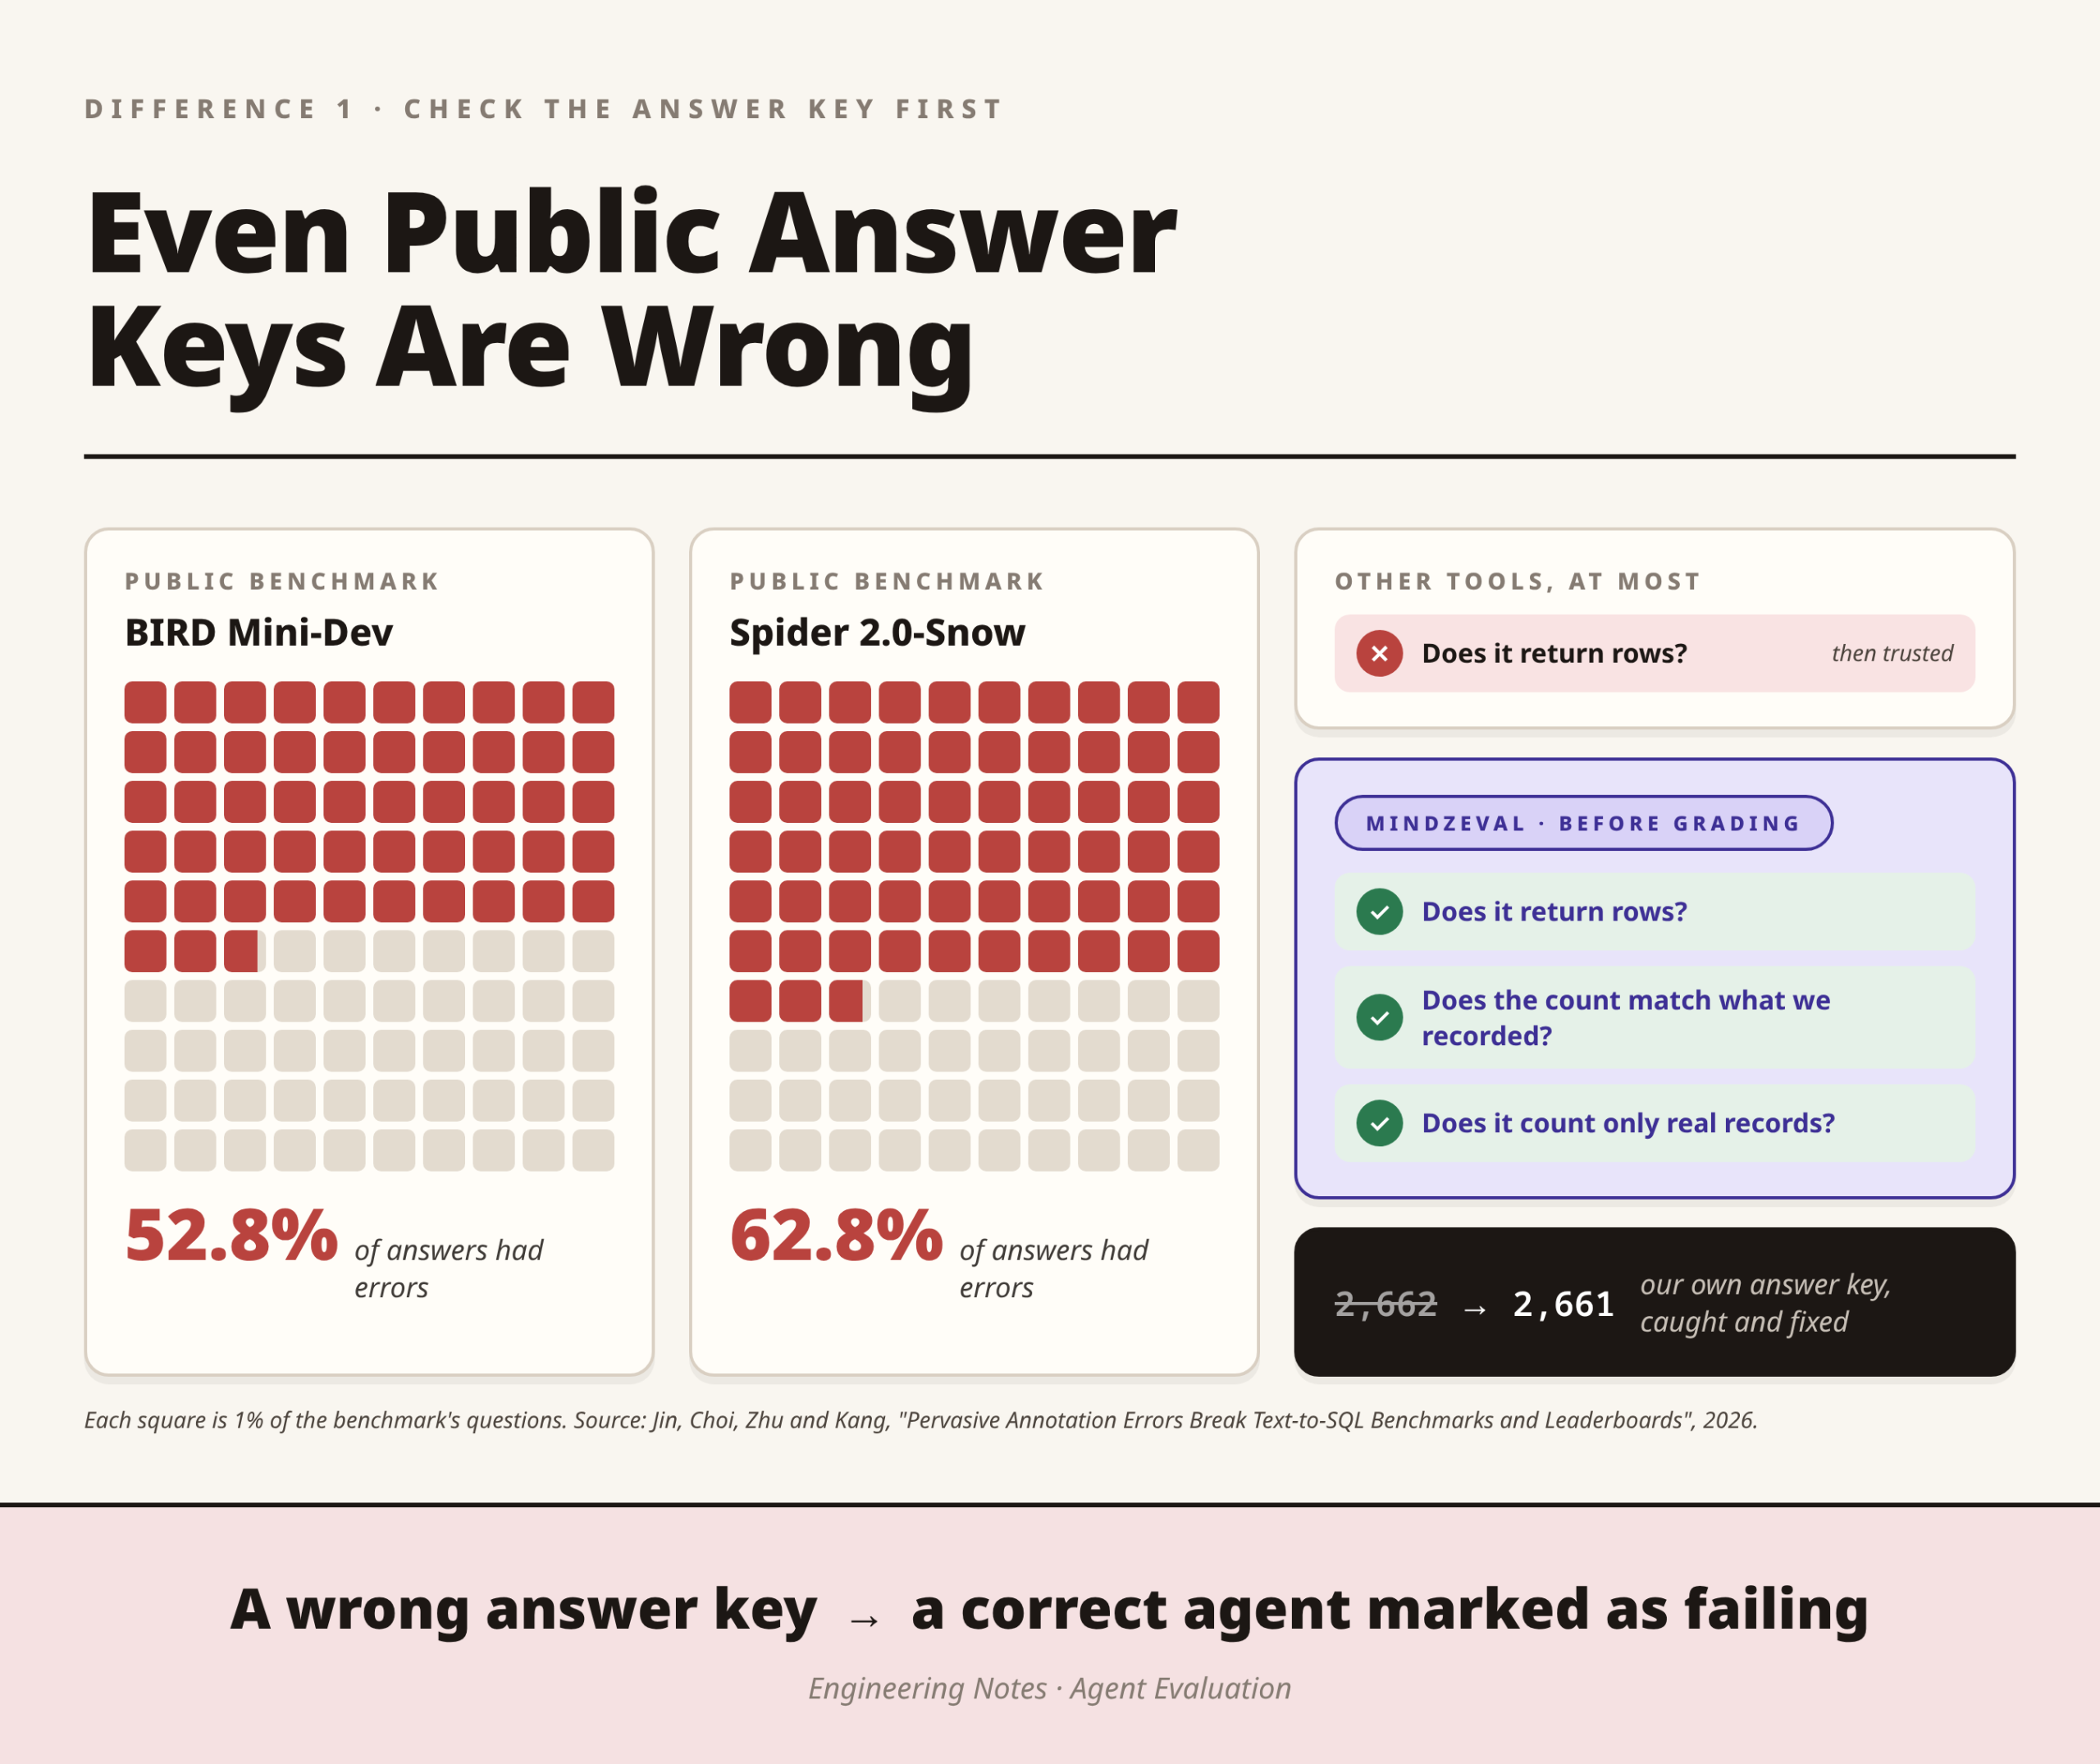
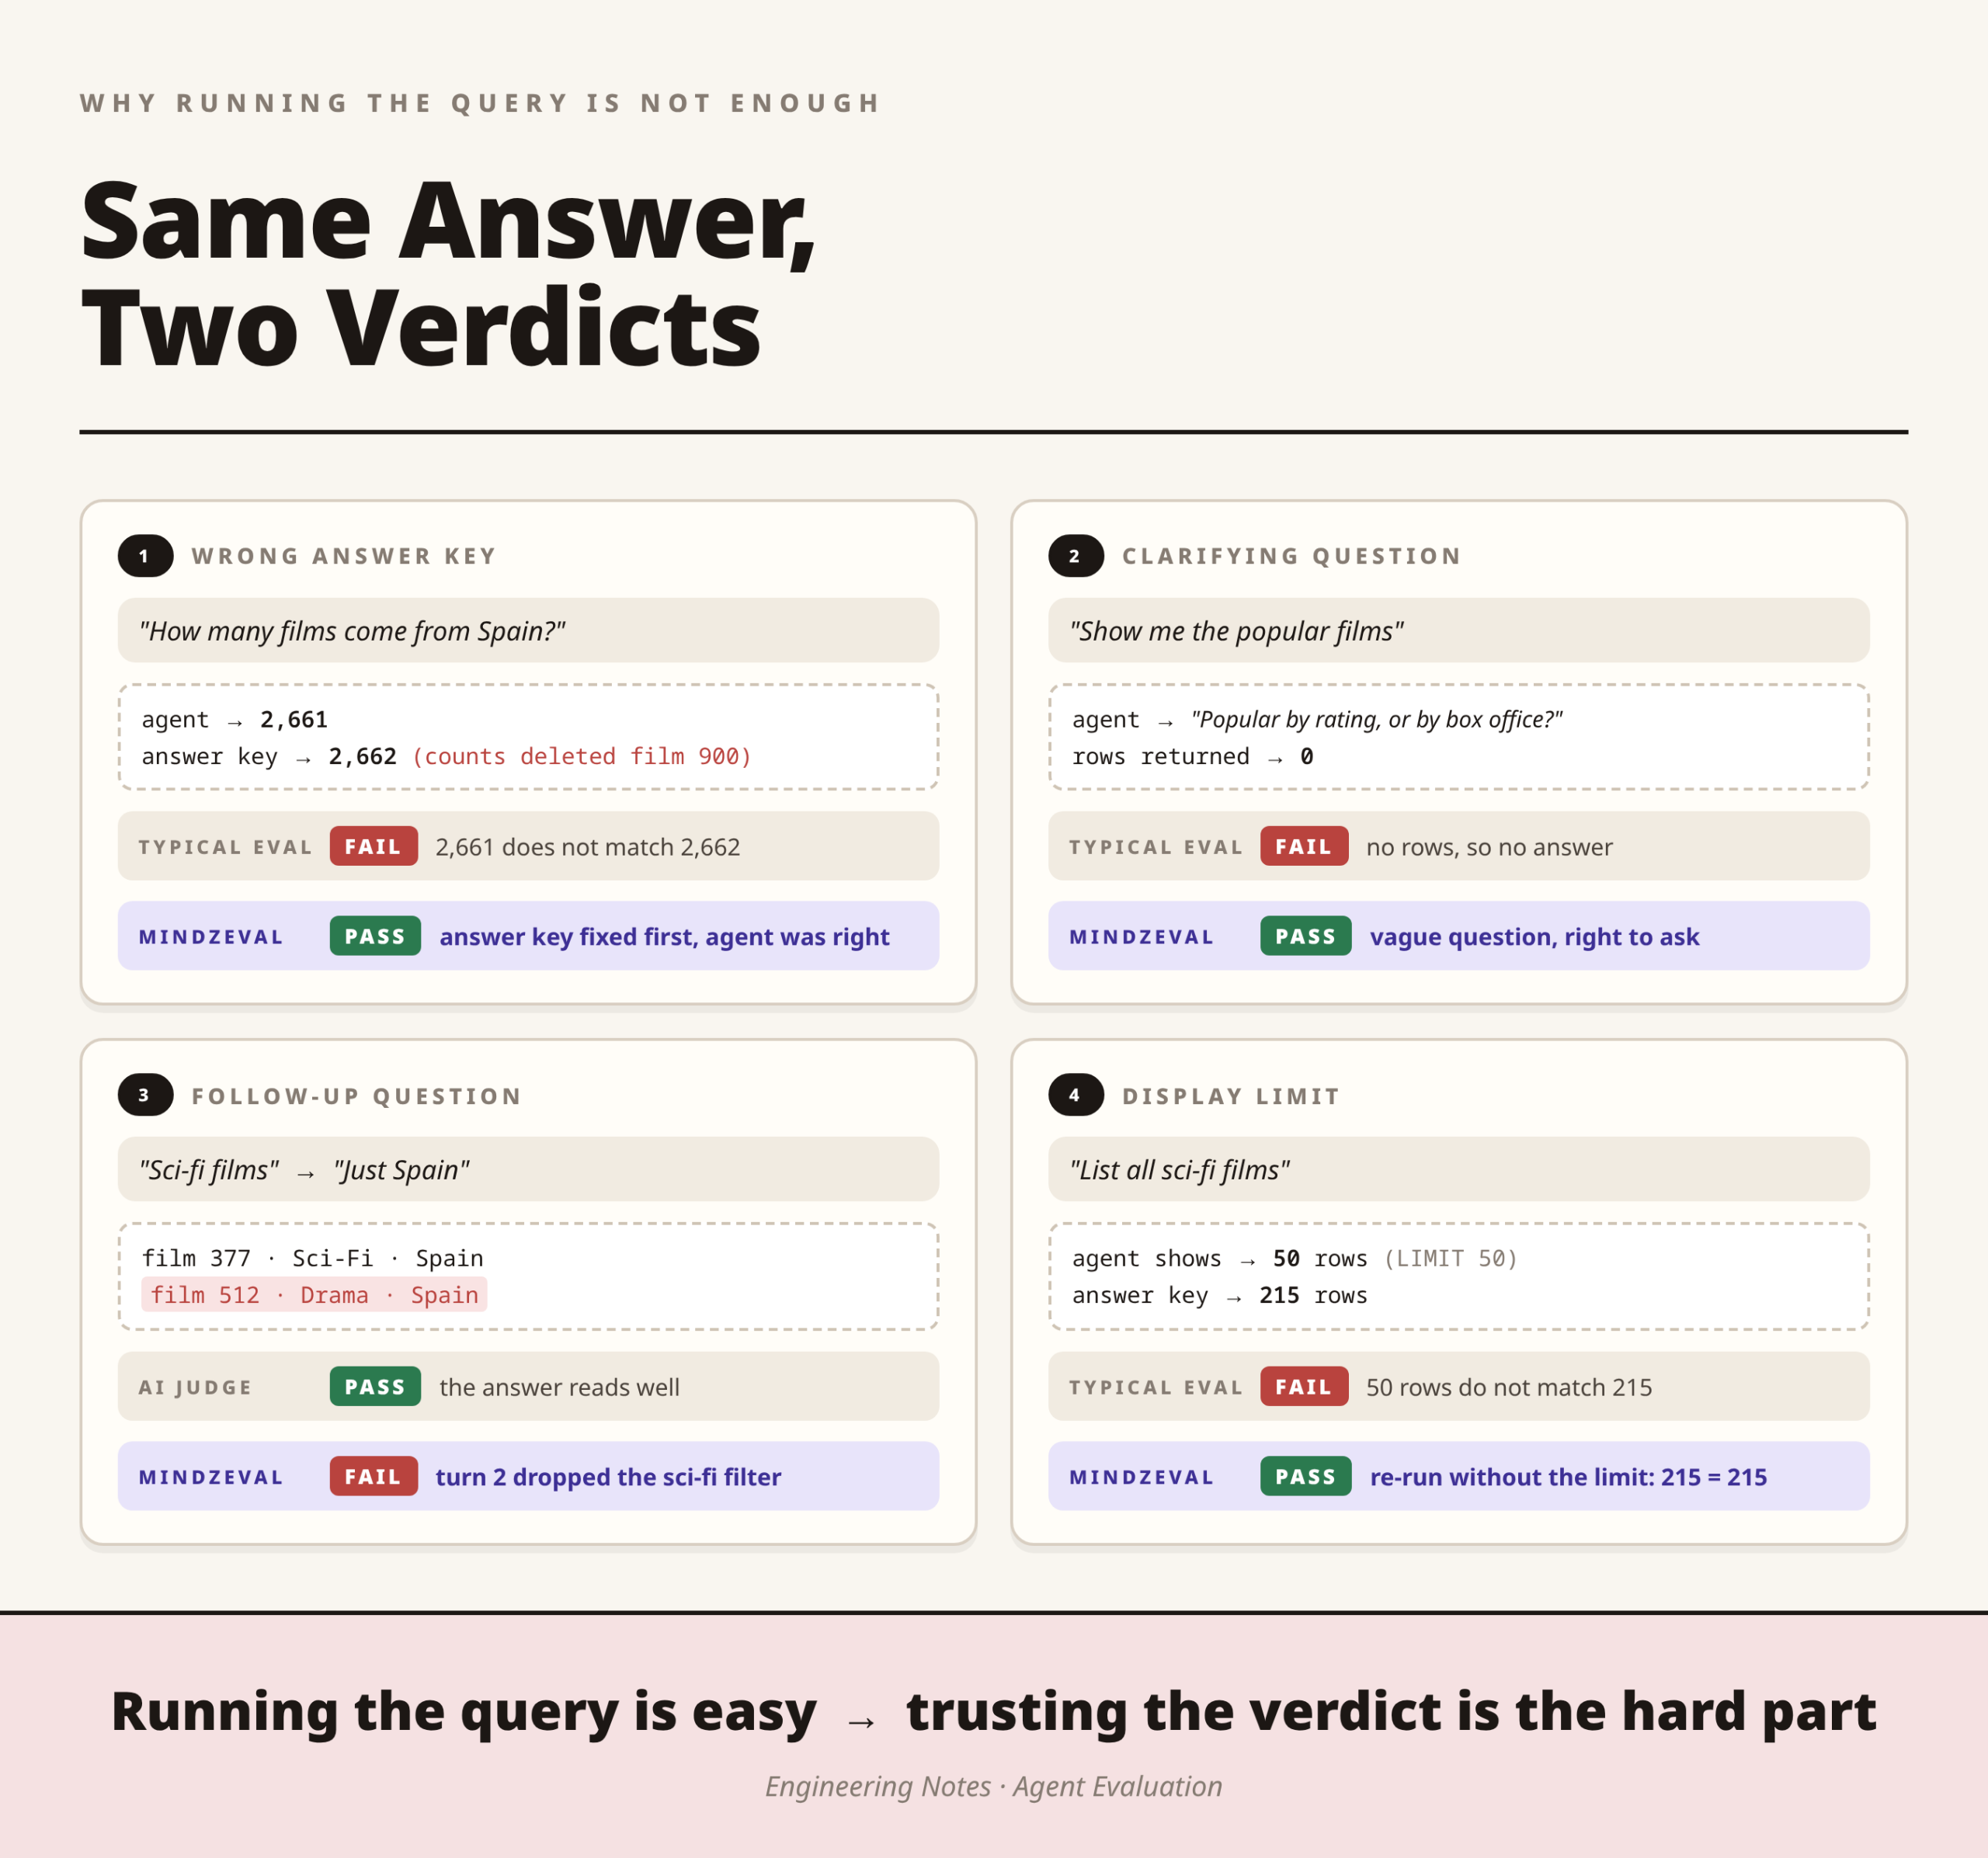
Every eval compares the agent’s answer with a reference answer. However, reference answers can be wrong too. In Part 2, our own reference said 2,662 films came from Spain, while the agent correctly said 2,661.
This is not just our problem. A 2026 study found error rates of 52.8% and 62.8% in the reference answers of two popular Text-to-SQL benchmarks, BIRD Mini-Dev and Spider 2.0-Snow.
- Other tools at most check that a reference answer returns some rows.
- MindzEval tests each reference answer against your database before it grades the agent, so a broken test cannot show up as an agent bug.
2. It scores clarifying questions and refusals both ways
Most eval tools are built to score answers. As a result, they have no clear way to tell a good clarifying question or refusal from a bad one.
MindzEval scores this too. It gives credit when asking or declining was the right move, and marks it down when it was not.
3. It checks the data on every turn of a conversation
Real users ask follow-up questions. For example, someone might ask for sci-fi films and then say “just Spain”. The second answer only makes sense if the agent remembers the first question.
- Most tools either do not test conversations, or they ask an AI judge whether the answers look right.
- MindzEval checks the actual data returned on every turn, so each answer is graded on facts, not on how it reads.
4. It tells a display limit apart from a wrong query
Many agents only show a limited number of rows. For example, our agent showed 50 films when the full answer was 215. A simple row comparison marks that as wrong, even though every film shown was correct.
To avoid this, MindzEval re-runs the query without the limit. That way, it can tell “the agent only showed part of the answer” apart from “the agent wrote the wrong query”.
5. It is one neutral standard for any SQL agent
- It gives the same verdict every time, because it does not use an AI judge by default.
- It works with any framework, so you do not have to rebuild your agent around it.
- It works the same way for every SQL agent, whatever platform or database it runs on.
Because of this, a score from MindzEval means the same thing whichever agent, framework or week it comes from.
Where we are still behind
We want to be honest about this too. The mature platforms are ahead of us on dashboards, comparing runs and tracking trends over time. We are building these now, but for the moment, they do them better.
The short answer
So, why another eval tool? Because for SQL agents, running the query is the easy part. The hard part is trusting the score, and that is the gap MindzEval is built to fill.
Want to know whether your SQL agent is right, not just whether it looks right?
MindzEval is built to give you a number you can trust for your SQL agent. To find out more, call us on +91 85957 97775.
Leave a Reply